# Speech Recognition (ASR) (/docs/en/skills/asr)
Transcribe audio files to text using `coli asr`. It runs entirely on your machine through local speech recognition models, so it needs no ListenHub API key and no internet connection once the models are downloaded.
> **No ListenHub API key required.** This skill is local-only — it does not call the ListenHub API. It needs the `coli` CLI, which is a separate tool from `listenhub`. See [Prerequisites](#prerequisites) below.
Trigger [#trigger]
Invoke this skill with `/asr`, or use any of these phrases:
| Phrase | Language |
| -------------------------------- | -------- |
| `transcribe` / `transcribe this` | English |
| `ASR` | English |
| `转录` / `识别音频` | Chinese |
| `语音转文字` | Chinese |
| `把这段音频转成文字` | Chinese |
Prerequisites [#prerequisites]
This skill depends on the `coli` CLI, not the `listenhub` CLI. Install it once:
```bash
npm install -g @marswave/coli
```
**Optional but recommended:** install `ffmpeg` to support compressed formats (MP4, M4A, AAC, and similar):
```bash
# macOS
brew install ffmpeg
# Ubuntu / Debian
sudo apt install ffmpeg
```
WAV files transcribe without `ffmpeg`. Other formats need it for decoding.
First-run model download [#first-run-model-download]
The recognition models are not bundled with the CLI. On your first transcription, `coli` automatically downloads the model it needs (roughly 60 MB) to `~/.coli/models/`. This happens once per model and takes a moment — the AI tells you it is downloading if the model is not present yet. Every later run reuses the cached model and starts immediately.
After the download, transcription is fully offline. No audio leaves your machine, and no network call is made.
Quick Example [#quick-example]
```
Transcribe this file: meeting.m4a
```
The AI checks prerequisites, reads your config, confirms the model and polish settings, and runs the transcription locally. The result appears directly in the conversation.
Models [#models]
The skill ships with two recognition models. Pick based on the languages in your audio and whether you want extra signals like emotion.
| Model | Languages | Detects emotion / events | Notes |
| ---------------------- | --------------------------------------------- | ------------------------ | -------------------------------------------------------------------- |
| `sensevoice` (default) | Chinese, English, Japanese, Korean, Cantonese | Yes | Recommended for multilingual content or when the language is unknown |
| `whisper-tiny.en` | English only | No | Smaller, English-only model |
Use `sensevoice` unless your audio is reliably English and you want the lighter model. `sensevoice` is the default and the better general-purpose choice — it covers five languages and returns the language, emotion, and audio-event signals described below.
Detected metadata [#detected-metadata]
When you run with JSON output, `sensevoice` returns more than the transcript text. The result includes:
* **`lang`** — the detected spoken language
* **`emotion`** — the detected emotional tone of the speech
* **`event`** — detected non-speech audio events (for example background sounds)
* **`duration`** — the audio length in seconds
The AI surfaces `lang`, `emotion`, and `duration` alongside the transcript, and writes them into the Markdown export header. `whisper-tiny.en` returns the transcript and `duration` but does not produce emotion or event detection.
AI polish [#ai-polish]
Polish is a post-processing pass on the raw transcript, applied by the AI after `coli` returns the text. It is **enabled by default**.
| Mode | What you get |
| ------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| Polish on (default) | The AI rewrites the raw transcript to fix punctuation, remove filler words, and improve readability — without changing meaning, summarizing, or paraphrasing |
| Polish off | The exact raw transcript as returned by the model, unedited |
The raw transcript is always preserved. Even with polish on, you can ask the AI to show the original unedited text. To turn polish off for a single transcription, say so in the request (for example *"transcribe interview\.wav, no polish"*); to change the default, reconfigure the skill.
Output [#output]
The transcript appears inline in the conversation, followed by the detected metadata:
```
Transcription complete
{transcript text}
─────────────────
lang: {lang} · emotion: {emotion} · duration: {duration}s
```
If polish is on, the polished version is shown and marked as AI-refined.
Markdown export [#markdown-export]
After presenting the result, the AI offers to save the transcript as a Markdown file in your current working directory:
```
{audio-filename}-transcript.md
```
The file contains the transcript (the polished version when polish is on) under a front-matter header recording the source file, date, model, duration, and detected language:
```markdown
---
source: meeting.m4a
date: 2026-06-25
model: sensevoice
duration: 312s
lang: zh
---
{transcript text}
```
Configuration [#configuration]
Settings are stored per project in `.listenhub/asr/config.json` and created automatically on first use with sensible defaults (`sensevoice`, polish on). You don't need to configure anything to get started. To change defaults, ask the AI to reconfigure; it walks you through the model and polish choices and saves your answers.
| Setting | Default | Options |
| -------- | ------------ | ------------------------------- |
| `model` | `sensevoice` | `sensevoice`, `whisper-tiny.en` |
| `polish` | `true` | `true`, `false` |
CLI Command [#cli-command]
The skill drives the `coli asr` command. JSON output is used so the AI can read the detected metadata:
```bash
# Transcribe with JSON output (returns text, lang, emotion, event, duration)
coli asr -j --model sensevoice "meeting.m4a"
# English-only, lighter model
coli asr -j --model whisper-tiny.en "talk.wav"
```
Run `coli asr --help` for the current set of flags supported by your installed version.
Composability [#composability]
This skill produces transcript text that you can pass directly to other skills in the same conversation:
* Transcribe a recorded interview, then feed it into [`/podcast`](/docs/en/skills/podcast) as reference material
* Transcribe a voice memo, then use it as input for [`/explainer`](/docs/en/skills/explainer)
See [Composing Skills](/docs/en/skills/guides/composing-skills) for more chained workflows.
API Reference [#api-reference]
None. This skill makes no API calls — it uses the local `coli asr` command only.
# Content Parser (/docs/en/skills/content-parser)
Extract structured content from any URL. Supports articles, YouTube videos, tweets, WeChat posts, PDFs, and more. Use standalone or as a preprocessing step for other skills.
Trigger [#trigger]
Invoke this skill with `/content-parser`, or use any of these phrases:
| Phrase | Language |
| ---------------------------------- | -------- |
| `parse this URL` / `parse this` | English |
| `extract content` / `extract from` | English |
| `解析链接` | Chinese |
| `提取内容` | Chinese |
Requires ListenHub Skills to be installed — see [Getting Started](/docs/en/skills/getting-started).
Quick Example [#quick-example]
```
Parse this article: https://en.wikipedia.org/wiki/Topology
```
The AI extracts the content, returns a preview, and offers to save or use it in another skill.
Supported Sources [#supported-sources]
| Platform | URL patterns | Content type |
| ----------- | ----------------------------------- | -------------------------- |
| YouTube | `youtube.com/watch?v=`, `youtu.be/` | Video transcripts |
| Bilibili | `bilibili.com/video/` | Video transcripts |
| Twitter/X | `twitter.com/`, `x.com/` | Tweets (profile or single) |
| WeChat | `mp.weixin.qq.com/s/` | Public articles |
| PDF | Direct `.pdf` URL | Document text |
| DOCX | Direct `.docx` URL | Document text |
| Images | Direct image URL | OCR / description |
| Any webpage | Any HTTP(S) URL | Article text |
Extraction Options [#extraction-options]
All options are optional. When you don't set them, Content Parser extracts the full article text with default limits. The AI asks whether you want to configure options before extracting, or you can state them in your request ("summarize it", "get the latest 50 tweets").
| Parameter | Description | Default |
| --------------- | --------------------------------------------------- | --------------------- |
| `summarize` | Return a generated summary instead of the full text | `false` |
| `maxLength` | Maximum content length in characters | 100,000 (max 500,000) |
| `twitter.count` | Tweets to fetch — Twitter/X profiles only | 20 (max 100) |
**Summarize** — set this when you want the gist rather than the full document. Useful for long articles or videos where you'll feed the result into another skill. When enabled, the response carries the summary in place of the full `content`.
**Max length** — caps how much text is returned and billed. Lower it to trim a very long page; the default 100,000 characters covers most articles, and you can raise it up to 500,000.
**Platform handling** — extraction adapts to the source automatically:
* **YouTube / Bilibili** — pulls the video transcript, not the page chrome.
* **Twitter/X** — a single tweet URL returns that tweet; a profile URL returns the most recent tweets, controlled by `twitter.count` (default 20, up to 100).
* **PDF / DOCX** — extracts document text from the direct file URL.
* **Images** — returns OCR text or a description for direct image URLs.
Common Use Cases [#common-use-cases]
Standalone Extraction [#standalone-extraction]
```
Extract the content from this YouTube video: https://youtube.com/watch?v=...
```
Summarize a Long Article [#summarize-a-long-article]
```
Parse this report and just give me a summary: https://example.com/2026-outlook
```
Fetch Tweets from a Profile [#fetch-tweets-from-a-profile]
```
Extract the latest 50 tweets from https://x.com/elonmusk
```
Parse + Generate [#parse--generate]
Combine with other skills in a single conversation:
```
Parse this article and turn it into a podcast: https://example.com/article
```
```
Extract this YouTube video and make an explainer video from it
```
See the [Composing Skills](/docs/en/skills/guides/composing-skills) guide for more workflow examples.
Output [#output]
After extraction completes, the AI receives the following structured data:
* **content** — full extracted text, up to `maxLength` (default 100,000 characters)
* **metadata** — title, author, publication date, and other page metadata
* **references** — URLs referenced in the content
* **summary** — returned in place of `content` when `summarize` was enabled
By default the AI also saves two files to your current working directory, named from the extracted title:
* `{slug}.md` — the extracted content as Markdown, ready to read or edit
* `{slug}.json` — the full raw API response, including metadata, references, and credits
It then shows a preview of the first part of the content and offers to pass it into another skill, such as [`/podcast`](/docs/en/skills/podcast) or [`/tts`](/docs/en/skills/tts).
Limitations [#limitations]
* Paywalled content may not be accessible
* JavaScript-rendered content may be partially extracted
* Very long content may be truncated at `maxLength`
* Some platforms may block automated access
Credits [#credits]
Content extraction is billed based on extracted content length:
| Rule | Details |
| -------------- | ------------------------------------------------------------------------------------------ |
| Pre-deduction | 5 credits reserved when extraction starts |
| Rate | 100 credits per 100,000 characters; if actual is less than 5, the actual amount is charged |
| Default limit | 100,000 characters (100 credits) |
| Maximum limit | 500,000 characters (500 credits) |
| Failure refund | All pre-deducted credits refunded on failure |
API Reference [#api-reference]
See the [Content Extraction API reference](/docs/en/openapi/api-reference/content-extract) for technical details.
# Creator (/docs/en/skills/creator)
Creator is a [ListenHub Skill](/docs/en/skills/getting-started) — an AI agent workflow with access to file system, web browsing, image generation, and other tools. Give it a topic, URL, or audio file, and it produces a complete content package — WeChat articles with illustrations, Xiaohongshu image cards, or narration scripts with optional TTS. All outputs land in a local folder: text, images, and metadata, ready to publish.
Quick Example [#quick-example]
**WeChat article from a URL:**
```
Write a WeChat article based on this link https://mp.weixin.qq.com/s/xxx
```
Creator extracts the source, picks an illustration preset, then shows a summary and waits for your confirmation:
```
Platform: WeChat
Source: https://mp.weixin.qq.com/s/xxx (article extraction)
Prototype: Insight commentary
Preset: Flat illustration
Output: ./ai-trends-wechat/
APIs used: Content Extraction, Image Generation
```
Once you confirm, Creator runs the full pipeline. After a few minutes, you get:
```
ai-trends-wechat/
├── article.md # Full article with image references
├── images/
│ ├── cover.jpg # AI-generated cover
│ ├── section-1.jpg
│ └── section-2.jpg
└── meta.json # Title, summary, tags
```
**Xiaohongshu cards from a topic:**
```
Create Xiaohongshu cards about must-have items for solo apartment living
```
```
solo-living-xiaohongshu/
├── cards/
│ ├── 01-cover.jpg
│ ├── 02-page.jpg
│ ├── ...
│ └── prompts.json
├── long-text.md # Post text with hashtags
└── meta.json
```
How Creator Writes [#how-creator-writes]
Creator does not generate text in a single pass. Each platform runs a structured writing process before any image or audio is produced.
1. Match a prototype [#match-a-prototype]
Creator reads the platform's prototype catalog and auto-matches the best-fit narrative structure for your material — for example "insight commentary", "step-by-step guide", or "personal story". It shows the recommendation and lets you switch to another prototype.
2. Write with the writing engine [#write-with-the-writing-engine]
Creator drafts the content using its built-in writing engine, applying the selected prototype's structure and your active style rules. This is where the headline, hook, body, and section breaks are produced.
3. Self-review and revise [#self-review-and-revise]
Creator runs a multi-level quality review (L1–L4) over the draft — checking structure, clarity, tone, and platform fit — and revises before finalizing. You receive the revised result, not the first draft.
Platforms [#platforms]
**WeChat:**
Creator writes a structured, long-form WeChat article with clear headings and concise paragraphs, and generates a cover image plus section illustrations to match.
Three visual presets are available for illustrations — Flat, Watercolor, and Photo-Realistic. Creator picks one based on your topic and shows it in the confirmation summary, or you can specify: "use the watercolor preset".
**Xiaohongshu:**
Creator produces Xiaohongshu content in two formats: image cards (5–8 designed pages with bold text and visuals) and a long-form post (hook-first, with hashtags). You get both by default, or can request just one.
Ten visual presets are available for cards, ranging from minimal to retro to pop. Creator auto-selects based on content, or you can specify: "use the Notion preset". In long-text-only mode, no cards or images are generated and no preset is chosen.
**Narration:**
Creator writes a conversational, spoken-word script with natural pacing and clear structure. Optionally, it generates a TTS audio file using an AI voice. Narration uses no visual presets.
Choosing a Preset [#choosing-a-preset]
For WeChat and Xiaohongshu (when images are generated), Creator selects the illustration or card preset **before** the confirmation gate, so the chosen style appears in the summary you approve. If you named a preset in your request (e.g., "use watercolor"), Creator uses it directly; otherwise it recommends the best match for your topic and lets you pick.
Presets are skipped entirely for the Narration template and for Xiaohongshu in long-text-only mode.
Supported Inputs [#supported-inputs]
| Input | Example | What Creator does |
| ------------------ | -------------------------------- | ------------------------------------------------------------- |
| URL (article/page) | `https://mp.weixin.qq.com/s/xxx` | Extracts content via API, uses it as source material |
| URL (audio/video) | A YouTube or Bilibili link | Downloads and transcribes locally, writes from the transcript |
| Local audio file | `meeting.mp3` | Transcribes with local ASR, writes from the transcript |
| Text | A pasted paragraph or document | Uses the text as source material |
| Topic | "AI in education" | Generates content from scratch |
> Audio/video transcription runs locally via [`coli`](https://www.npmjs.com/package/@marswave/coli). Install with `npm i -g @marswave/coli`. No API key needed for transcription.
When you give Creator only a topic or a few keywords, it first checks the angle against a quality filter — is it interesting, informative, and relatable — and proposes sharper alternatives if the topic is too thin or vague before it starts writing.
API Key [#api-key]
Image generation, content extraction from URLs, and TTS require a [ListenHub API key](https://listenhub.ai/settings/api-keys). Creator checks at the confirmation step and walks you through setup if needed.
Text-only pipelines (e.g., topic → narration script without audio) work without an API key.
Style Learning [#style-learning]
**Learn from a reference**: Share an article, post, or script you like — say "use this as a style reference". Creator extracts 3–5 concrete style directives (sentence length, tone, formatting habits), shows them for you to confirm or edit, and applies them to this generation. It then asks whether to save them for future use. If you share only a reference with no material (e.g., "just learn this article's style"), Creator extracts and saves the style directly without generating content.
**Set rules directly**: After reviewing output, tell Creator what to adjust. It saves these as persistent style rules:
* "remember: keep WeChat paragraphs short"
* "narration scripts should be under 800 words"
* "小红书少用 emoji"
How style rules are stored [#how-style-rules-are-stored]
Style rules live as plain Markdown files under your current working directory, one directive per line, one file per platform:
```
.listenhub/creator/styles/
├── wechat.md
├── xiaohongshu.md
└── narration.md
```
You can edit these files directly. When writing, Creator applies style in priority order — directives from the current reference override saved platform rules, which override the built-in platform baseline. If a platform file does not exist, no custom style is applied. To reset: "reset WeChat style" or "重置公众号风格偏好".
Trigger [#trigger]
Type `/creator` to invoke directly, or describe what you want in natural language — Creator activates when it recognizes a content generation request (e.g., "write a WeChat article", "帮我写篇公众号").
API Reference [#api-reference]
See the [OpenAPI documentation](/docs/en/openapi) for details on the underlying content extraction, image generation, and TTS endpoints.
# Explainer Video (/docs/en/skills/explainer)
Generate explainer videos that pair a single narrator's voiceover with AI-generated visuals. Best for product introductions, concept explanations, and tutorials. You can produce a full narrated video, or just the script text first to review before committing to video.
Trigger [#trigger]
Invoke this skill with `/explainer`, or use any of these phrases:
| Phrase | Language |
| ------------------------- | -------- |
| `explainer video` | English |
| `explain this as a video` | English |
| `tutorial video` | English |
| `解说视频` | Chinese |
| `解释一下 XXX(视频形式)` | Chinese |
Requires ListenHub Skills to be installed — see [Getting Started](/docs/en/skills/getting-started).
Quick Example [#quick-example]
```
Make an explainer video introducing Claude Code
```
The AI confirms the language, style, and output type through a short Q\&A, then writes the script, selects a voice, generates visuals for each section, and produces the video.
> Explainer and [Slides](/docs/en/skills/slides) both turn a topic into visual content. Use **Explainer** for a continuous narrated video. Use **Slides** for a deck of discrete slides where narration is optional and off by default. Explainer uses exactly **one** speaker. If you want audio without visuals, use [Speech](/docs/en/skills/tts) or [Podcast](/docs/en/skills/podcast).
Modes [#modes]
Explainer supports two modes. Set with `--mode`; the default is `info`.
**Info:**
Factual, structured presentation. Clear progression: intro, key points, summary.
Best for product introductions, feature walkthroughs, and educational content.
**Story:**
Narrative storytelling approach. Engaging flow: hook, build-up, climax, resolution.
Best for brand stories, case studies, and emotional topics.
| Intent | Recommended mode |
| ------------------------ | ---------------- |
| "Introduce this product" | `info` |
| "Explain how X works" | `info` |
| "Tell the story of X" | `story` |
| "Make an engaging video" | `story` |
| No preference stated | `info` (default) |
> Explainer accepts only `info` or `story`. The `slides` mode belongs to the [Slides](/docs/en/skills/slides) skill — use that instead for a slide deck.
Options [#options]
The AI collects these through a short Q\&A before generating. You can also pass them directly when driving the `listenhub explainer create` command yourself.
| Option | CLI flag | Values | Default |
| --------------- | ---------------- | ------------------------------------- | --------------------------------- |
| Topic / content | `--query` | Free text, or pair with a source | Required |
| Source URL | `--source-url` | A URL to summarize (repeatable) | None |
| Source text | `--source-text` | Reference text (repeatable) | None |
| Mode | `--mode` | `info`, `story` | `info` |
| Language | `--lang` | `en`, `zh`, `ja` | Auto-detected from the topic |
| Speaker | `--speaker` | A voice name | Built-in default for the language |
| Speaker ID | `--speaker-id` | A speaker inner ID | Resolved from `--speaker` |
| Text only | `--skip-audio` | Present = script only, no audio/video | Off (full video) |
| Image size | `--image-size` | `2K`, `4K` | `2K` |
| Aspect ratio | `--aspect-ratio` | `16:9`, `9:16`, `1:1` | `16:9` |
| Visual style | `--style` | Free text style hint for the visuals | None |
Language [#language]
`--lang` accepts `en`, `zh`, or `ja`. If omitted, the language is auto-detected from your topic text. If you set a default language in config, the AI pre-fills it and skips the question.
Speaker [#speaker]
Explainer uses exactly **one** speaker. If you do not name a speaker, the AI uses the built-in default voice for the chosen language. To use a different voice, ask to change it and the AI fetches the available voices — speaker IDs are never hardcoded.
Image size and aspect ratio [#image-size-and-aspect-ratio]
`--image-size` controls the resolution of generated visuals (`2K` or `4K`; default `2K`). `--aspect-ratio` controls the video shape: `16:9` (default, landscape), `9:16` (vertical), or `1:1` (square).
Source URL or text [#source-url-or-text]
To build an explainer from existing material, provide a reference. The AI passes a page link as `--source-url` or pasted content as `--source-text` alongside your `--query`, and the script is generated from that content. Both flags are repeatable.
Output type [#output-type]
Choose between a full narrated video or just the script text.
**Text + Video:**
The default. Generates the narration script, then produces a video with AI-generated visuals matching each section.
```bash
listenhub explainer create \
--query "Introduce Claude Code: what it is, key features, and how to get started" \
--mode info \
--lang en \
--speaker "Mars" \
--image-size 2K \
--aspect-ratio 16:9 \
--timeout 600 \
--json
```
Typical generation time: 5–10 minutes.
**Text only:**
Pass `--skip-audio` to generate just the narration script — no audio and no video. Useful for reviewing content before committing to a full render.
```bash
listenhub explainer create \
--query "Introduce Claude Code" \
--mode info \
--lang en \
--skip-audio \
--json
```
Typical generation time: 2–3 minutes.
Output [#output]
When generation finishes, the AI presents the result based on your configured output mode.
Online episode [#online-episode]
Every run produces an online episode you can view and share:
```
https://listenhub.ai/app/explainer/{episodeId}
```
The full narration script is available in the episode detail.
Result fields [#result-fields]
The `create` command returns the episode detail. The shape depends on the output type:
| Output type | Returned links |
| -------------------------- | ------------------------------------------------------------------------------------- |
| Text + Video | `videoUrl` (the rendered video), `audioUrl` (the voiceover track), `credits` |
| Text only (`--skip-audio`) | Script only — no `audioUrl` or `videoUrl`; view the script at the online episode link |
With `--json`, the command prints the full episode detail (including `id` / `episodeId`, `title`, and `processStatus`). Without `--json`, it prints a compact summary.
Download [#download]
If your output mode is `download` or `both`, the AI also saves files into the current working directory:
* **Text only** — a script file, e.g. `claude-code-explainer.md`
* **Text + Video** — a `claude-code-explainer/` folder containing `script.md` and `audio.mp3`
The online episode link is always shown, regardless of output mode.
> Credit cost varies by script length, image size, and whether video is rendered, and is shown in the result after generation. There is no separate estimate command for explainer — generate text only first if you want to review scope before rendering video.
Tips [#tips]
* Detailed descriptions in your prompt produce richer visuals.
* One concept per section works best for clarity.
* Request text only first to review the script, then generate the video.
* Use `--aspect-ratio 9:16` for vertical social formats and `4K` for higher-resolution visuals.
Related [#related]
- **Slides** -- Slide deck with optional narration [/docs/en/skills/slides](/docs/en/skills/slides)
- **Image Generation** -- Generate standalone AI images [/docs/en/skills/image](/docs/en/skills/image)
- **Podcast** -- Audio-only multi-speaker discussion [/docs/en/skills/podcast](/docs/en/skills/podcast)
API Reference [#api-reference]
The OpenAPI equivalent is the storybook surface (same backend, different naming). See the [Explainer Video API reference](/docs/en/openapi/api-reference/explainer-video) for endpoint details and code examples.
# Getting Started (/docs/en/skills/getting-started)
This guide walks you through installation, configuration, and your first content generation.
Prerequisites [#prerequisites]
* **AI coding tool** with [Agent Skills](https://vercel.com/blog/skills) support — Claude Code, Cursor, Windsurf, OpenCode, or similar
* **ListenHub API Key** — [create a free account](https://listenhub.ai) first, then [get your API key](https://listenhub.ai/settings/api-keys)
* **curl and jq** — usually pre-installed; the AI installs them automatically if missing
Installation [#installation]
**Vercel skills.sh (Recommended):**
```bash
npx skills add marswaveai/skills
```
**Open Agent Skills:**
```bash
bunx add-skill marswaveai/skills
```
After installation, the skill files are added to your project directory automatically.
See [Updating Skills](/docs/en/skills/updating) for update instructions and AI Agent automation steps.
API Key Setup [#api-key-setup]
On first use, the AI detects that no API key is configured and guides you through setup:
1. Open [ListenHub API Key Settings](https://listenhub.ai/settings/api-keys) (login required)
2. Create a new API key or copy an existing one (format: `lh_sk_...`)
3. Paste the key when prompted by the AI
The key is saved automatically. You only need to do this once.
> You can also set the key manually as an environment variable:
>
> ```bash
> export LISTENHUB_API_KEY="lh_sk_..."
> ```
>
> Add this line to `~/.zshrc` (macOS) or `~/.bashrc` (Linux), then run `source ~/.zshrc`.
Your First Generation [#your-first-generation]
Try one of these prompts to verify everything works:
| Example | What happens |
| ----------------------------------- | ----------------------------------- |
| `Make a podcast about AI trends` | Generates a podcast episode |
| `Read this aloud: Hello world` | Converts text to speech audio |
| `Generate an image: a cat in space` | Creates an AI-generated image |
| `Transcribe this file: meeting.m4a` | Transcribes audio to text (offline) |
The AI handles voice selection, content scripting, and generation automatically. You'll receive a link to listen, watch, or download when it's done.
Retrieving Results [#retrieving-results]
After generation completes:
* **Podcast & Speech** — the AI displays a link inline by default. To save locally, set output mode to `download` or `both` during setup, or say "download audio"
* **Explainer Video** — the AI provides a link inline; download is available on request
* **Images** — displayed inline by default; saved to `.listenhub/image-gen/` if output mode is `download`
* **Transcripts** — available in the episode detail on [listenhub.ai](https://listenhub.ai)
Example Prompts [#example-prompts]
| Goal | Prompt |
| --------------------------- | -------------------------------------------------- |
| Chinese podcast, quick mode | `Make a podcast about XXX, in Chinese` |
| English podcast, deep mode | `Make a podcast about XXX, in English, mode: deep` |
| Explainer video | `Make an explainer video about XXX` |
| Text-to-speech | `Read this aloud: [your text]` |
| Image generation | `Generate an image: XXX, 16:9, 2K` |
Default Behavior [#default-behavior]
When you don't specify certain parameters, the AI uses sensible defaults:
| Parameter | Default |
| ------------ | ----------------------------------------------- |
| Language | Auto-detected from your input |
| Podcast mode | Quick + solo (when only a topic is given) |
| Voice | First available voice for the detected language |
| Speech mode | FlowSpeech `direct` (reads text as-is) |
Next Steps [#next-steps]
- **Explore Skills** -- Learn what each skill can do and how to use it. [/docs/en/skills/podcast](/docs/en/skills/podcast)
- **Composing Skills** -- Chain skills together for complex workflows. [/docs/en/skills/guides/composing-skills](/docs/en/skills/guides/composing-skills)
For more examples and an illustrated walkthrough, see the [Way to AGI Workshop Tutorial (Feishu)](https://waytoagi.feishu.cn/wiki/Saa3wVV5PihHpPkfNMgcMeAQn4f).
# Help & FAQ (/docs/en/skills/help)
Common Questions [#common-questions]
API Key [#api-key]
**Q: I'm seeing "API Key not configured"**
The AI will guide you through setup on first use. If you skipped it, set manually:
1. Visit [ListenHub API Key Settings](https://listenhub.ai/settings/api-keys)
2. Create or copy your API Key (starts with `lh_sk_`)
3. Run: `export LISTENHUB_API_KEY="lh_sk_your_key_here"`
4. Add the line to `~/.zshrc` or `~/.bashrc` to persist
**Q: Does the free plan support Skills?**
Yes. All users can obtain an API Key from the [API Key Settings page](https://listenhub.ai/settings/api-keys) and use Skills.
Generation [#generation]
**Q: Generation is taking too long?**
Podcasts typically take 2–3 minutes, explainer videos 3–5 minutes. If it exceeds 10 minutes, the server may be busy. Ask "ready yet?" anytime to check status, or resubmit.
**Q: How do I improve generation quality?**
A few directions:
* Be specific with topics ("Three core paradigm shifts in AI coding" works better than "AI coding")
* Specify mode: `deep` (longer, detailed) or `quick` (concise)
* Specify language explicitly in the request
* Use [Script-First Podcast](/docs/en/skills/advanced/script-first-podcast) to review the script before audio generation
**Q: Can I use my own script to generate a podcast?**
Yes. Use the stage-two feature of [Script-First Podcast](/docs/en/skills/advanced/script-first-podcast) to supply a custom script JSON and generate audio directly. Alternatively, use [Multi-Voice Scripts](/docs/en/skills/advanced/tts) for precise per-line voice assignment.
Images [#images]
**Q: Must reference images be uploaded to an image host?**
Yes. Reference images need a publicly accessible URL. Local file paths are not supported. Recommended free hosts: [imgbb.com](https://imgbb.com), [sm.ms](https://sm.ms), [postimages.org](https://postimages.org). Copy the **direct link** after upload (typically ending in `.jpg` or `.png`).
**Q: Where are generated images saved?**
`~/Downloads` by default, named `listenhub-{date}-{time}-{id}.jpg`.
Voices [#voices]
**Q: How do I see the available voice list?**
Ask the AI directly — for example, "What English voices are available?" or "Show me the voice list." The AI will call the voice query API and return the full list.
**Q: Can I use my own cloned voice?**
If voice cloning has been completed on the ListenHub platform, the cloned voice will appear in the available voice list and can be used directly.
***
Common Errors [#common-errors]
Error: Invalid JSON format [#error-invalid-json-format]
When using TTS multi-voice scripts or custom podcast scripts, ensure valid JSON structure:
```json
{
"scripts": [
{ "content": "Line content", "speakerId": "voice-id" }
]
}
```
curl: command not found or jq: command not found [#curl-command-not-found-or-jq-command-not-found]
Skills depend on `curl` and `jq`. In most cases the AI will install them automatically. If not, install manually:
```bash
# macOS
brew install curl jq
# Ubuntu/Debian
sudo apt install curl jq
```
Task stuck on "processing" for a long time [#task-stuck-on-processing-for-a-long-time]
Possible causes: server queue or network timeout. Try:
1. Wait 1–2 minutes and check the status again
2. If it persists beyond 10 minutes, resubmit the generation request
General troubleshooting [#general-troubleshooting]
If something unexpected happens, re-run the installation command first. It always pulls the latest version and may already include a fix:
```bash
npx skills add marswaveai/skills
```
***
Ask AI for Everything [#ask-ai-for-everything]
If the above doesn't cover the issue, ask in natural language. The AI knows everything ListenHub Skills can do:
> "What can ListenHub do"
 Contact Support [#contact-support]
For further assistance, reach out to `support@marswave.ai`.
# Image Generation (/docs/en/skills/image)
Generate AI images from text descriptions. Choose between a higher-quality `pro` model and a
faster, cheaper `flash` model, pick a resolution and aspect ratio, and optionally pass reference
images for style guidance. Images are returned as local files or displayed inline.
Trigger [#trigger]
Invoke this skill with `/image-gen`, or use any of these phrases:
| Phrase | Language |
| --------------------------------------- | -------- |
| `generate an image` / `generate image` | English |
| `draw` / `visualize` / `create picture` | English |
| `生成图片` / `画一张` | Chinese |
| `AI图` / `配图` | Chinese |
Requires ListenHub Skills to be installed — see [Getting Started](/docs/en/skills/getting-started).
Quick Example [#quick-example]
```
Generate an image: cyberpunk city at night, 16:9, 2K
```
The AI collects your preferences one question at a time, summarizes them for confirmation, and then
generates the image.
Parameters [#parameters]
| Parameter | Options | Default |
| ---------------- | ----------------------------------------------------------------------------------------------------------------------------------------------- | ------- |
| Model | 🍌 `pro` (`gemini-3-pro-image`, higher quality, recommended), ⚡️ `flash` (`gemini-3.1-flash-image`, faster and cheaper, unlocks extreme ratios) | — |
| Resolution | `1K`, `2K` (recommended), `4K` | — |
| Aspect ratio | `16:9`, `1:1`, `9:16`, `2:3`, `3:2`, `3:4`, `4:3`, `21:9`; `flash` also supports `1:4`, `4:1`, `1:8`, `8:1` | — |
| Reference images | Up to 5, via local file or image URL | None |
Choosing a Model [#choosing-a-model]
Both models are Google Gemini image models. Pick based on quality versus speed and which aspect
ratios you need.
| Model | Model ID | Use it when |
| ---------- | ------------------------ | ------------------------------------------------------------------------------------------------------ |
| 🍌 `pro` | `gemini-3-pro-image` | You want the highest quality and most detail. Recommended default. |
| ⚡️ `flash` | `gemini-3.1-flash-image` | You want faster, cheaper generation, or you need an extreme aspect ratio (`1:4`, `4:1`, `1:8`, `8:1`). |
The four extreme ratios — `1:4` (narrow portrait), `4:1` (wide landscape), `1:8` (extreme portrait),
and `8:1` (panoramic) — are available **only** on the `flash` model. The eight standard ratios work
on both models.
> Don't hardcode credit costs — they depend on model, resolution, and account. To see the cost before
> generating, check the [`estimate-credits` endpoint](/docs/en/openapi/api-reference/image-generation#estimate-credits).
Writing Good Prompts [#writing-good-prompts]
A good prompt covers these elements:
1. **Subject** — what is in the image
2. **Style** — art style or visual treatment
3. **Composition** — how elements are arranged
4. **Lighting/Mood** — atmosphere and time of day
5. **Quality** — detail level and rendering quality
Examples [#examples]
**Basic:**
```
a cat sitting on a windowsill
```
**Better:**
```
a fluffy orange tabby cat sitting on a sunny windowsill, warm afternoon light, cozy interior, highly detailed, photorealistic
```
Style Keywords [#style-keywords]
| Style | Keywords |
| -------------- | ------------------------------------------------------------- |
| Photorealistic | photorealistic, highly detailed, 8K, professional photography |
| Cyberpunk | neon lights, futuristic, dystopian, rain-slicked streets |
| Ink painting | Chinese ink painting, traditional art style, brush strokes |
| Watercolor | watercolor painting, soft edges, flowing colors |
| Anime | anime style, Japanese animation, cel shading |
| Minimalist | minimalist, clean lines, simple composition, white space |
> Always write prompts in **English** — the image model is trained on English descriptions. If you
> describe in Chinese, the AI translates automatically.
Prompt Enrichment [#prompt-enrichment]
The AI passes your prompt through unchanged by default. It only offers to enrich the prompt when:
* The prompt is very short (a few words), **and**
* You haven't asked for verbatim generation.
When you accept enrichment, the AI adds style, lighting, and composition detail, then shows you the
expanded prompt before submitting. For example, "cyberpunk" becomes "neon lights, futuristic,
dystopian, rain-slicked streets."
The AI never rewrites a prompt that is already long, detailed, or structured — it treats you as
experienced. It also leaves the prompt exactly as written when you say something like "use this
prompt exactly."
Reference Images [#reference-images]
Reference images guide the AI on **style**, not content. Your prompt still controls what appears in
the image. You can supply up to 5 references, mixing local files and URLs in one request.
Supported formats: `jpg`, `png`, `webp`, `gif`. Max 10 MB per file.
Using Local Files [#using-local-files]
The skill accepts local file paths directly. Provide the path (for example `./sketch.png`) when the
AI asks about references — it uploads the file for you. No image hosting needed.
Using Image URLs [#using-image-urls]
1. Upload your reference to an image hosting service ([imgbb.com](https://imgbb.com), [sm.ms](https://sm.ms), [postimages.org](https://postimages.org))
2. Copy the direct image URL (ending in `.jpg`, `.png`, `.webp`, or `.gif`)
3. Provide the URL when the AI asks about references
You can mix local files and URLs in the same request — for example one local sketch plus one hosted
photo.
Using Base64 Inline Data (API) [#using-base64-inline-data-api]
When calling the [Image Generation API](/docs/en/openapi/api-reference/image-generation) directly,
you can also provide reference images as base64-encoded data via the `inlineData` field — no image
hosting required. This is useful for programmatic workflows where you already have the image in
memory.
> Each reference image must use exactly one of `fileData` (URL) or `inlineData` (base64), not both. See
> the [API reference](/docs/en/openapi/api-reference/image-generation) for request format and code
> examples.
Output [#output]
Output behavior follows the `outputMode` set during config:
* **`inline` (default)** — the image is displayed directly in the conversation
* **`download`** — saved to `.listenhub/image-gen/YYYY-MM-DD-{id}/` in the current project
* **`both`** — displayed inline and saved locally
The output mode can be changed at any time by saying "reconfigure" when the AI shows your current
config.
API Reference [#api-reference]
See the [Image Generation API reference](/docs/en/openapi/api-reference/image-generation) for
endpoint details, request parameters, the provider/model matrix, and code examples.
# ListenHub Skills (/docs/en/skills)
You have ideas worth sharing. Install ListenHub Skills and let your AI Agent turn them into content people actually want to listen to and watch — no editing skills required.
Quick Install [#quick-install]
```bash
npx skills add marswaveai/skills
```
How It Works [#how-it-works]
1. Install & Configure [#install--configure]
Run the install command above and set your [API key](https://listenhub.ai/settings/api-keys). The AI guides you through setup on first use.
2. Describe What You Want [#describe-what-you-want]
Tell the AI what to create in natural language. For example: *"Make a podcast about quantum computing"* or *"Turn this article into an explainer video"*.
3. Get Your Content [#get-your-content]
The AI handles everything — scripting, voice selection, generation, and delivery. You get the actual content — a podcast episode, a video, or an image — along with a link to listen, watch, or download.
Choose a Skill [#choose-a-skill]
- **ListenHub Voice** -- End-to-end audio: narration, sound effects, multi-voice dialogue, voice cloning, or image-to-audio. [/docs/en/skills/listenhub-voice](/docs/en/skills/listenhub-voice)
- **Podcast** -- Solo narration, two-host dialogue, or debate. From any topic, URL, or text. [/docs/en/skills/podcast](/docs/en/skills/podcast)
- **Explainer Video** -- Narrated video with AI-generated visuals. Ideal for product intros and concept explainers. [/docs/en/skills/explainer](/docs/en/skills/explainer)
- **TTS** -- Text-to-speech with natural voices. Single voice or multi-character dialogue scripts. [/docs/en/skills/tts](/docs/en/skills/tts)
- **Speech Recognition (ASR)** -- Transcribe audio files to text. Runs fully offline — no API key required. [/docs/en/skills/asr](/docs/en/skills/asr)
- **Image Generation** -- AI images from text prompts. Optional reference images for style guidance. [/docs/en/skills/image](/docs/en/skills/image)
- **Music** -- Generate, remix, extend, and analyze AI music — songs, instrumentals, soundtracks, stems, and lyrics. [/docs/en/skills/music](/docs/en/skills/music)
- **Video Generation** -- AI videos from text, images, or reference media — with image-to-video, editing, and lip sync. [/docs/en/skills/video-gen](/docs/en/skills/video-gen)
- **Slides** -- Slide decks with AI-generated visuals from a topic, URL, or text, with optional voice narration. [/docs/en/skills/slides](/docs/en/skills/slides)
- **Content Parser** -- Extract structured content from any URL — articles, YouTube, tweets, PDFs, and more. [/docs/en/skills/content-parser](/docs/en/skills/content-parser)
- **Creator** -- Turn any idea into platform-ready content — WeChat articles, Xiaohongshu posts, or narration scripts with AI images. [/docs/en/skills/creator](/docs/en/skills/creator)
Combine Skills [#combine-skills]
Skills work together. Parse a YouTube video, turn it into a podcast, then generate cover art — all in one conversation.
See the [Composing Skills](/docs/en/skills/guides/composing-skills) guide for workflow examples.
Resources [#resources]
* [Getting Started](/docs/en/skills/getting-started) — 5-minute setup guide
* [Way to AGI Workshop Tutorial (Feishu)](https://waytoagi.feishu.cn/wiki/Saa3wVV5PihHpPkfNMgcMeAQn4f) — illustrated step-by-step community guide
* [API Reference](/docs/en/openapi) — Full endpoint documentation
* [GitHub](https://github.com/marswaveai/skills) — Source code and issues
* [Discord](https://discord.gg/ZbwA7g2guU) — Community support
# ListenHub Voice (/docs/en/skills/listenhub-voice)
Turn a text script into a finished audio track with the end-to-end `ListenHub-Voice-1.0` model. Unlike stitched-together TTS, the model produces one continuous take that can carry sound effects, multiple speakers, cloned voices, or narration derived from a reference image.
> ListenHub Voice costs **30 credits per generated minute**. Billing uses the actual generated audio duration, with a minimum charge of **1 credit** per task.
Trigger [#trigger]
Invoke this skill with `/listenhub-voice`, or use any of these phrases:
| Phrase | Language |
| ------------------------------------- | -------- |
| `generate audio` / `sound effect` | English |
| `end-to-end audio` / `image to audio` | English |
| `生成音频` / `语音生成` | Chinese |
| `端到端音频` / `图片转音频` | Chinese |
| `多音色对白` / `参考音频克隆` / `音效生成` | Chinese |
Requires ListenHub Skills to be installed — see [Getting Started](/docs/en/skills/getting-started).
Quick Example [#quick-example]
```
Generate a 20-second clip: "Welcome to ListenHub — here is your daily briefing."
```
The AI collects the script, voice, and any tuning, then submits one async task and polls it until the audio is ready. You get a link to listen and download.
When to Use [#when-to-use]
- **Plain text / sound effects** -- Narrate a script and let the model bake in the sound effects it describes — no voice selection needed.
- **Single voice** -- Read a script in one built-in voice or a platform voice_type.
- **Multi-voice dialogue** -- Assign 2–3 voices to a conversation, one line at a time.
- **Voice cloning** -- Clone a voice from a short reference audio clip and speak your script in it.
- **Image to audio** -- Turn a reference image into a short narrated clip.
For plain single-voice narration with an already-registered ListenHub speaker, [`/tts`](/docs/en/skills/tts) is lower latency. Use `/listenhub-voice` when you want sound effects, dialogue, cloning, or image-driven audio in one pass.
Modes [#modes]
**Text / SFX:**
No voices, no image — the model synthesizes the script and any sound effects described in it.
```
Generate audio: "Rain patters on the window as a distant train rolls by."
```
**Single voice:**
One voice reads the whole script — a built-in ListenHub voice or platform `voice_type`.
```
Read this in a warm female voice: "Here are today's headlines."
```
**Dialogue:**
Two or three voices in conversation. Each line is assigned to a voice with an `@音频N` prefix, in order.
```
Make a two-voice dialogue: @音频1 asks a question, @音频2 answers.
```
Every voice in a multi-voice request must be reference-audio-capable. A built-in `voice_type` is single-voice only.
**Cloning:**
Clone a voice from a short public reference clip, then speak your script in it.
```
Clone the voice in https://example.com/host.mp3 and read my intro.
```
**Image:**
Turn a reference image into a short narrated clip. Image mode is mutually exclusive with voices.
```
Describe this image as a 15-second narrated clip.
```
Parameters [#parameters]
| Parameter | Options | Default |
| ------------- | ---------------------------------------------------- | ----------------- |
| Text | Up to 1400 characters | required |
| Voices | 1–3 built-in voices or reference clips | None (plain text) |
| Image | One reference image (mutually exclusive with voices) | None |
| Speech rate | `-50` to `100` | Model default |
| Loudness | `-50` to `100` | Model default |
| Pitch | `-12` to `12` | Model default |
| Format | `mp3`, `wav`, `pcm`, `ogg_opus` | `mp3` |
| Duration hint | `1` to `110` seconds | None |
| Watermark | On / off | Off |
Voices and an image are **mutually exclusive** — send at most one. Built-in voices are fetched from the API; ask "what voices are available?" to browse the list with demo audio.
Output [#output]
After the task reaches `success`, you receive:
* **Listen link** — stream the finished audio
* **Audio download** — say "download audio" to save it locally (the file extension follows your chosen `format`)
* **Task detail** — status, billed duration, and credits charged
Generation is asynchronous: the task moves through `pending` → `generating` → `uploading` → `success`. On failure, the reason is reported and any reserved credits are refunded.
API Reference [#api-reference]
See the [ListenHub Voice API reference](/docs/en/openapi/api-reference/listenhub-voice) for the underlying endpoints, request fields, and error codes.
# Music (/docs/en/skills/music)
Generate original AI music from a prompt or lyrics, remix an existing song, score an image or video, isolate a single track, or analyze audio — all powered by the Mureka provider through the `listenhub music` CLI.
Trigger [#trigger]
Invoke this skill with `/music`, or use any of these phrases:
| Phrase | Language |
| -------------------------------------- | -------- |
| `music` / `generate music` / `compose` | English |
| `create a song` / `cover` / `remix` | English |
| `instrumental` / `soundtrack` / `stem` | English |
| `recognize lyrics` / `extend` | English |
| `音乐` / `生成音乐` / `作曲` / `做一首歌` | Chinese |
| `翻唱` / `混音` / `续写` / `纯音乐` | Chinese |
| `配乐` / `分轨` / `识别歌词` | Chinese |
Requires ListenHub Skills to be installed — see [Getting Started](/docs/en/skills/getting-started).
This skill does not use speakers — music generation has no speaker selection.
Quick Example [#quick-example]
```
Make a song about a summer evening by the sea
```
The AI confirms the capability and parameters with you, submits the job, and notifies you when the track is ready. You get a listen link, duration, and credit cost, plus a local download when output mode is set to `download` or `both`.
Capabilities [#capabilities]
The skill splits into two groups: **generation** commands run asynchronously and return a task to poll; **analysis** commands run synchronously and return results in the same call.
**Generate:**
**generate** — text and/or lyrics into a new song. At least one of `prompt` or `lyrics` is required. Optional `style`, `title`, `model`, instrumental toggle, and a cloned `vocal-id`. Async.
**Remix:**
**remix** — an existing song plus new lyrics into a re-creation. Provide exactly one input source: an audio file, an audio URL, or a Mureka `provider-song-id`. Both `lyrics` and `prompt` are required. Optional `style`, `title`, `model`. Async.
**Instrumental:**
**instrumental** — a pure instrumental with no vocals. Provide exactly one of `prompt` or a `reference-audio` file. Optional `title`, `model`. Async.
**Soundtrack:**
**soundtrack** — music scored to an image or a video. Provide exactly one of `image` or `video`. Optional `prompt`, `title`, `model`. Async.
**Track:**
**track** — isolate or generate a single instrument or vocal track from a song. Provide exactly one input source (audio file or `provider-song-id`) plus a `generate-type`. When the type is `Vocals`, `lyrics` is required. Optional `prompt`, `vocal-gender`, and a `generate-start`/`generate-end` range in seconds. Async.
**Extend:**
**extend** — make an existing song longer. Provide one input source (audio file or `provider-song-id`). Optional `prompt` describing how to continue, and `model`. Async.
**Recognize:**
**recognize** — extract lyrics with line-level timestamps from an audio file. Sync — results return immediately.
**Describe:**
**describe** — analyze an audio file into a description, tags, genres, and instruments. Sync — results return immediately.
**Stem:**
**stem** — split a song into separated stems and return ZIP download URLs. Choose a separation model (`audio-separation-1` or `audio-separation-2`). Sync — results return immediately.
> A `cover` capability also exists but is deprecated — use **remix** instead unless you specifically need the older cover flow.
Two task-management commands are available any time: `list` shows recent tasks, and `get ` returns the status or result of a single task.
Models [#models]
Generation commands accept a `model` parameter. `auto` is the default and lets the service pick.
| Model | Notes |
| ------------ | ----------------------------------- |
| `auto` | Default — service selects the model |
| `mureka-7.6` | Mureka 7.6 |
| `mureka-8` | Mureka 8 |
| `mureka-9` | Mureka 9 |
| `mureka-o2` | Mureka o2 |
Analysis is different. The **stem** command takes a separation model instead — `audio-separation-1` or `audio-separation-2`. The `recognize` and `describe` commands take no model.
Parameters [#parameters]
Parameters apply per capability. Provide only what each command needs; the AI asks for required inputs and offers optional ones.
| Parameter | Applies to | Notes |
| ------------------------------------------ | -------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------ |
| `prompt` | generate, remix, instrumental, soundtrack, track, extend | Free text describing the music or direction |
| `lyrics` | generate, remix, track (Vocals only) | Song lyrics |
| `style` | generate, remix | Genre or mood, e.g. `city pop` |
| `title` | generate, remix, instrumental, soundtrack | Track title; auto-generated if omitted |
| `model` | generation commands | One of the models above; defaults to `auto` |
| `instrumental` | generate | Toggle vocals off |
| `vocal-id` | generate | A cloned voice id |
| `audio` / `audio-url` / `provider-song-id` | remix, track, extend | The input song; supply exactly one |
| `reference-audio` | instrumental | Reference audio file (alternative to `prompt`) |
| `image` / `video` | soundtrack | Source media; supply exactly one |
| `generate-type` | track | One of `Vocals`, `Instrumental`, `Drums`, `Bass`, `Guitar`, `Keyboard`, `Percussion`, `Strings`, `Synth`, `FX`, `Brass`, `Woodwinds` |
| `vocal-gender` | track | `male` or `female` |
| `generate-start` / `generate-end` | track | Time range in **seconds** |
File limits [#file-limits]
All input files are capped at **10 MB**. Accepted formats by type:
| Type | Formats |
| ----- | ----------------------------------------------------- |
| Audio | `mp3`, `m4a` (the `track` command also accepts `wav`) |
| Image | `jpg`, `jpeg`, `png`, `webp` |
| Video | `mp4`, `mov`, `avi`, `mkv`, `webm` |
You can also pass a URL instead of a local file where the command supports it; the CLI validates it on submission.
> Music generation is slow — expect roughly **5 to 10 minutes** per track. The AI submits the job in the background and notifies you on completion. If you only have a task id, check progress with `listenhub music get --json` or browse `listenhub music list --json`.
Output [#output]
Output behavior follows the `outputMode` set during config:
* **`inline` or `both`** — the audio URL is shown as a clickable listen link, alongside the title, duration, and credit cost.
* **`download` or `both`** — the file is also saved to the current working directory with a friendly, topic-based name (e.g. `summer-breeze.mp3`). Names are de-duplicated automatically.
For **stem**, the result is one or more ZIP download URLs; in `download` or `both` mode they are fetched to the current directory. For **recognize** and **describe**, the result is shown directly in the conversation.
Each completed task reports its `creditCost`. To estimate or check credits, see the credits notes in the [Music API reference](/docs/en/openapi/api-reference/music) and your balance via [`GET /v1/user/subscription`](/docs/en/openapi/api-reference/subscription).
CLI Commands [#cli-commands]
The skill drives the `listenhub music` command group. The common shape:
```bash
# Generate a song (async — polls until ready)
listenhub music generate --prompt "upbeat summer pop about the sea" --json
# Remix an existing file with new lyrics
listenhub music remix --audio demo.mp3 --lyrics "..." --prompt "rework as city pop" --json
# Pure instrumental
listenhub music instrumental --prompt "electronic track for a game intro" --json
# Soundtrack for a video
listenhub music soundtrack --video clip.mp4 --prompt "tense, suspenseful score" --json
# Analyze audio (sync)
listenhub music recognize --audio song.mp3 --json
listenhub music describe --audio song.mp3 --json
listenhub music stem --audio track.mp3 --model audio-separation-2 --json
# Task management
listenhub music list --json
listenhub music get --json
```
Global flags apply: `--json` / `-j` for machine output, `--no-wait` to skip polling, `--timeout
` to bound it.
API Reference [#api-reference]
See the [Music API reference](/docs/en/openapi/api-reference/music) for endpoint paths, request parameters, response fields, and credit handling.
# Podcast (/docs/en/skills/podcast)
Generate podcast episodes from any topic, URL, or text. Choose between quick overviews, deep analysis, or debate formats with 1-2 AI speakers.
Trigger [#trigger]
Invoke this skill with `/podcast`, or use any of these phrases:
| Phrase | Language |
| --------------------------------- | -------- |
| `make a podcast about...` | English |
| `podcast` | English |
| `discuss` / `debate` / `dialogue` | English |
| `做播客` | Chinese |
| `播客` / `录一期节目` | Chinese |
Requires ListenHub Skills to be installed — see [Getting Started](/docs/en/skills/getting-started).
Quick Example [#quick-example]
```
Make a podcast about the latest AI developments, in English, go deep
```
The AI handles topic research, scripting, voice selection, and audio generation. You get a link to listen and download.
Modes [#modes]
**Quick:**
Short, concise overview of the topic. \~5 minutes.
Best for news summaries, brief introductions, and quick takes.
**Deep:**
Thorough analysis with extended discussion. \~10-15 minutes.
Best for deep-dives, educational content, and detailed analysis.
**Debate:**
Two speakers with opposing viewpoints. \~10-15 minutes. Requires 2 speakers.
Best for controversial topics, pros/cons analysis, and opinion pieces.
| Intent | Recommended mode |
| ------------------------ | ---------------- |
| "Quick overview of X" | Quick |
| "Learn about X in depth" | Deep |
| "Pros and cons of X" | Debate |
| No preference stated | Quick (default) |
Parameters [#parameters]
| Parameter | Options | Default |
| ---------- | ------------------------------ | ------------- |
| Mode | `quick`, `deep`, `debate` | `quick` |
| Language | `zh` (Chinese), `en` (English) | Auto-detected |
| Speakers | 1 (solo) or 2 (dialogue) | 1 |
| References | URLs or text to include | None |
Speakers are fetched dynamically from the API — the AI presents available voices for your chosen language. Ask "what voices are available?" to browse the full list with demo audio.
Reference Materials [#reference-materials]
Ground the episode in your own source material instead of letting the AI write from general knowledge. Pass references right alongside the topic — a URL, pasted text, or both:
```
Make a podcast about the pros and cons of remote work.
Reference: https://example.com/remote-work-2026
```
Under the hood, references map to two repeatable CLI flags:
| Flag | Use | Repeatable |
| --------------- | -------------------------- | ---------- |
| `--source-url` | One URL reference per flag | Yes |
| `--source-text` | One block of text per flag | Yes |
You can mix several of each — multiple `--source-url` flags for a set of links, multiple `--source-text` flags for several quotes or notes. When you provide no references, both flags are omitted and the AI writes from the topic alone.
Generation Methods [#generation-methods]
One-Step (Recommended) [#one-step-recommended]
Text and audio are generated together in a single pass. Faster and simpler.
```
Make a podcast about quantum computing
```
Two-Step (Review Script First) [#two-step-review-script-first]
Generate the script first, review and edit it, then generate audio from the final version.
```
Make a podcast about quantum computing, let me review the script first
```
The two-step method:
1. Generate the script [#generate-the-script]
The AI writes the dialogue script and saves it as a Markdown file.
2. Review and edit [#review-and-edit]
Generation pauses here. Edit the content, condense a long script, adjust the tone, or fix any inaccuracies in the saved file.
3. Generate audio [#generate-audio]
After you approve, the AI generates audio from the final script.
Use two-step when you want to lock down the wording before committing credits to audio generation.
Supported Inputs [#supported-inputs]
| Input type | Example |
| ----------------- | ------------------------------------------ |
| Topic description | "The future of renewable energy" |
| URL | A YouTube video, article, or blog post URL |
| Plain text | Paste or type the content directly |
Output [#output]
After generation completes, you receive:
* **Listen link** — stream directly on ListenHub
* **Audio download** — say "download audio" to save locally
* **Transcript** — available in the episode detail page
API Reference [#api-reference]
See the [Podcast API reference](/docs/en/openapi/api-reference/podcast) for technical details on the underlying API.
# Slides (/docs/en/skills/slides)
Turn a topic, URL, or block of text into a slide deck with AI-generated visuals. By default the deck is visual-only; you can optionally add voice narration. Best for presentations, summaries, and visual storytelling.
Trigger [#trigger]
Invoke this skill with `/slides`, or use any of these phrases:
| Phrase | Language |
| ----------------------------------------- | -------- |
| `slides` / `slide deck` / `create slides` | English |
| `presentation` | English |
| `幻灯片` / `做幻灯片` | Chinese |
| `PPT` | Chinese |
Requires ListenHub Skills to be installed — see [Getting Started](/docs/en/skills/getting-started).
Quick Example [#quick-example]
```
Make slides about quantum computing
```
The AI confirms your language and whether you want narration, then generates the deck and returns an online link.
> Slides and [Explainer](/docs/en/skills/explainer) both produce visual content from a topic. Use **Slides** for a deck of discrete slides (narration optional, off by default). Use **Explainer** for a continuous narrated video. If you want audio without slides, use [Speech](/docs/en/skills/tts) or [Podcast](/docs/en/skills/podcast).
Options [#options]
The AI collects these through a short Q\&A before generating. You can also pass them directly when driving the `listenhub slides create` command yourself.
| Option | CLI flag | Values | Default |
| --------------- | ----------------- | --------------------------------------------- | --------------------------------- |
| Topic / content | `--query` | Free text, or pair with `--source-url` | Required |
| Source URL | `--source-url` | A URL to summarize into slides | None |
| Narration | `--no-skip-audio` | Present = add narration; absent = visual-only | Off (visual-only) |
| Speaker | `--speaker` | A voice name (only with narration) | Built-in default for the language |
| Language | `--lang` | `en`, `zh`, `ja` | Asked, or read from config |
| Image size | `--image-size` | `1K`, `2K`, `4K` | `2K` |
| Aspect ratio | `--aspect-ratio` | `16:9`, `9:16`, `1:1`, etc. | `16:9` |
With or without narration [#with-or-without-narration]
By default, slides are generated **without** audio — you get the deck only. To add a voiceover, the AI passes `--no-skip-audio`, which enables narration and lets you pick a speaker. Narration supports exactly **one** speaker.
**Without narration:**
The default. The AI generates only the visual deck.
```bash
listenhub slides create \
--query "Quantum computing" \
--lang en \
--image-size 2K \
--aspect-ratio 16:9 \
--timeout 600 \
--json
```
Typical generation time: 2–4 minutes.
**With narration:**
Adds a voiceover. Requires `--no-skip-audio` and a single `--speaker`.
```bash
listenhub slides create \
--query "React hooks" \
--lang en \
--image-size 2K \
--aspect-ratio 16:9 \
--no-skip-audio \
--speaker "Mars" \
--timeout 600 \
--json
```
Typical generation time: 4–8 minutes.
Language [#language]
`--lang` accepts `en`, `zh`, or `ja`. If you set a default language in config, the AI pre-fills it and skips the question; otherwise it asks before generating.
Speaker [#speaker]
Only applies when narration is enabled. If you do not name a speaker, the AI uses the built-in default voice for the chosen language. To use a different voice, ask to change it and the AI fetches the available voices — speaker IDs are never hardcoded.
Image size and aspect ratio [#image-size-and-aspect-ratio]
`--image-size` controls the resolution of generated visuals (`1K`, `2K`, `4K`; default `2K`). `--aspect-ratio` controls slide shape (`16:9` by default; `9:16` for vertical, `1:1` for square).
Source URL [#source-url]
To build slides from an existing page, provide a URL. The AI passes it as `--source-url` alongside your `--query`, and the deck is generated from that content.
Output [#output]
When generation finishes, the AI presents the result based on your configured output mode.
Online deck [#online-deck]
Every run produces an online deck you can view and share:
```
https://listenhub.ai/app/slides/{episodeId}
```
With narration enabled, the audio track is also returned as a separate link.
Download [#download]
If your output mode is `download` or `both`, the AI also saves files into the current working directory:
* **Without narration** — a script file, e.g. `quantum-computing-slides.md`
* **With narration** — a `quantum-computing-slides/` folder containing `script.md` and `audio.mp3`
The online deck link is always shown, regardless of output mode.
> Credit cost varies by length, image size, and whether narration is enabled, and is shown in the result after generation. To estimate before generating, see the relevant `estimate-credits` endpoint in the [Slides API reference](/docs/en/openapi/api-reference/slides).
Related [#related]
- **Explainer Video** -- Continuous narrated video with AI visuals [/docs/en/skills/explainer](/docs/en/skills/explainer)
- **Image Generation** -- Generate standalone AI images [/docs/en/skills/image](/docs/en/skills/image)
- **Podcast** -- Audio-only multi-speaker discussion [/docs/en/skills/podcast](/docs/en/skills/podcast)
API Reference [#api-reference]
See the [Slides API reference](/docs/en/openapi/api-reference/slides) for endpoint details and code examples.
# TTS (/docs/en/skills/tts)
Convert text or URL content into natural-sounding speech audio. The skill picks one of two paths based on what you give it: a single voice reading straight through, or multiple speakers voicing a script you mark up line by line.
Trigger [#trigger]
Invoke this skill with `/tts`, or use any of these phrases:
| Phrase | Language |
| -------------------------------- | -------- |
| `read aloud` / `read this aloud` | English |
| `TTS` / `text to speech` | English |
| `voice narration` | English |
| `朗读这段` | Chinese |
| `配音` / `语音合成` | Chinese |
Requires ListenHub Skills to be installed — see [Getting Started](/docs/en/skills/getting-started).
Quick Example [#quick-example]
```
Read this article aloud: https://en.wikipedia.org/wiki/Podcast
```
The skill fetches the content, picks a voice, and generates natural speech audio.
Quick vs Script Mode [#quick-vs-script-mode]
The skill decides between two modes before it asks you anything. Both produce an MP3 you can stream or download; they differ in how many voices they use and how much control you have over each line.
| | Quick mode | Script mode |
| -------- | ------------------------------------------------- | ------------------------------------------------------ |
| CLI flag | `--mode direct` | `--mode smart` |
| Voices | One | One per character |
| Speed | Fast, low-latency (\~1–2 min) | Moderate (\~2–3 min) |
| Best for | Reading an article, casual TTS, a single narrator | Dialogue, audiobooks, scripted multi-character content |
| Control | Reads the text as one block | Each segment is voiced by the speaker you assign |
**Quick mode** takes a block of text (or a URL) and reads it straight through with one voice. It runs synchronously and returns an audio link quickly.
**Script mode** takes a script where each line is tagged with a speaker, assigns a distinct voice per character, and stitches the segments into one track. Longer scripts run in the background — the skill submits the job and polls until it completes.
> The CLI's `tts create` command defaults to `--mode smart`. The skill chooses the flag for you from the mode detection below, so you rarely set it by hand.
How the Mode Is Detected [#how-the-mode-is-detected]
The skill reads your request and routes to a mode automatically, before asking any questions:
| Signal in your input | Mode |
| -------------------------------------------------------- | --------------- |
| "多角色", "脚本", "对话", "script", "dialogue", "multi-speaker" | Script |
| Multiple characters named or described by role | Script |
| Structured segments like `A: ...` / `B: ...` | Script |
| A single paragraph of text, no character markers | Quick |
| "read this", "TTS", "朗读" with plain text | Quick |
| Ambiguous | Quick (default) |
If the routing looks wrong, say so — for example, "do this as a multi-speaker script" — and the skill switches modes.
Writing a Script (Script mode) [#writing-a-script-script-mode]
In Script mode you provide the lines with a speaker on each one. The simplest format is one line per turn, `Speaker: text`:
```
Alex: Hello everyone, welcome to the show.
Sam: Thanks for having me!
Alex: Let's get into today's topic.
```
The skill parses each `Speaker:` marker into a segment, collects the unique characters (`Alex`, `Sam`), and assigns a voice to each. Markers carry through to the underlying [`/v1/flow-speech/episodes/tts`](/docs/en/openapi/api-reference/flowspeech) request, which also accepts an explicit `scripts` array if you call the API directly:
```json
{
"scripts": [
{ "content": "Hello everyone, welcome to the show.", "speakerId": "cozy-man-english" },
{ "content": "Thanks for having me!", "speakerId": "travel-girl-english" }
]
}
```
Each segment is spoken by its assigned speaker, in order.
Script tips [#script-tips]
* Break at natural speech boundaries — one sentence or short paragraph per line.
* Alternate speakers for a dialogue feel.
* Keep all speakers in the same language.
* If you call the API directly, each `speakerId` must be a valid ID from the [speakers endpoint](/docs/en/openapi/api-reference/speakers).
Voice Selection and Saved Preferences [#voice-selection-and-saved-preferences]
You do not have to choose a voice. The skill follows this order:
1. **Saved preference.** If you have a default voice saved for the detected language, the skill uses it silently.
2. **Built-in default.** Otherwise it falls back to a built-in default voice for that language — for English, a neutral narrator; for Chinese, a primary and secondary voice for multi-character scripts.
3. **Explicit change.** Only if you ask to change the voice does the skill show you the speaker list and let you pick.
When you pick a **new** voice (not when a default is used), the skill offers to remember it:
* Quick mode — "Save this as your default voice for `{language}`?"
* Script mode — "Save these voice assignments for future sessions?"
Saved preferences live in `.listenhub/tts/config.json` in the working directory, under `defaultSpeakers` keyed by language. Quick mode stores a single voice; Script mode stores the full set of voices assigned that session. Choosing "No" uses the voice for the current run only and leaves the config untouched.
> Preferences are per working directory. Run the skill in a different project and you start from the built-in defaults again.
Parameters [#parameters]
| Parameter | Options | Default |
| --------- | ---------------------------------- | --------------------------------------- |
| Input | Text or URL | — |
| Mode | `direct` (Quick), `smart` (Script) | Auto-detected |
| Language | `en`, `zh`, `ja` | Auto-detected from the text |
| Speaker | Speaker name or `speakerId` | Saved preference, else built-in default |
When to Use TTS vs Podcast [#when-to-use-tts-vs-podcast]
Both skills can produce multi-speaker audio, but they serve different purposes:
| Use case | Skill |
| ----------------------------------------------------- | ---------------------------------- |
| Topic-based discussion with natural conversation flow | [Podcast](/docs/en/skills/podcast) |
| Precise control over every line and speaker | TTS (Script mode) |
| Reading an article or text aloud | TTS (Quick mode) |
Limits [#limits]
* FlowTTS text input: max 10,000 characters.
* For longer content, pass a URL instead — the API fetches and processes it automatically.
* Plain `text` sources must be at least 10 characters.
Credits [#credits]
Generation consumes credits. Costs depend on length, mode, and voice, so check the relevant `estimate-credits` endpoint before a large job rather than assuming a fixed price. See the [FlowSpeech API reference](/docs/en/openapi/api-reference/flowspeech) for the estimation endpoints.
Output [#output]
After generation:
* **Listen link** — stream the audio on ListenHub.
* **Subtitles** — Script mode also returns a subtitles URL when available.
* **Download** — say "download audio" to save the MP3 to the current directory with a topic-based filename.
API Reference [#api-reference]
See the [FlowSpeech API reference](/docs/en/openapi/api-reference/flowspeech) for `/v1/flow-speech/episodes`, `/v1/flow-speech/episodes/tts`, and the `/v1/speech` text-to-speech surface.
Related [#related]
- **Podcast** -- Topic-driven multi-speaker conversations [/docs/en/skills/podcast](/docs/en/skills/podcast)
- **Explainer** -- Narrated explainer videos that reuse TTS voices [/docs/en/skills/explainer](/docs/en/skills/explainer)
- **Getting Started** -- Install ListenHub Skills and authenticate [/docs/en/skills/getting-started](/docs/en/skills/getting-started)
# Updating Skills (/docs/en/skills/updating)
Keep your skills current to get new skills, bug fixes, and improvements as they're released.
For Users [#for-users]
**Via npx skills (Recommended):**
```bash
npx skills update -g
```
**Via Git:**
```bash
# If you already have a local clone:
cd path/to/marswaveai/skills
git pull origin main
# Or clone fresh:
git clone https://github.com/marswaveai/skills
```
Use this if you're working from a local clone of the skills repository.
Restart your AI coding tool (Claude Code, Cursor, Windsurf, etc.) after updating.
***
For AI Agents [#for-ai-agents]
This section is for AI Agents (Claude Code, Cursor, Windsurf, OpenCode, and similar tools) executing skill management tasks on behalf of the user.
Installing Skills [#installing-skills]
**When to run:** User asks to install ListenHub Skills. Example triggers: "install listenhub skills", "set up skills", "add skills".
**Steps:**
1. Run via Bash in the user's project directory:
```bash
npx skills add marswaveai/skills
```
2. Verify exit code is 0.
3. Report to user: skills have been installed and are ready to use.
> Installation is per-project. Run this command from the project root where the user intends to use the skills.
Updating Skills [#updating-skills]
**When to run:** User asks to update or upgrade skills. Example triggers: "update my skills", "check for skill updates", "upgrade skills", "get the latest skills".
**Steps:**
1. Run via Bash:
```bash
npx skills update -g
```
2. Verify exit code is 0.
3. Report to user: skills have been updated. **Instruct the user to restart their AI coding tool** — the agent itself cannot reload new skill definitions at runtime.
> After updating, a full client restart is required to load new skill definitions. The AI agent cannot reload skills without restarting.
Checking Installed Version [#checking-installed-version]
To inspect what's currently installed:
```bash
cat .claude/skills/marswaveai/skills/CHANGELOG.md 2>/dev/null | head -10
```
Or check the skills directory to see what skills are present:
```bash
ls .claude/skills/marswaveai/skills/
```
# Video Generation (/docs/en/skills/video-gen)
Generate AI videos from a text prompt or reference materials using the `listenhub video` CLI. Animate a still image, edit an existing clip, or drive a character's lips with audio or text-to-speech. Three model families cover different jobs: HappyHorse, SeeDance, and PixVerse.
Trigger [#trigger]
Invoke this skill with `/video-gen`, or use any of these phrases:
| Phrase | Language |
| ----------------------------------------------------- | -------- |
| `video generation` / `text to video` / `create video` | English |
| `video edit` / `lipsync` / `pixverse` | English |
| `生成视频` / `做视频` / `视频生成` | Chinese |
| `视频编辑` / `口型` / `对口型` | Chinese |
Requires ListenHub Skills to be installed — see [Getting Started](/docs/en/skills/getting-started).
For narrated explainer videos with AI visuals, use [`/explainer`](/docs/en/skills/explainer) instead.
Quick Example [#quick-example]
```
Generate a video: cyberpunk city at night, 16:9, 5 seconds
```
The AI walks you through the mode and parameters one question at a time, shows a cost estimate, and asks you to confirm before generating. Generation takes minutes — the job runs in the background and the AI notifies you when the video is ready, with a URL, duration, resolution, and credit cost.
> Video generation always runs with `--no-wait`, so the CLI returns a task id immediately and the AI polls in the background (10s interval). If you only have a task id, check progress with `listenhub video get --json`.
Models [#models]
Pick the model by the job. HappyHorse is the default and the only family that edits existing video; SeeDance adds last-frame and reference-audio support; PixVerse is the only family with lip sync, plus a set of atomic capabilities (mimic, restyle, fusion, transition, marketing agent).
| Capability | HappyHorse (default) | SeeDance | PixVerse |
| ---------------------------- | ----------------------------------- | ------------------------------- | --------------------------------------- |
| Text-to-video | Yes | Yes | Yes (`text_to_video`) |
| Image-to-video (first-frame) | Yes | Yes (+ last-frame) | Yes (`image_to_video`) |
| Reference image | Yes (1–9, `[Image N]` syntax) | Yes | Yes (`fusion`, `@refName`) |
| Video edit | Yes | No | No |
| Lip sync | No | No | Yes (`lip_sync`, audio or TTS) |
| Motion transfer / mimic | No | No | Yes (`mimic`, locked 720p) |
| Restyle | No | No | Yes (`restyle`) |
| Transition (first → last) | No | Yes (frame mode) | Yes (`transition` / `multi_transition`) |
| Reference video | No (use video edit) | Yes | Yes (mimic / lip\_sync source) |
| Reference audio | No | Yes | Yes (lip\_sync) |
| Max resolution | 1080p | 1080p | 1080p |
| Resolution options | 720p, 1080p | 480p, 720p, 1080p | 360p, 540p, 720p, 1080p |
| Duration range | 3–15s | 4–15s | 1–60s (agent: 20/30/60) |
| Aspect ratios | 16:9, 9:16, 1:1, 4:3, 3:4, 4:5, 5:4 | 16:9, 9:16, 1:1, 4:3, 3:4, 21:9 | 9:16, 16:9, 1:1, 4:3, 3:4 |
Lip sync, mimic, restyle, fusion, transition, and the marketing agent are **PixVerse-only**. HappyHorse and SeeDance do not support them.
SeeDance model variants [#seedance-model-variants]
When you pick SeeDance, choose between two variants:
| Model | Notes |
| ------------------------ | --------------------------------------------------------------------------- |
| `doubao-seedance-2-pro` | Higher quality; required for 1080p; supports last-frame and reference-audio |
| `doubao-seedance-2-fast` | Faster; selecting 1080p auto-upgrades to `pro` |
> PixVerse is **OpenAPI-only** — it lives under `listenhub openapi video pixverse` and uses public-network URLs for all media (no local file upload). If you want lip sync, mimic, restyle, fusion, transition, or the marketing agent but only have internal-auth login configured, set up an API key first with `listenhub openapi config set-key`.
Modes [#modes]
The AI routes to a mode based on what reference material you have. HappyHorse and SeeDance share the `listenhub video create` command; PixVerse uses `listenhub openapi video pixverse generate` with an explicit `--capability`.
**Text-to-video:**
Generate a video from a text prompt only, no reference media. Available on all three model families.
```bash
listenhub video create \
--prompt "cyberpunk city at night, neon reflections on wet streets" \
--model "happyhorse" \
--resolution "1080p" \
--ratio "16:9" \
--duration 5 \
--no-wait --json
```
**Image-to-video:**
Animate a still image as the first frame. SeeDance can also take a last-frame image to interpolate a transition between two stills.
Image requirements: `jpg`, `jpeg`, `png`, or `webp`; local files up to 20 MB; width and height ≥ 300px; aspect ratio between 1:2.5 and 2.5:1.
```bash
listenhub video create \
--prompt "bring the scene to life with smooth motion" \
--model "happyhorse" \
--resolution "1080p" \
--duration 5 \
--first-frame "/path/to/scene.png" \
--no-wait --json
```
For SeeDance frame mode, add `--last-frame` and use a `doubao-seedance-2-*` model.
> HappyHorse image-to-video has **no `--ratio`** — the output ratio is determined by the input image. SeeDance still accepts `--ratio`.
**Reference image:**
Supply 1–9 reference images to guide style or characters. With HappyHorse, refer to specific images in the prompt using `[Image 1]`, `[Image 2]`, and so on.
Image requirements: `jpg`, `jpeg`, `png`, or `webp`; up to 20 MB each; HappyHorse recommends short edge ≥ 400px.
```bash
listenhub video create \
--prompt "[Image 1]'s character walking through [Image 2]'s street" \
--model "happyhorse" \
--resolution "1080p" \
--ratio "16:9" \
--duration 5 \
--reference-image "/path/to/character.png" \
--reference-image "/path/to/scene.png" \
--no-wait --json
```
SeeDance reference mode additionally accepts up to 3 reference videos (`mp4`/`mov`, ≤ 50 MB) and up to 3 reference audios (`mp3`/`wav`, ≤ 20 MB, paired with an image or video).
**Lip sync:**
**PixVerse only.** Drive a character's lips with either an audio file or text-to-speech. The source video must already exist on PixVerse — reference it by `--source-video-id` or by a prior succeeded task with `--source-task-id`.
Drive with an audio file (one public audio URL, 5–60s):
```bash
listenhub openapi video pixverse generate \
--capability lip_sync \
--source-video-id "abc123" \
--audio "https://example.com/voice.mp3" \
--quality 720p \
--no-wait --json
```
Drive with text-to-speech (nested `tts`, no `--audio`):
```bash
listenhub openapi video pixverse generate \
--capability lip_sync \
--source-task-id "task_xyz" \
--pixverse-json '{"tts":{"speakerId":"speaker_01","content":"Welcome to this episode"}}' \
--quality 720p \
--no-wait --json
```
> Provide **either** an audio file **or** TTS, never both — passing both is rejected. For TTS, use the nested `--pixverse-json '{"tts":{...}}'`; do not use `--lip-sync-tts` / `--lip-sync-speaker-id` / `--lip-sync-content`, which the contract does not accept.
Video edit (HappyHorse) [#video-edit-happyhorse]
Edit an existing clip — change style, replace the background, restyle motion. HappyHorse only; if you ask for this on SeeDance, the AI switches you to HappyHorse.
Video requirements: `mp4`/`mov` (H.264 recommended); 3–60s input (output capped at 15s); ≤ 100 MB; short edge ≥ 360px, long edge ≤ 4096px. Optionally pass 0–5 reference images.
```bash
listenhub video create \
--prompt "replace the background with a deep starry sky, keep the subject's motion" \
--model "happyhorse" \
--resolution "1080p" \
--reference-video "/path/to/input.mp4" \
--audio-setting "origin" \
--no-wait --json
```
`--audio-setting` controls audio: `auto` lets the model decide, `origin` keeps the original audio. Video edit has no `--ratio` or `--duration` — the output matches the input video.
Other PixVerse capabilities [#other-pixverse-capabilities]
PixVerse exposes additional atomic capabilities through `--capability`, all OpenAPI-only with URL inputs:
| Capability | Inputs | Constraints |
| --------------------------------- | ------------------------------------------------------------ | ----------------------------------------------------------------------------- |
| `mimic` (motion transfer) | 1 image + 1 video | Quality locked to 720p; motion source 5–30s |
| `restyle` | `--source-video-id` (or `--source-task-id`) + `--restyle-id` | — |
| `fusion` | Nested `imageReferences` (1–8), prompt uses `@refName` | Top-level `--image` must be empty |
| `transition` / `multi_transition` | Nested `multiTransition` keyframes (2–7) | Default quality 360p |
| `agent` (ad\_master / promo\_mix) | Prompt + images | Quality 720p/1080p only; duration 20/30/60 only; `promo_mix` needs ≥ 4 images |
Parameters [#parameters]
The AI asks for these one at a time and applies sensible session defaults. For HappyHorse and SeeDance, ratio and duration use `--ratio` / `--duration`; PixVerse uses `--quality` and `--aspect-ratio` instead of `--resolution` / `--ratio`.
| Parameter | Flag | Notes |
| --------------- | ------------------- | ---------------------------------------------------------------------------------------------- |
| Prompt | `--prompt` | Free text. HappyHorse ≤ 2500 (Chinese) / ≤ 5000 (non-Chinese); SeeDance ≤ 500; PixVerse ≤ 2048 |
| Model | `--model` | `happyhorse` (default), `doubao-seedance-2-pro`, `doubao-seedance-2-fast`, `pixverse` |
| Resolution | `--resolution` | HappyHorse: 720p/1080p; SeeDance: 480p/720p/1080p (480p is SeeDance-only) |
| Aspect ratio | `--ratio` | Not used for image-to-video or video edit (ratio follows input) |
| Duration | `--duration` | Seconds. HappyHorse 3–15, SeeDance 4–15 |
| First frame | `--first-frame` | Image-to-video source image |
| Last frame | `--last-frame` | SeeDance frame mode only |
| Reference image | `--reference-image` | Repeatable; 1–9 (HappyHorse), or video-edit references (0–5) |
| Reference video | `--reference-video` | Video-edit input (HappyHorse) or SeeDance reference |
| Audio setting | `--audio-setting` | Video edit only: `auto` or `origin` |
| Seed | `--seed` | Optional; for reproducing a result |
PixVerse-specific flags: `--capability`, `--quality` (360p/540p/720p/1080p), `--aspect-ratio` (9:16/16:9/1:1/4:3/3:4), `--source-video-id` / `--source-task-id`, `--audio`, `--agent-type`, `--restyle-id`, and `--pixverse-json` for nested payloads (`tts`, `imageReferences`, `multiTransition`).
> Some choices are auto-corrected: 480p on HappyHorse falls back to 720p; 1080p on `doubao-seedance-2-fast` upgrades to `doubao-seedance-2-pro`. The AI tells you when it adjusts.
Estimating credits [#estimating-credits]
Before generating, the AI runs an estimate. To check cost yourself, mirror the create parameters against the estimate command:
```bash
# HappyHorse / SeeDance
listenhub video estimate --model "happyhorse" --resolution "1080p" --ratio "16:9" --duration 5 --json
# PixVerse — mirror the capability + quality + duration
listenhub openapi video pixverse estimate --capability text_to_video --model pixverse --quality 720p --duration 5 --json
```
For video edit, add `--has-video-input` and `--input-video-duration `.
Output [#output]
Status flows `pending` → `generating` → `uploading` → `success`. On success the AI reports the video URL, duration, resolution, ratio, seed, and credits charged.
Output behavior follows the `outputMode` set during config:
* **`inline` (default) or `both`** — the video URL and metadata are shown directly in the conversation.
* **`download` or `both`** — the file is also saved to the current working directory with a topic-based name (e.g. `cyberpunk-city.mp4`). Names are de-duplicated automatically.
To review past work, `listenhub video get --json` returns a single task and `listenhub video list --json` lists recent tasks. Global flags apply: `--json` / `-j`, `--no-wait`, and `--timeout `.
API Reference [#api-reference]
See the [AI Video API reference](/docs/en/openapi/api-reference/ai-video) for endpoint paths, request parameters, and response fields.
# Reference Image (/docs/en/skills/advanced/reference-image)
A text prompt is not always precise enough. The reference image feature lets you supply an image as a style anchor: the AI picks up its style, palette, and composition, then generates a new variant from your prompt.
When you need a series of images built on an existing visual style, a reference image is far more precise than describing that style in words.
Uploading a Reference Image [#uploading-a-reference-image]
The reference image needs a publicly accessible URL. The simplest route is a free image host such as [postimages.org](https://postimages.org) — upload the image, then copy the **direct link** (not the share link, which points at a viewer page):
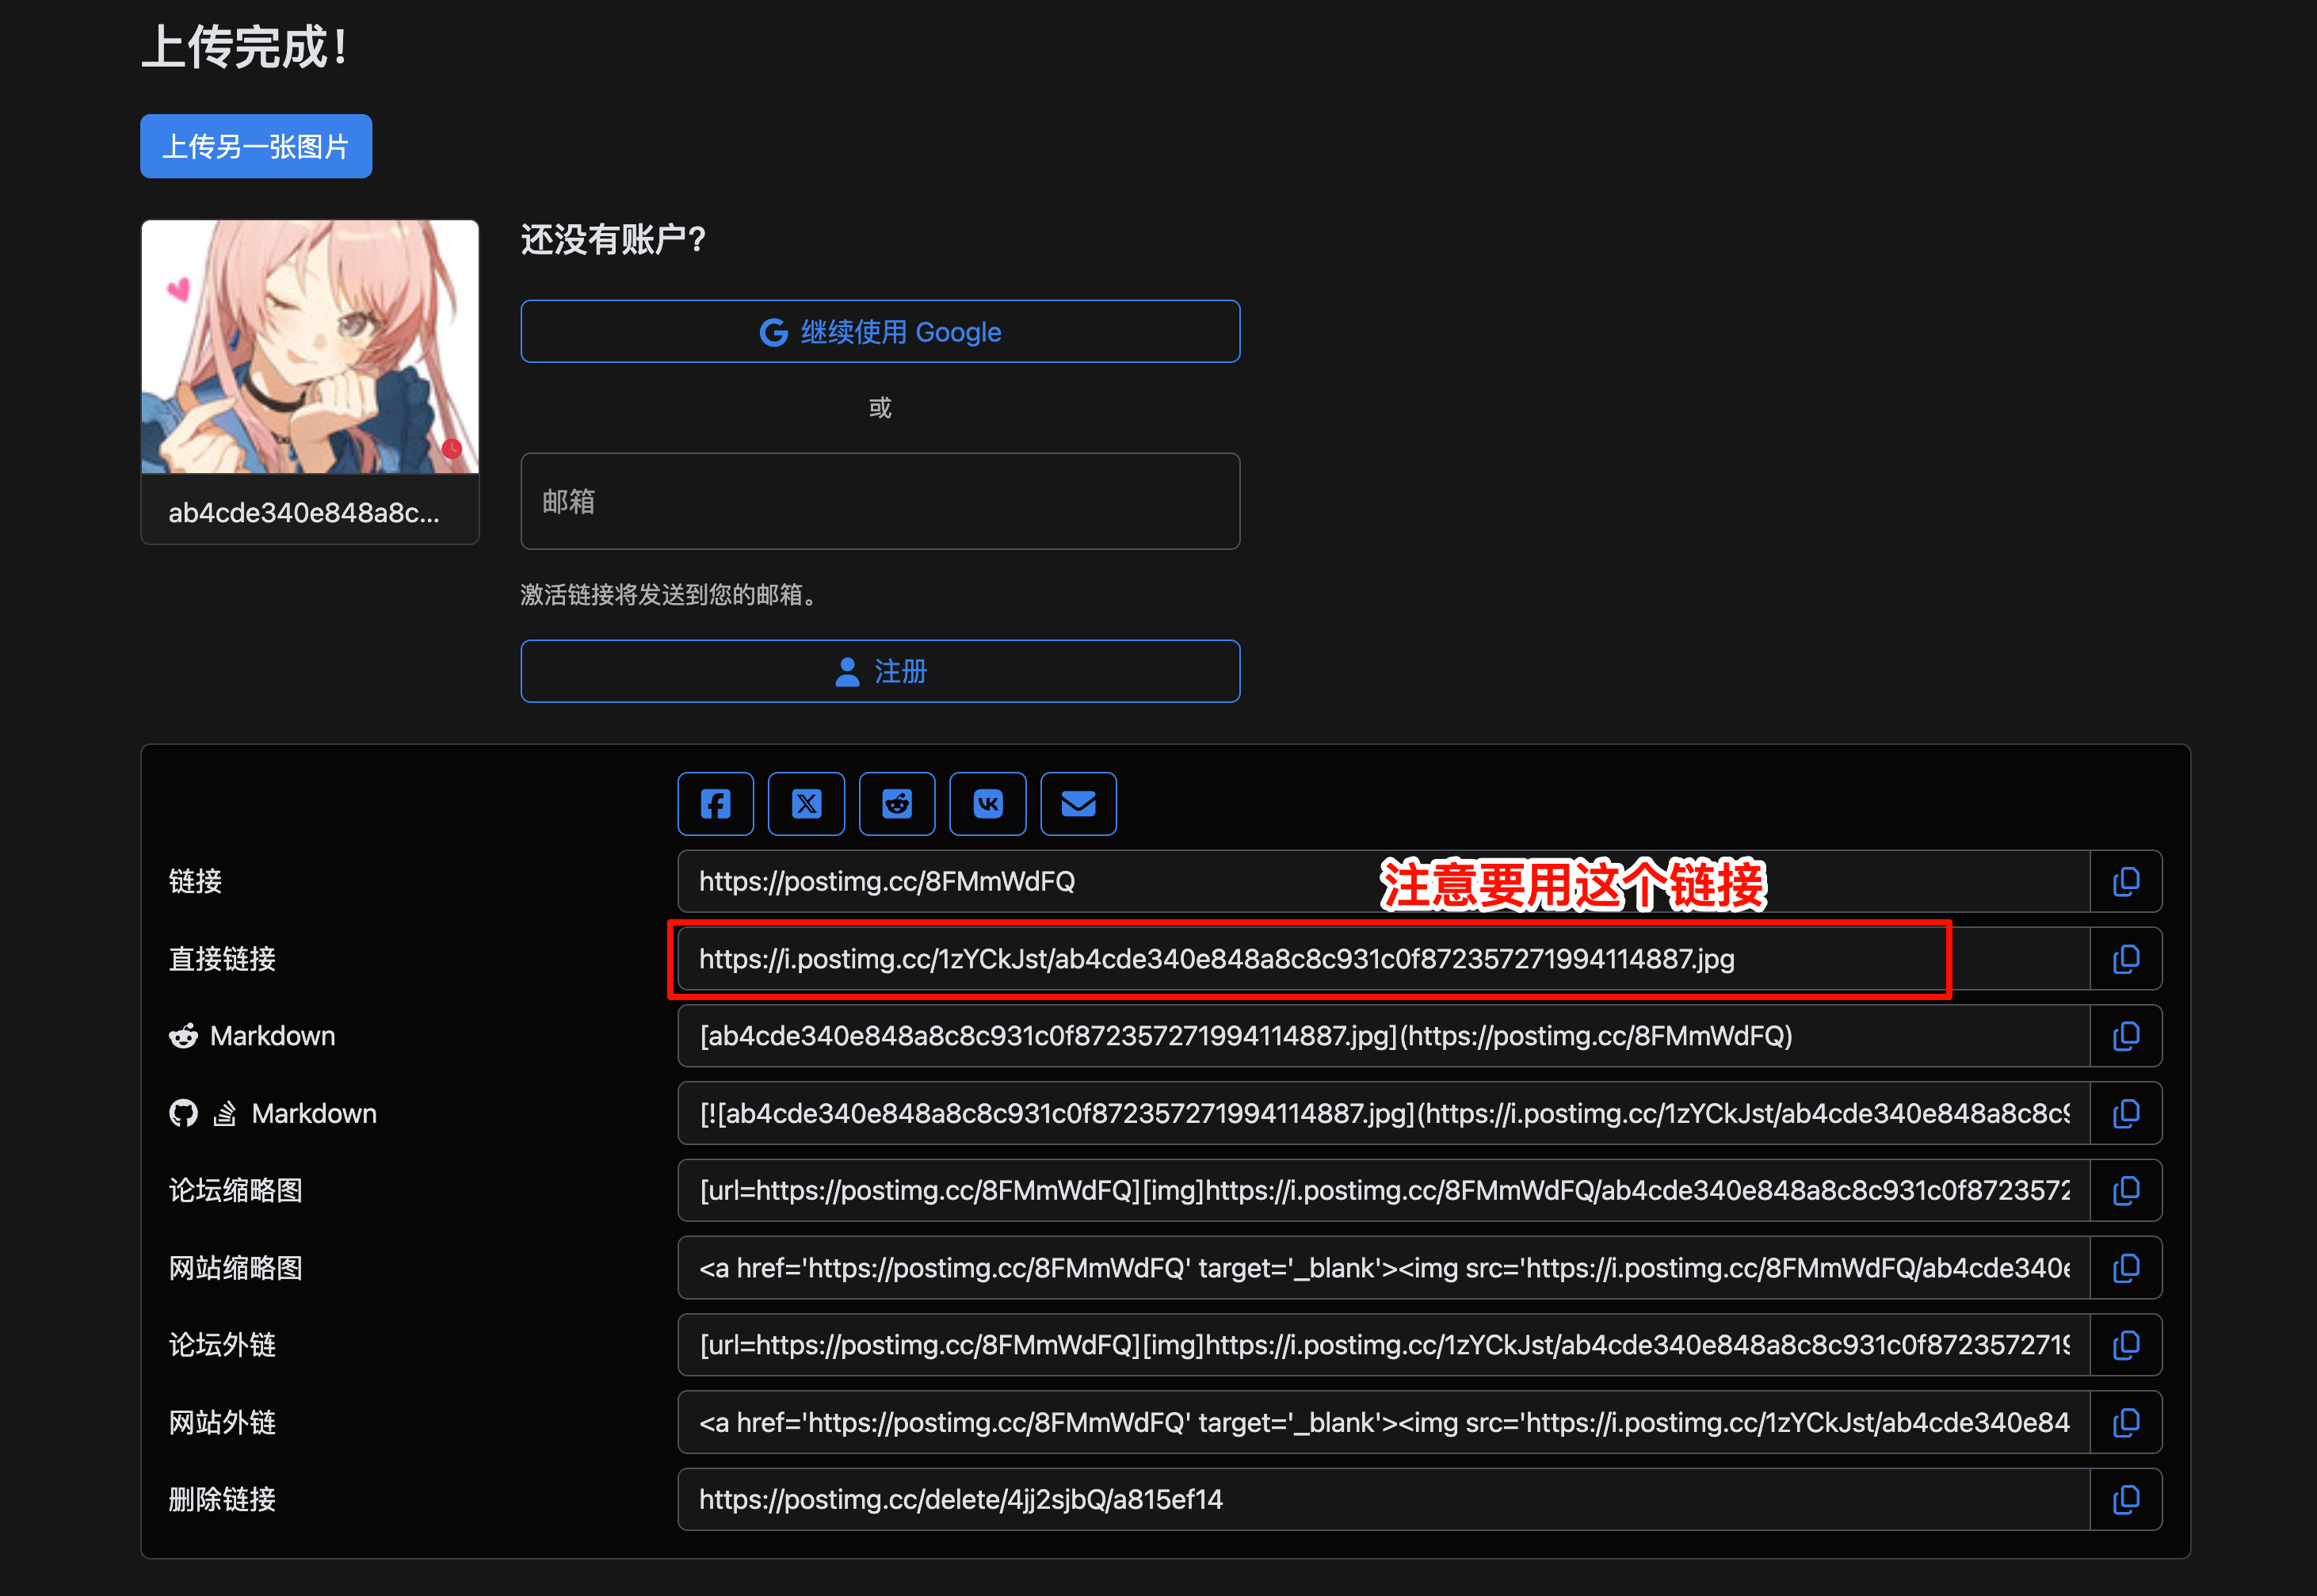 > The reference image must be reachable at a public URL. A local file path will not work — upload the file first and use the resulting link. Common hosts: imgbb.com, sm.ms, postimages.org.
Starting a Generation Request [#starting-a-generation-request]
Send the reference image link together with what you want made. In this example the reference is an anime character illustration, and the request is a derivative meme:
 The AI recognises this as a reference-image generation request, uses the reference for style and expression, and combines it with the prompt to produce a new image.
Generation Complete [#generation-complete]
After about a minute the image is ready. The AI reports the file location, resolution, and how the image was produced:
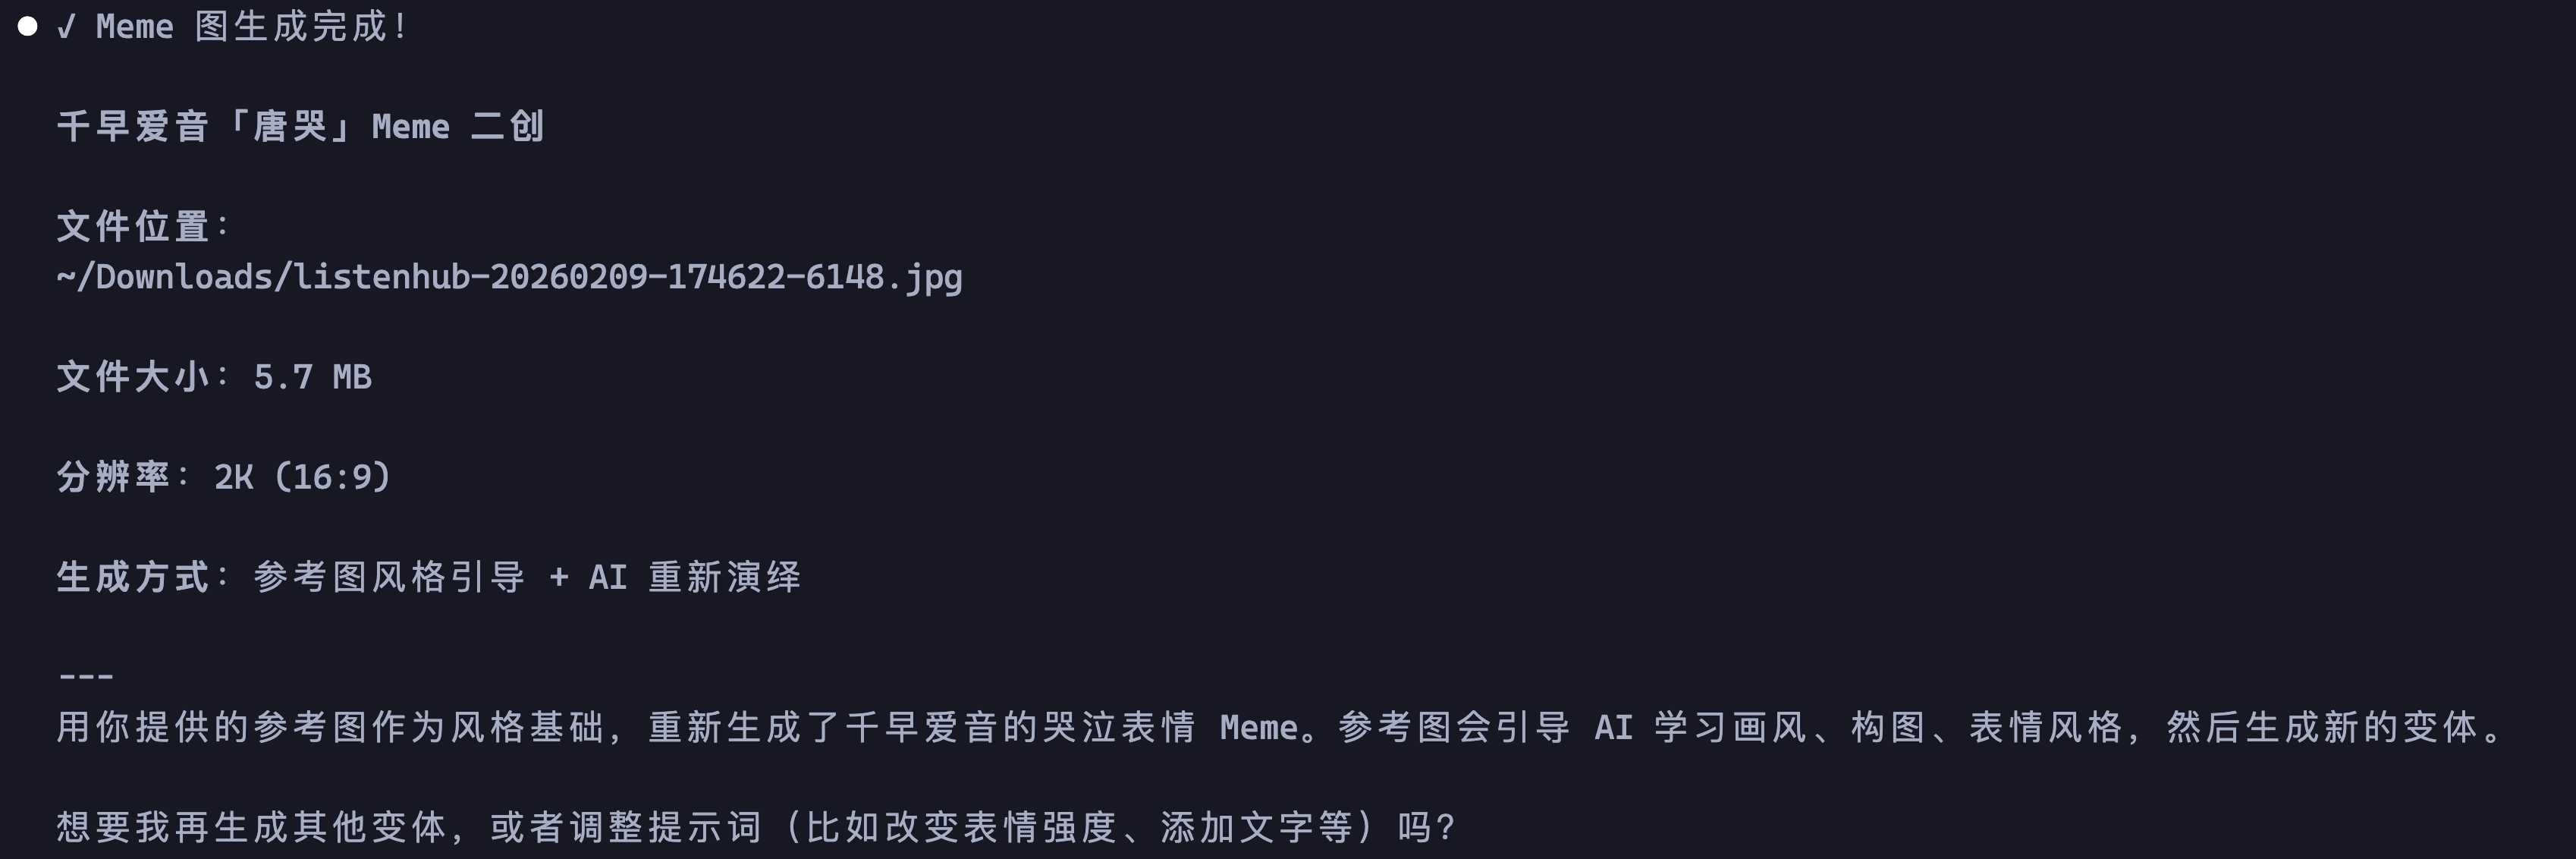 Result [#result]
The finished meme — the AI picked up the style and facial expression from the reference and reinterpreted them as a new variant:
 For programmatic access with URL or base64 reference images, see the [Image Generation API reference](/docs/en/openapi/api-reference/image-generation).
# Script-First Podcast (/docs/en/skills/advanced/script-first-podcast)
A standard podcast request goes straight through: topic in, wait, audio out. That is fast, but there is no point at which you can read what the hosts are about to say.
Script-first mode splits the job in two: **generate the script, review and edit it, then generate the audio**. Use it for episodes you intend to publish, content where wording matters, and any workflow that needs a review pass before rendering.
Starting a Request [#starting-a-request]
Tell the AI you want to use script-first mode. It explains the trade-off before starting — the script is produced first so you can review and edit it before any audio is rendered:
 Stage One: Script Generation [#stage-one-script-generation]
The AI submits a script-generation task and returns an Episode ID. This stage produces text only — no audio is rendered yet:
 After a few minutes, the AI polls the status and reports the finished script: title, word count, and structure, along with two paths — render audio now, or review and edit first:
 Reviewing the Script [#reviewing-the-script]
Choose the review path and the AI lays out the full structure — in this example roughly 5,000 words across 10 sections, with the topic and central argument of each section visible at a glance:
 It also prints a detailed section outline with an editing entry point, so you can cut, add, or reorder any part:
 The review note in this example was "keep the structure, but make it tighter and more conversational". The AI condensed the 5,000-word academic draft into a 1,500-word dialogue script, which suits the pacing of something meant to be heard rather than read.
Stage Two: Audio Generation [#stage-two-audio-generation]
Once the revised script is approved, stage two begins. The AI starts audio generation from the condensed 27-line dialogue script:
 Finished Episode [#finished-episode]
Two to three minutes later the audio is ready. The AI returns a listening link, an audio download URL, and a subtitle file, along with a summary of what ran at each stage:
 Direct vs. Script-First [#direct-vs-script-first]
The core difference between the two modes:
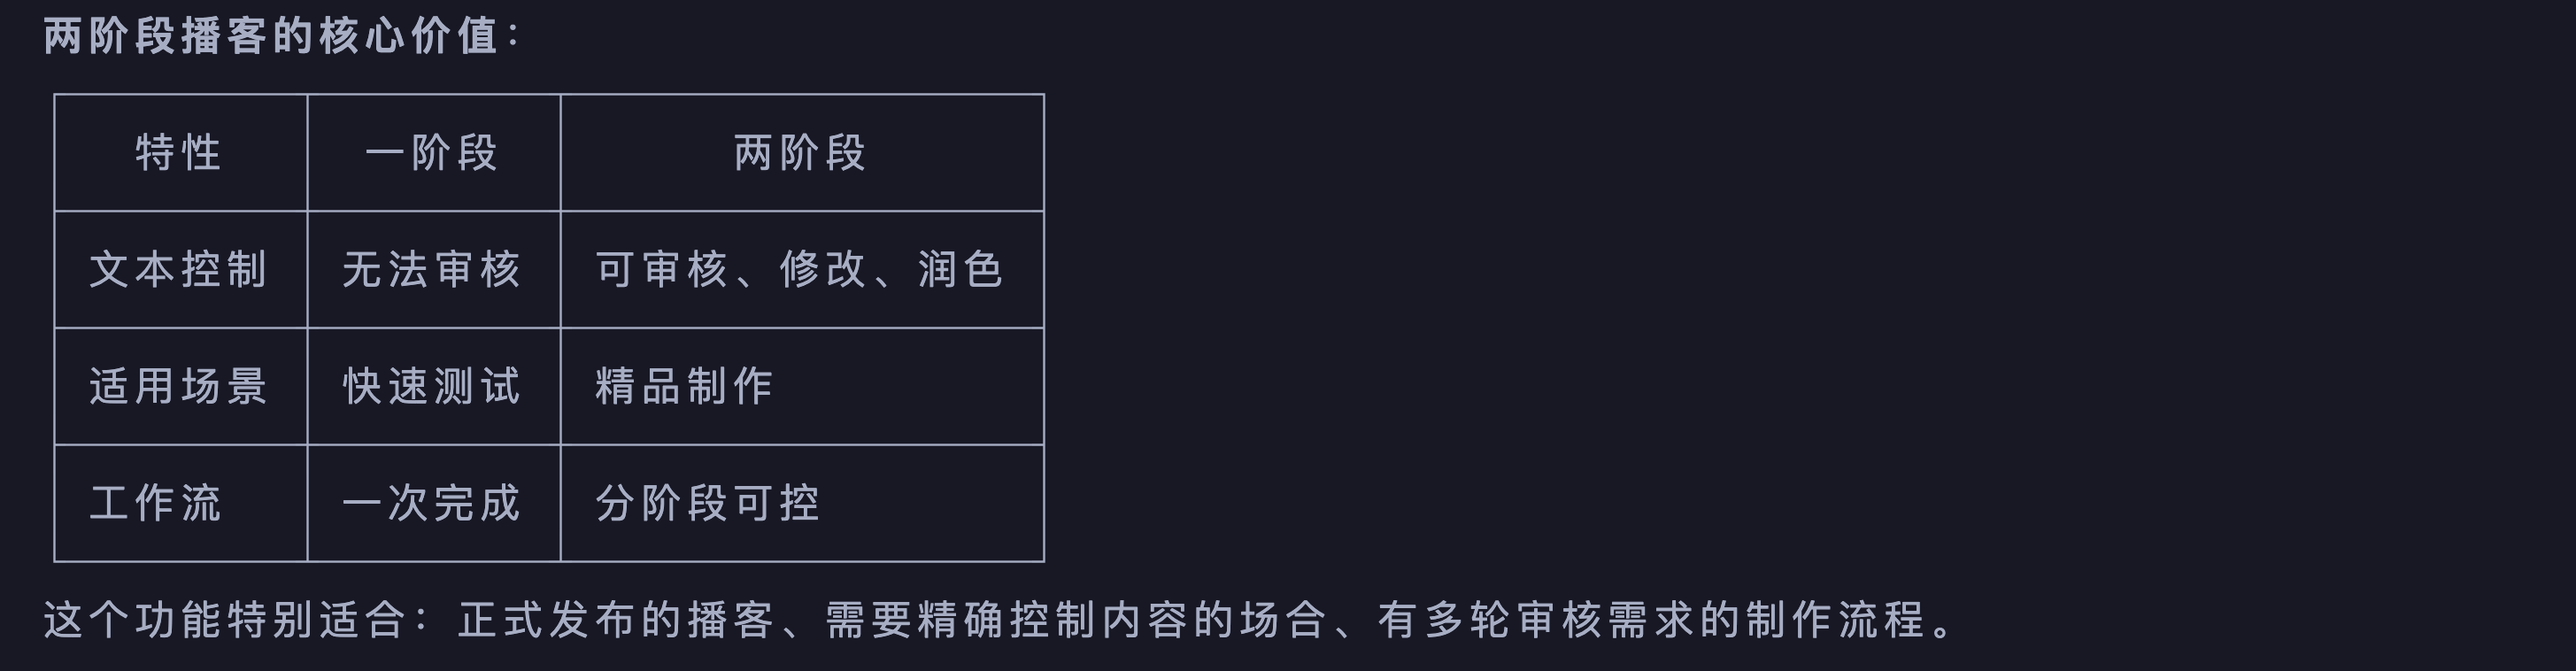 Use direct generation to test an idea quickly; use script-first when the episode is going to be published or the content matters.
The full workflow:
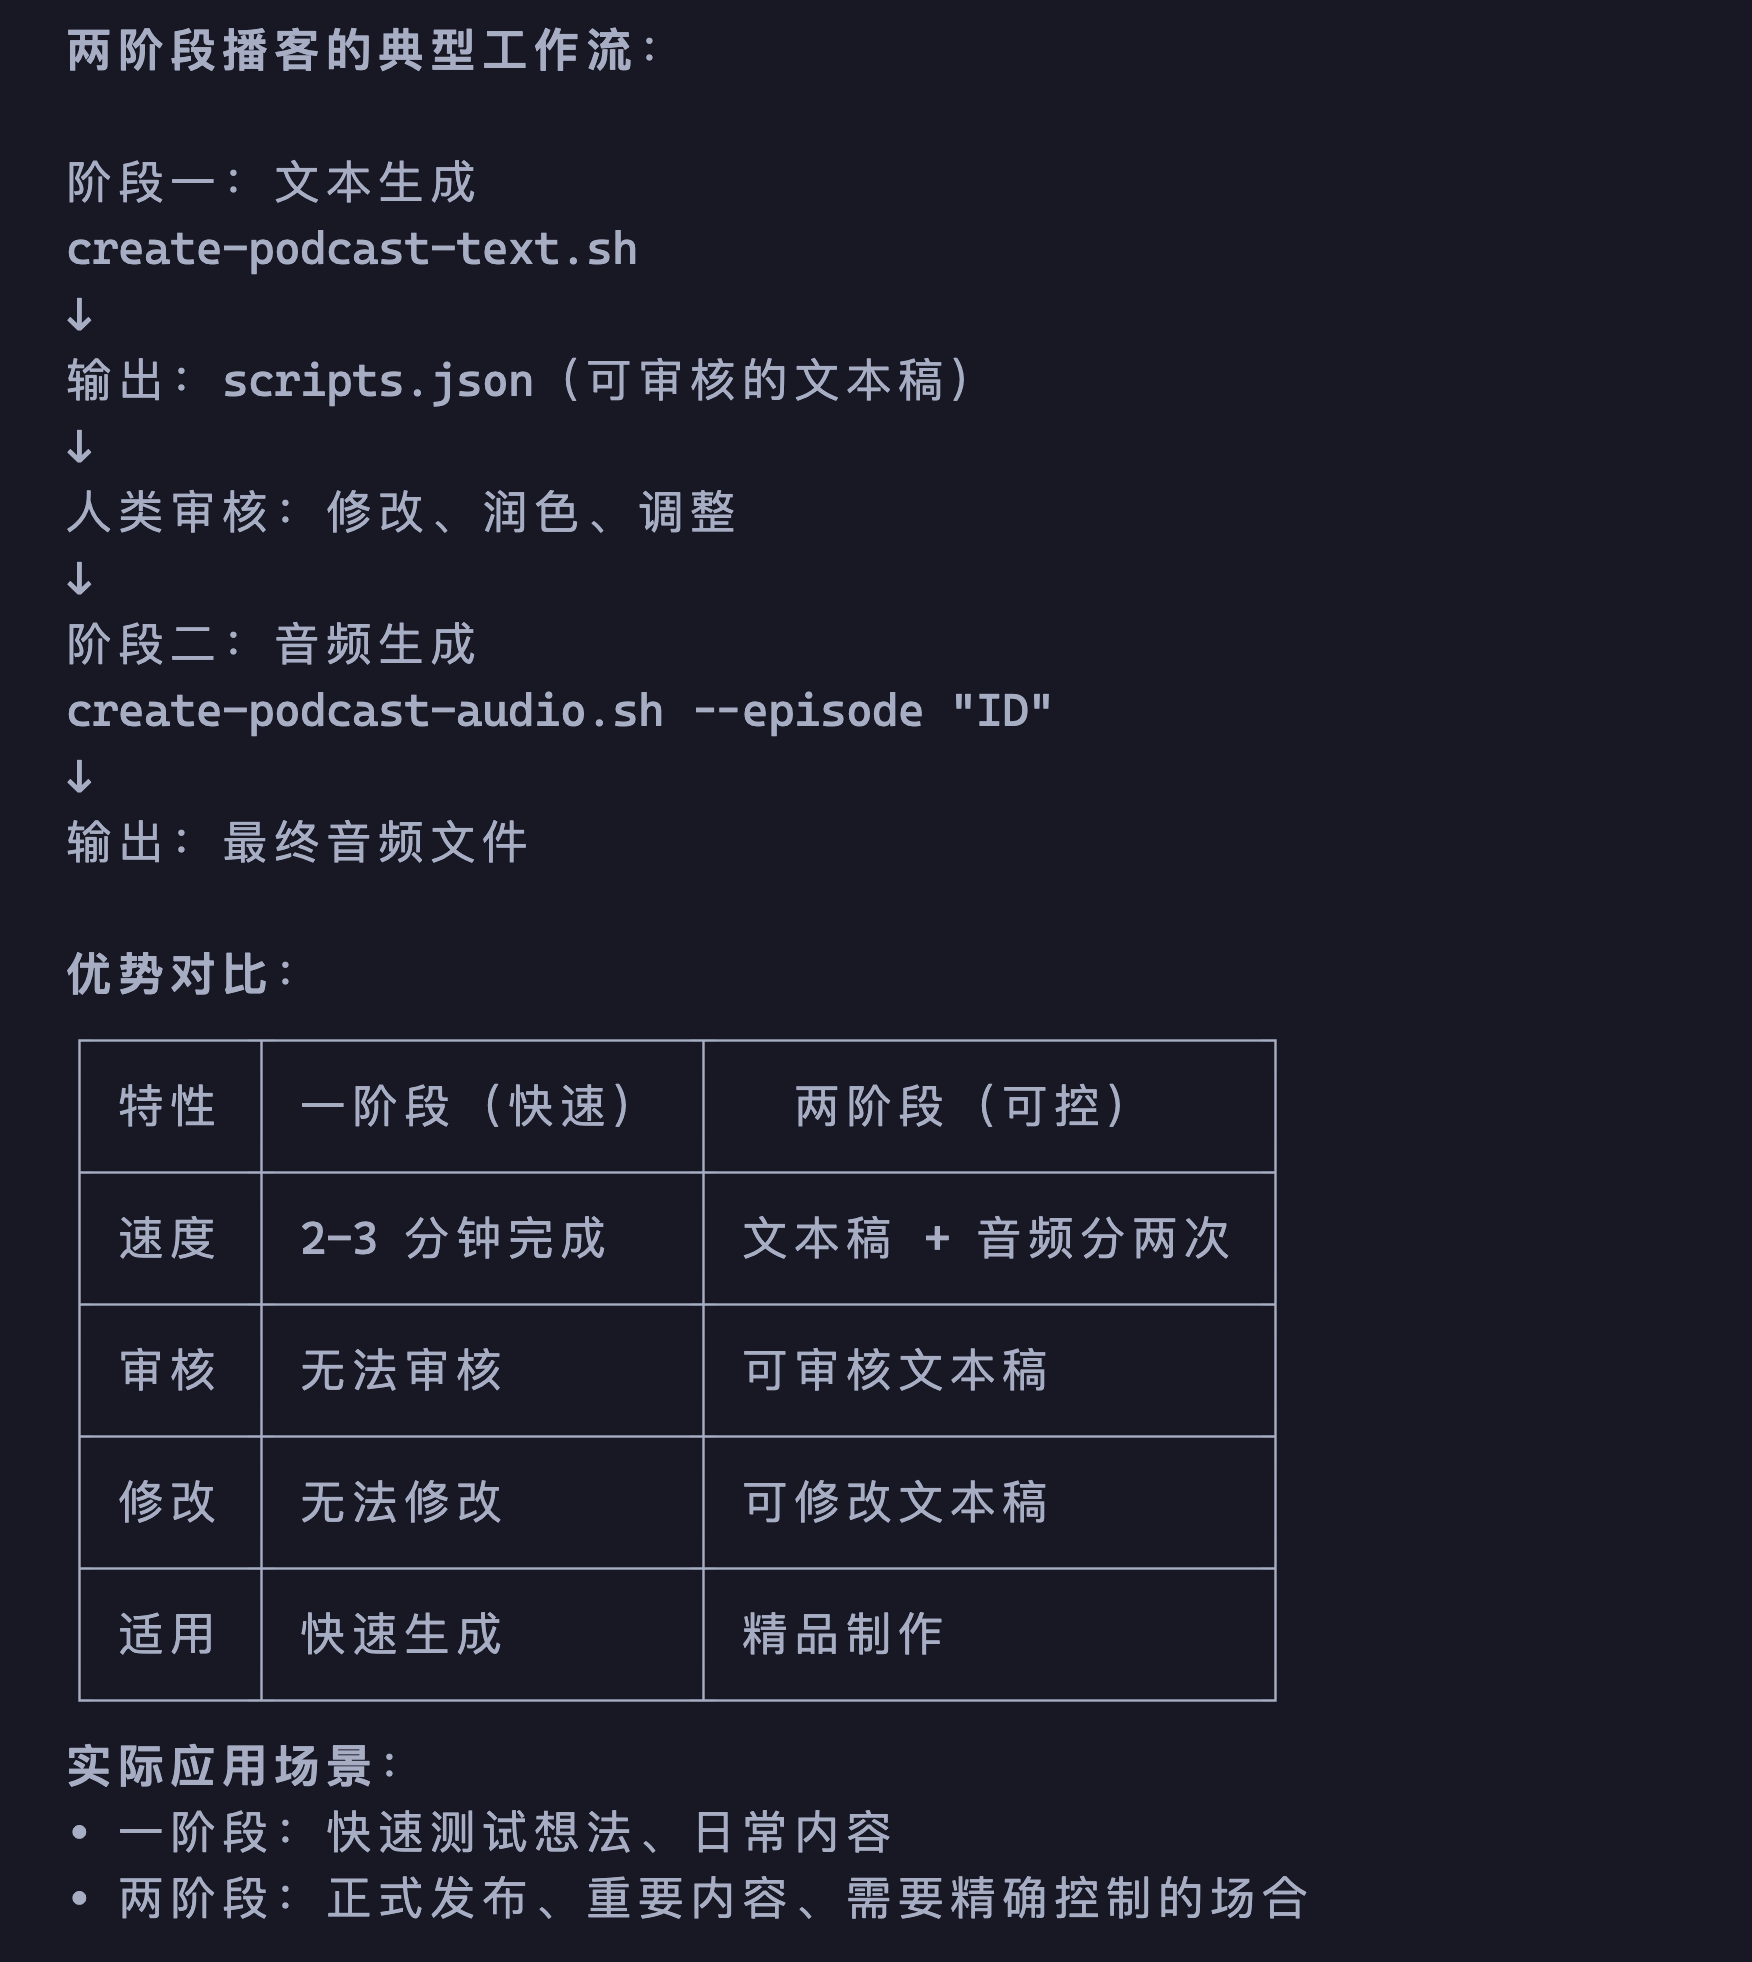 For the underlying two-stage API, see the [Podcast API reference](/docs/en/openapi/api-reference/podcast).
# Multi-Voice Scripts (/docs/en/skills/advanced/tts)
Basic TTS is one block of text read by one voice. A multi-voice script instead gives you **line-by-line control over who speaks** — a three-way debate, dialogue from a novel, or a teaching scenario where each character has their own voice and lines.
Starting a Request [#starting-a-request]
Tell the AI you want to use a multi-voice script. It builds a multi-character dialogue and assigns a distinct voice to each speaker. In this example:
* **Su Zhe** (measured male voice) — host, handles the opening and the main argument
* **Ruo Yun** (warm female voice) — questioner, surfaces the tension and works through it
* **Yuan Ye** (Beijing-accented male voice) — closer, delivers the philosophical wrap-up
 Script Structure [#script-structure]
The generated script is a plain JSON file. Each line specifies `content` (what is said) and `speakerId` (which voice says it), and lines are read in array order:
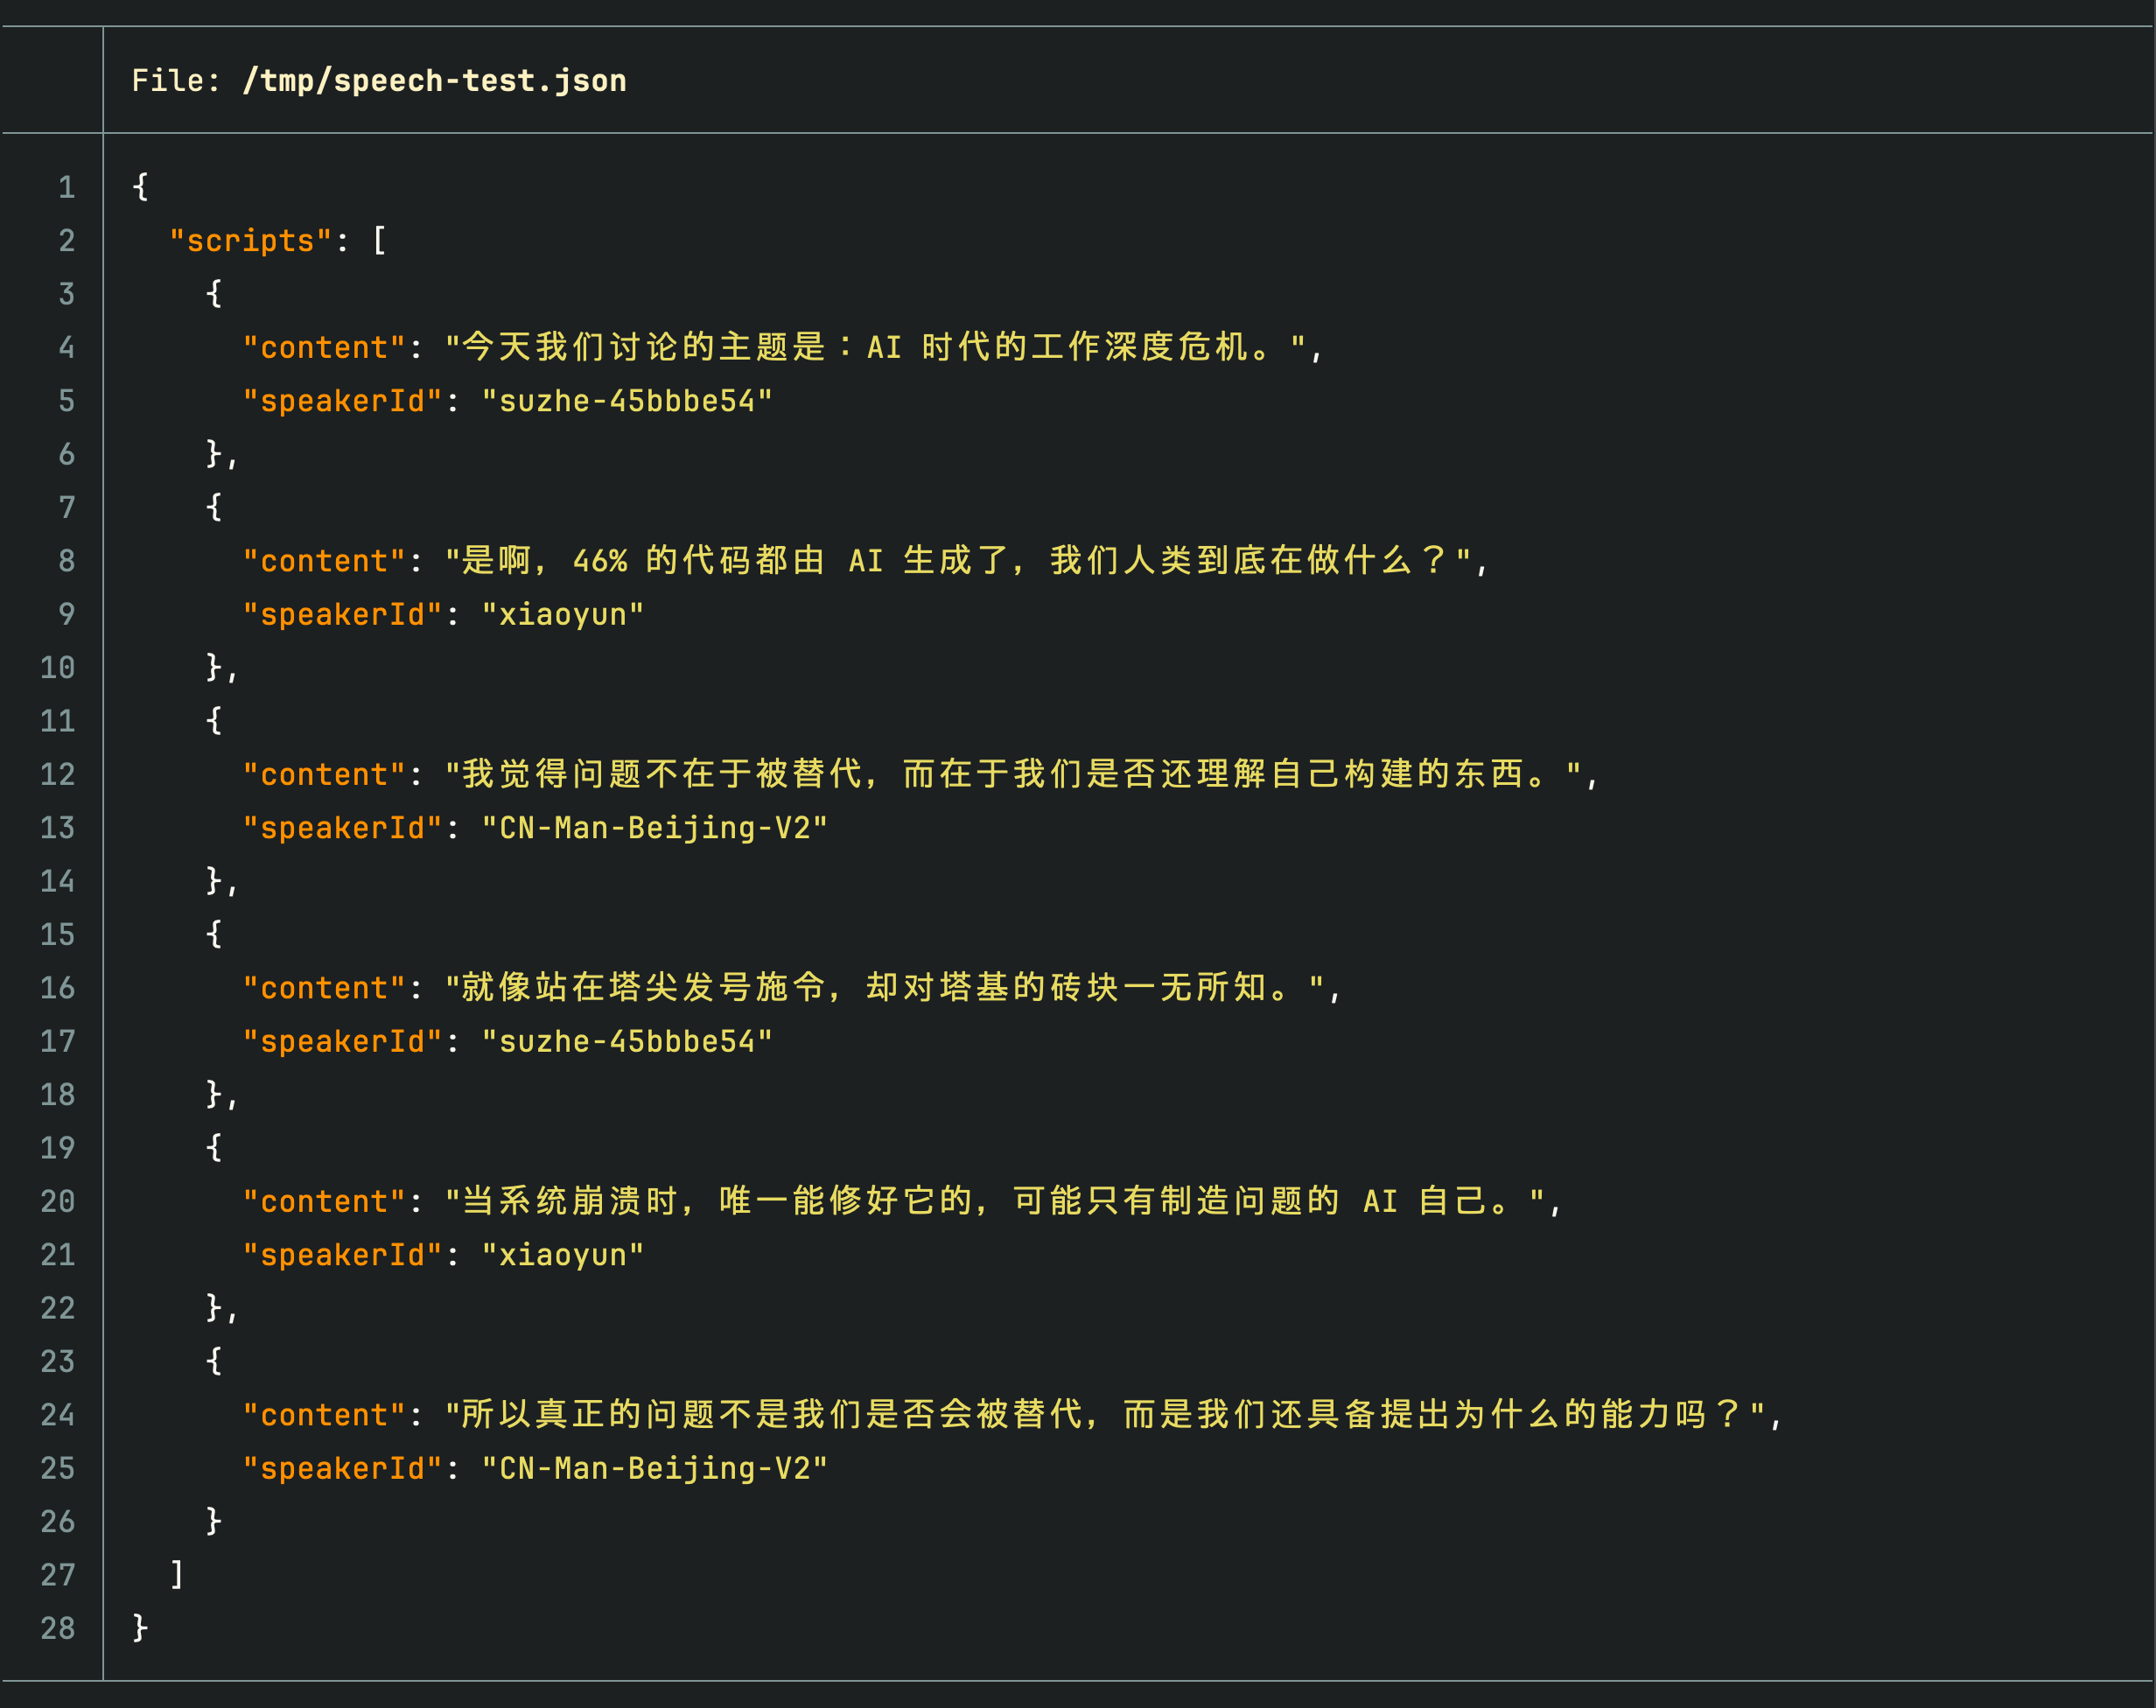 The point of this structure is that it is **fully deterministic** — two people alternating, a three-way roundtable, or a monologue interleaved with narration are all just different arrangements of the same array. You can write the script by hand, or have the AI generate it from a description.
Finished Dialogue [#finished-dialogue]
Around 30 seconds after submission, the three-way dialogue is ready. The AI returns a listening link, a subtitle file, the voice lineup, and the dialogue structure:
 FlowTTS vs. Script [#flowtts-vs-script]
| Aspect | FlowTTS (single narrator) | Script (multi-voice) |
| ------------------- | ---------------------------- | ----------------------------- |
| Granularity | Whole text, one voice | Per line, multiple voices |
| Best for | Article narration, long text | Dialogue, scripts, audiobooks |
| Input format | Plain text | JSON (`scripts` array) |
| Arrangement control | Low | High |
For the underlying API, see the [Text to Speech API reference](/docs/en/openapi/api-reference/flowspeech).
# Best Practices (/docs/en/skills/guides/best-practices)
These tips help you get higher quality results from ListenHub Skills.
General Tips [#general-tips]
Be Specific [#be-specific]
The more context you provide, the better the output.
| Vague | Specific |
| ------------------- | -------------------------------------------------------------------------- |
| "Make a podcast" | "Make a deep podcast about quantum computing in English with two speakers" |
| "Generate an image" | "Generate image: minimalist logo design for a coffee shop, 1:1, 2K" |
| "Read this" | "Read this article aloud in English, direct mode" |
Specify Language Early [#specify-language-early]
If you want content in a specific language, state it upfront. The AI auto-detects language from your input, but explicit is better.
```
Make a podcast about AI trends, in English
```
Use Two-Step Generation for Important Content [#use-two-step-generation-for-important-content]
For content that matters, use two-step generation to review and refine before final output:
* **Podcast**: "Make a podcast, let me review the script first"
* **Explainer Video**: Request "text only" first, review, then generate video
Podcast Tips [#podcast-tips]
* **Quick mode** for news and summaries, **Deep mode** for educational content
* **Debate mode** works best with controversial or two-sided topics
* Providing URLs as reference material produces more grounded, factual content
* Two-step generation lets you condense long scripts or adjust tone
Image Tips [#image-tips]
* Write prompts in **English** for best results (the model is trained on English)
* Include style keywords: "photorealistic", "watercolor", "minimalist"
* Add quality modifiers: "highly detailed", "8K", "cinematic composition"
* Use **reference images** when you want consistent style across multiple generations
* Start with 2K resolution — it balances quality and generation speed
Speech Tips [#speech-tips]
* Use **direct mode** for well-formatted text (articles, prepared content)
* Use **smart mode** for rough drafts and notes
* For multi-speaker scripts, keep segments at natural sentence boundaries
* URL input works better than text input for long content (avoids the 10,000 character limit)
Content Parser Tips [#content-parser-tips]
* Clean up URLs before providing them — strip tracking parameters (`utm_*`, `vd_source=`)
* For Twitter/X profiles, specify a tweet count: "get last 50 tweets"
* Enable `summarize` when you only need key points, not full content
* Use as a preprocessing step before other skills for URL-based content
Troubleshooting [#troubleshooting]
| Problem | Solution |
| ----------------------- | ------------------------------------------------------------------------------- |
| Generation seems stuck | Wait up to 10 minutes — complex content takes time |
| Audio quality is poor | Try a different speaker voice |
| Wrong language output | Explicitly specify the language in your prompt |
| API key error | Re-check your key at [API Key Settings](https://listenhub.ai/settings/api-keys) |
| Image prompt in Chinese | The AI should translate automatically; if not, write in English |
For more issues, see the [Help & FAQ](/docs/en/skills/help) page.
# Composing Skills (/docs/en/skills/guides/composing-skills)
Skills are designed to work together. You can chain them in a single conversation to build complex content workflows.
How Composition Works [#how-composition-works]
Just describe what you want in natural language. The AI figures out which skills to invoke and in what order.
```
Parse this YouTube video and turn it into a podcast with two speakers
```
This triggers:
1. **Content Parser** — extracts the video transcript
2. **Podcast** — generates a two-speaker podcast from the extracted content
Common Workflows [#common-workflows]
URL to Podcast [#url-to-podcast]
```
Turn this article into a podcast: https://example.com/article
```
Content Parser extracts the article, then Podcast generates an episode from it.
URL to Explainer Video [#url-to-explainer-video]
```
Make an explainer video from this YouTube video: https://youtube.com/watch?v=...
```
Content Parser extracts the video transcript, then Explainer generates a narrated video with AI visuals.
Topic to Podcast + Cover Art [#topic-to-podcast--cover-art]
```
Make a podcast about AI ethics, then generate a cover image for it
```
Podcast generates the episode, then Image Generation creates cover art based on the topic.
Article to Speech [#article-to-speech]
```
Read this article aloud: https://example.com/long-article
```
Content Parser extracts the text, then Speech converts it to natural audio.
Research to Content [#research-to-content]
```
Extract tweets from @elonmusk (last 50), summarize them, and make a podcast about the key themes
```
Content Parser fetches the tweets, then Podcast generates an episode covering the major themes.
Tips [#tips]
* **Be explicit about the chain** — "parse this URL and then make a podcast" is clearer than just providing a URL
* **Specify parameters for each step** — "parse this article, then make a deep podcast in English with two speakers"
* **Review intermediate results** — you can ask to see the extracted content before generating the podcast
* **One conversation** — all skills execute within the same conversation, maintaining context between steps
# Available Tools (/docs/en/mcp/available-tools)
The ListenHub MCP server exposes 8 tools. Each tool wraps an OpenAPI endpoint and returns the unwrapped `data` payload on success. Underlying responses follow the standard envelope `{ "code": 0, "message": "", "data": { ... } }`; a non-zero `code` indicates an error.
> Podcasts accept 1 to 2 speakers. `debate` mode is a two-host format and needs 2 speaker IDs. FlowSpeech is single-speaker (1 speaker). Languages are `zh` or `en`.
Speaker Lookup [#speaker-lookup]
get_speakers [#get_speakers]
Returns the available speakers for podcast and FlowSpeech generation, including voice ID, name, language, gender, demo audio link, and a voice profile.
**Inputs**
* `language`: filter by language code, `zh` or `en` (string, optional)
**Response**
Returns an `items` array. Each item carries a `speakerId` (use this value for `speakerIds` / `speakerId` in the other tools).
```json
{
"items": [
{
"name": "Aria",
"speakerId": "sp_aria_en",
"demoAudioUrl": "https://storage.googleapis.com/.../aria-demo.mp3",
"gender": "female",
"language": "en",
"profile": {
"pitch": ["medium", "medium-high"],
"speed": ["medium-fast"],
"traits": ["clear", "bright", "warm"],
"styles": ["friendly", "narrative"],
"scenes": ["podcast", "audiobook"],
"accent": "American English",
"description": "Warm, conversational host voice.",
"descriptionLocalized": { "zh": "温暖、口语化的主持人声音。" }
}
}
]
}
```
Podcast Generation [#podcast-generation]
create_podcast [#create_podcast]
Creates a full podcast (text + audio). Polls automatically until completion, which can take several minutes.
**Inputs**
* `query`: topic or content prompt (string, optional)
* `sources`: array of text/URL sources (array, optional)
* `speakerIds`: 1 to 2 speaker IDs (array, required). Provide 2 IDs for `debate` mode.
* `language`: language code `zh` or `en` (string, optional, default: `en`)
* `mode`: generation mode `quick`, `deep`, or `debate` (string, optional, default: `quick`)
Provide at least one of `query` or `sources`.
**Response**
Because this tool polls to completion, it returns the full podcast detail (the same shape as `get_podcast_status`). A representative completed payload:
```json
{
"episodeId": "664e0c2b9f1a2b3c4d5e6f70",
"createdAt": 1716460000000,
"processStatus": "success",
"contentStatus": "audio-success",
"completedTime": 1716460320000,
"credits": 12,
"title": "How LLMs Changed Search",
"outline": "1. The shift from keywords...",
"cover": "https://storage.googleapis.com/.../cover.png",
"audioUrl": "https://storage.googleapis.com/.../episode.mp3",
"audioStreamUrl": "https://storage.googleapis.com/.../episode-stream.mp3",
"subtitlesUrl": "https://storage.googleapis.com/.../episode.srt",
"scripts": [
{ "speakerId": "sp_aria_en", "speakerName": "Aria", "content": "Welcome back to the show." },
{ "speakerId": "sp_leo_en", "speakerName": "Leo", "content": "Today we're digging into search." }
]
}
```
get_podcast_status [#get_podcast_status]
Returns current podcast details immediately, without polling.
**Inputs**
* `episodeId`: podcast episode ID (string, required)
**Response**
Same shape as the completed `create_podcast` payload above. While generation is in progress, `processStatus` reflects the current state and content fields (`audioUrl`, `scripts`, and so on) may be absent until the corresponding phase finishes. `contentStatus` is one of `text-success`, `text-fail`, `audio-success`, or `audio-fail`.
```json
{
"episodeId": "664e0c2b9f1a2b3c4d5e6f70",
"createdAt": 1716460000000,
"processStatus": "processing",
"contentStatus": "text-success",
"credits": 0,
"title": "How LLMs Changed Search",
"outline": "1. The shift from keywords...",
"scripts": [
{ "speakerId": "sp_aria_en", "speakerName": "Aria", "content": "Welcome back to the show." }
]
}
```
create_podcast_text_only [#create_podcast_text_only]
Creates a text-only podcast (script, no audio). This is the first phase of the script-first workflow: generate the script, review or edit it, then call `generate_podcast_audio`.
**Inputs**
* `query`: topic or content prompt (string, optional)
* `sources`: array of text/URL sources (array, optional)
* `speakerIds`: 1 to 2 speaker IDs (array, required). Provide 2 IDs for `debate` mode.
* `language`: language code `zh` or `en` (string, required)
* `mode`: generation mode `quick`, `deep`, or `debate` (string, optional, default: `quick`)
* `waitForCompletion`: wait until text generation completes (boolean, optional, default: `true`)
Provide at least one of `query` or `sources`.
**Response**
Returns the new `episodeId` and a status message. When `waitForCompletion` is `true`, the tool waits for the script to finish before returning; query the script with `get_podcast_status`.
```json
{
"episodeId": "664e0c2b9f1a2b3c4d5e6f70",
"message": "Text content generation started. Audio generation can be triggered later."
}
```
generate_podcast_audio [#generate_podcast_audio]
Generates audio for an existing text-only podcast. This is the second phase of the script-first workflow.
**Inputs**
* `episodeId`: podcast episode ID (string, required)
* `customScripts`: custom scripts array (array, optional). Each entry has `content` (string) and `speakerId` (string). When omitted, the existing script is used.
* `waitForCompletion`: wait until audio generation completes (boolean, optional, default: `true`)
**Response**
Confirms that audio generation started. Poll `get_podcast_status` for the finished `audioUrl`.
```json
{
"success": true,
"message": "Audio generation started",
"episodeId": "664e0c2b9f1a2b3c4d5e6f70",
"status": "processing"
}
```
FlowSpeech Generation [#flowspeech-generation]
create_flowspeech [#create_flowspeech]
Creates FlowSpeech (single-speaker narration) from text or a URL. `smart` mode applies AI enhancement to the source; `direct` mode reads the content verbatim with no modification.
**Inputs**
* `sourceType`: source type `text` or `url` (string, required)
* `sourceContent`: source content — the text body or the URL (string, required). For `text`, the content must be at least 10 characters.
* `speakerId`: narration speaker ID (string, required). FlowSpeech uses exactly one speaker.
* `language`: language code `zh` or `en` (string, optional)
* `mode`: generation mode `smart` or `direct` (string, optional, default: `smart`)
**Response**
Returns the new `episodeId`. Generation runs asynchronously; poll with `get_flowspeech_status`.
```json
{
"episodeId": "664e0c2b9f1a2b3c4d5e6f71"
}
```
get_flowspeech_status [#get_flowspeech_status]
Returns current FlowSpeech details immediately, without polling.
**Inputs**
* `episodeId`: FlowSpeech episode ID (string, required)
**Response**
For FlowSpeech, `scripts` is a single string (the narration script), not the per-speaker array used by podcasts. Content fields appear as each phase finishes.
```json
{
"episodeId": "664e0c2b9f1a2b3c4d5e6f71",
"createdAt": 1716460000000,
"processStatus": "success",
"completedTime": 1716460120000,
"title": "Quarterly Product Update",
"outline": "1. Highlights...",
"cover": "https://storage.googleapis.com/.../cover.png",
"audioUrl": "https://storage.googleapis.com/.../flowspeech.mp3",
"audioStreamUrl": "https://storage.googleapis.com/.../flowspeech-stream.mp3",
"subtitlesUrl": "https://storage.googleapis.com/.../flowspeech.srt",
"scripts": "Welcome to the quarterly update. This quarter we shipped..."
}
```
User Subscription Lookup [#user-subscription-lookup]
get_user_subscription [#get_user_subscription]
Returns the current user's subscription and credit balances: plan details, monthly / permanent / limited-time credits, total available credits, renewal status, and subscription dates. Call this before generating to confirm you have enough credits.
**Inputs**
None.
**Response**
Timestamps are 13-digit milliseconds. `totalAvailableCredits` is the sum of the available monthly, permanent, and limited-time credits.
```json
{
"subscriptionStartedAt": 1714000000000,
"subscriptionExpiresAt": 1716592000000,
"usageAvailableMonthlyCredits": 480,
"usageTotalMonthlyCredits": 500,
"usageAvailablePermanentCredits": 100,
"usageTotalPermanentCredits": 100,
"usageAvailableLimitedTimeCredits": 0,
"totalAvailableCredits": 580,
"resetAt": 1716592000000,
"platform": "web",
"renewStatus": true,
"paidStatus": true,
"subscriptionPlan": {
"name": "Pro",
"duration": "monthly",
"platform": "web"
}
}
```
> Credit costs are not fixed per tool. To estimate cost before generating, use the relevant `*/estimate-credits` endpoints in the [OpenAPI reference](https://docs.marswave.ai/listenhub.html), and check live balances with `get_user_subscription`.
***
Thanks for using the ListenHub MCP server.
For support, contact: [support@marswave.ai](mailto:support@marswave.ai)
# Core Capabilities (/docs/en/mcp/core-capabilities)
The ListenHub MCP server exposes ListenHub's audio generation as MCP tools. Each tool wraps a public OpenAPI endpoint, so anything you can do here you can also do directly against the [OpenAPI](https://docs.marswave.ai/listenhub.html). For the exact tool names, inputs, and response shapes, see [Available Tools](/docs/en/mcp/available-tools).
Podcast generation [#podcast-generation]
Turn a topic or source material into a multi-speaker podcast (script plus audio).
* Full generation (script + audio) in one call, or text-only generation when you want to review the script first.
* 1 to 2 speakers. `debate` mode is a two-host format and requires 2 speaker IDs.
* Three modes: `quick`, `deep`, and `debate`.
* Script-first workflow: generate the script, edit it, then generate audio from your edited script.
* Content sources: a `query` prompt, text passages, or URLs (you can combine `query` and `sources`).
* Status polling returns title, outline, cover, audio URL, subtitles, per-speaker scripts, and credit usage.
Languages are `zh` or `en`.
FlowSpeech generation [#flowspeech-generation]
Turn text or a URL into single-speaker narration.
* `smart` mode applies AI enhancement to the source; `direct` mode reads the content verbatim.
* Source is `text` (at least 10 characters) or `url`.
* Exactly one speaker.
* Status polling returns title, outline, cover, audio URL, subtitles, the narration script, and credit usage.
Speaker discovery [#speaker-discovery]
Browse the voice library before you generate.
* List available speakers, optionally filtered by language.
* Each speaker carries a `speakerId`, name, language, gender, a demo audio link, and a voice profile (pitch, speed, traits, styles, scenes, accent).
* Use the returned `speakerId` for the `speakerIds` / `speakerId` inputs of the generation tools.
Account and credits [#account-and-credits]
Check your subscription and balances before generating.
* Plan details, renewal status, and subscription start / expiration dates.
* Available and total credits broken down by monthly, permanent, and limited-time buckets, plus `totalAvailableCredits`.
> Credit cost is not fixed per tool. To estimate cost before generating, use the relevant `*/estimate-credits` endpoints in the [OpenAPI reference](https://docs.marswave.ai/listenhub.html), and check live balances with the `get_user_subscription` tool.
Transports [#transports]
The server runs over **stdio** by default — the mode every MCP client (Claude Desktop, Cursor, and others) uses out of the box. For remote or shared setups, you can run it in **HTTP** mode, which exposes both a streamable HTTP endpoint (`/mcp`) and a Server-Sent Events endpoint (`/sse`). See [Transport Modes](/docs/en/mcp/transport-modes) for the details.
Next [#next]
- **Available Tools** -- Tool names, inputs, constraints, and response shapes. [/docs/en/mcp/available-tools](/docs/en/mcp/available-tools)
- **Usage Examples** -- Prompt-to-tool-call walkthroughs for the common flows. [/docs/en/mcp/usage-examples](/docs/en/mcp/usage-examples)
- **Transport Modes** -- stdio vs HTTP/SSE, and when to use each. [/docs/en/mcp/transport-modes](/docs/en/mcp/transport-modes)
# MCP Server (/docs/en/mcp)
The ListenHub MCP server lets an MCP client — Claude Desktop, Cursor, Windsurf, VS Code, Zed, and others — generate podcasts and FlowSpeech narration, browse voices, and check your account, all by calling tools. Each tool wraps a public ListenHub [OpenAPI](/docs/en/openapi) endpoint, so the MCP server and the API expose the same capabilities through different surfaces.
You authenticate with a ListenHub API key (`LISTENHUB_API_KEY`), created at [listenhub.ai/settings/api-keys](https://listenhub.ai/settings/api-keys). Generation consumes credits according to your plan.
Start here [#start-here]
- **Quick Start** -- Install Node.js, get an API key, and connect a client. [/docs/en/mcp/quick-start](/docs/en/mcp/quick-start)
- **Usage Examples** -- Prompt-to-tool-call walkthroughs for the common flows. [/docs/en/mcp/usage-examples](/docs/en/mcp/usage-examples)
- **Core Capabilities** -- What the server can do, at a glance. [/docs/en/mcp/core-capabilities](/docs/en/mcp/core-capabilities)
- **Transport Modes** -- stdio (default) vs HTTP/SSE, and when to use each. [/docs/en/mcp/transport-modes](/docs/en/mcp/transport-modes)
- **Available Tools** -- Every tool's inputs, constraints, and response shape. [/docs/en/mcp/available-tools](/docs/en/mcp/available-tools)
Other ways to call ListenHub [#other-ways-to-call-listenhub]
The MCP server is one way in. If you are building server-side or scripting, the same endpoints are available through the API and the official client libraries:
- **OpenAPI** -- The public REST API the MCP tools are built on. [/docs/en/openapi](/docs/en/openapi)
- **SDKs & CLI** -- Official JavaScript/TypeScript SDK and command-line tool. [/docs/en/tools](/docs/en/tools)
Who this is for [#who-this-is-for]
* Developers integrating ListenHub MCP into Claude Desktop, Cursor, Windsurf, VS Code, Zed, and other MCP clients.
* Teams that want podcast generation, FlowSpeech, speaker lookup, and subscription checks available as tools inside an AI assistant.
# Quick Start (/docs/en/mcp/quick-start)
[ListenHub](https://listenhub.ai/) provides an official MCP server for AI podcast generation (single or dual host), FlowSpeech narration, and related capabilities.
The MCP server is available to all ListenHub users with an API key. An API key is generated automatically for any ListenHub account — there is no plan gate to connect the server. Generating podcasts, FlowSpeech, and audio consumes credits according to your plan. Use the `get_user_subscription` tool, or the [`*/estimate-credits` endpoints](https://docs.marswave.ai/listenhub.html), to check balances and estimate cost before you generate.
Quick Start [#quick-start]
Environment Setup [#environment-setup]
Install Node.js first.
The MCP server requires Node.js 18 or newer. If Node.js is not installed yet, follow one of the options below.
* macOS
**Option 1: Official installer**
1. Visit the [Node.js website](https://nodejs.org/) and download an LTS release, for example [v24.11.0 (LTS)](https://nodejs.org/dist/v24.11.0/node-v24.11.0.pkg)
2. Open the downloaded `.pkg` file and follow the installer
3. Verify installation in terminal:
```bash
node --version
npm --version
```
**Option 2: Homebrew**
If [Homebrew](https://brew.sh/) is not installed, install it with:
```bash
/bin/bash -c "$(curl -fsSL https://raw.githubusercontent.com/Homebrew/install/HEAD/install.sh)"
```
Then install Node.js:
```bash
brew install node
```
Verify installation:
```bash
node --version
npm --version
```
* Windows
**Option 1: Official installer**
1. Visit the [Node.js website](https://nodejs.org/)
2. Download the Windows LTS version
3. Run the downloaded `.msi` installer
4. Follow the setup wizard
5. Verify installation in PowerShell:
```bash
node --version
npm --version
```
**Option 2: winget**
For Windows 10 version 1809 or newer:
```bash
winget install OpenJS.NodeJS.LTS
```
Verify installation:
```bash
node --version
npm --version
```
**Option 3: Chocolatey**
If Chocolatey is available:
```bash
choco install nodejs-lts
```
Verify installation:
```bash
node --version
npm --version
```
* Linux
**Ubuntu/Debian**
```bash
# Install Node.js 20.x (LTS)
curl -fsSL https://deb.nodesource.com/setup_20.x | sudo -E bash -
sudo apt-get install -y nodejs
```
**Fedora/RHEL/CentOS**
```bash
# Install Node.js 20.x (LTS)
curl -fsSL https://rpm.nodesource.com/setup_20.x | sudo bash -
sudo yum install -y nodejs
```
Verify installation:
```bash
node --version
npm --version
```
Get a ListenHub API key.
Create or view your API key on the [ListenHub API key settings page](https://listenhub.ai/en/settings/api-keys), then set it as the environment variable `LISTENHUB_API_KEY`. Keep the key on the server side — it grants full access to your account's credits.
Client Configuration Methods [#client-configuration-methods]
* Claude Desktop
Edit Claude Desktop config file:
**macOS**: `~/Library/Application Support/Claude/claude_desktop_config.json`
**Windows**: `%APPDATA%\\Claude\\claude_desktop_config.json`
Add:
```json
{
"mcpServers": {
"listenhub": {
"command": "npx",
"args": ["-y", "@marswave/listenhub-mcp-server@latest"],
"env": {
"LISTENHUB_API_KEY": "your_api_key_here"
}
}
}
}
```
Replace `your_api_key_here` with the real API key.
* Cursor
1. Open Cursor Settings
2. Navigate to **Features** -> **Model Context Protocol**
3. Click **Add MCP Server** or edit config file directly
Config file location:
* **macOS/Linux**: `~/.cursor/mcp.json`
* **Windows**: `%APPDATA%\\Cursor\\mcp.json`
Add:
```json
{
"mcpServers": {
"listenhub": {
"command": "npx",
"args": ["-y", "@marswave/listenhub-mcp-server@latest"],
"env": {
"LISTENHUB_API_KEY": "your_api_key_here"
}
}
}
}
```
Replace `your_api_key_here` with the real API key.
**Optional: HTTP transport mode**
Start server manually:
```bash
export LISTENHUB_API_KEY="your_api_key_here"
npx @marswave/listenhub-mcp-server --transport http --port 3000
```
Then configure Cursor:
```json
{
"mcpServers": {
"listenhub": {
"url": "http://localhost:3000/mcp"
}
}
}
```
* Windsurf
1. Open Windsurf Settings
2. Navigate to **MCP Servers**
3. Add a new server config
Config file location:
* **macOS/Linux**: `~/.windsurf/mcp_server_config.json`
* **Windows**: `%APPDATA%\\Windsurf\\mcp_server_config.json`
Add:
```json
{
"mcpServers": {
"listenhub": {
"command": "npx",
"args": ["-y", "@marswave/listenhub-mcp-server@latest"],
"env": {
"LISTENHUB_API_KEY": "your_api_key_here"
}
}
}
}
```
Replace `your_api_key_here` with the real API key.
* VS Code (with Cline extension)
1. Install [Cline extension](https://marketplace.visualstudio.com/items?itemName=saoudrizwan.claude-dev) from VS Code Marketplace
2. Open VS Code Settings
3. Search for `Cline: MCP Settings`
4. Click `Edit in settings.json`
Add:
```json
{
"cline.mcpServers": {
"listenhub": {
"command": "npx",
"args": ["-y", "@marswave/listenhub-mcp-server@latest"],
"env": {
"LISTENHUB_API_KEY": "your_api_key_here"
}
}
}
}
```
Replace `your_api_key_here` with the real API key.
* Zed
1. Open Zed Settings
2. Go to MCP section
3. Edit config file
Config file location:
* **macOS/Linux**: `~/.config/zed/mcp.json`
* **Windows**: `%APPDATA%\\Zed\\mcp.json`
Add:
```json
{
"mcpServers": {
"listenhub": {
"command": "npx",
"args": ["-y", "@marswave/listenhub-mcp-server@latest"],
"env": {
"LISTENHUB_API_KEY": "your_api_key_here"
}
}
}
}
```
Replace `your_api_key_here` with the real API key.
* Claude CLI
Run in terminal:
```bash
claude mcp add listenhub --env LISTENHUB_API_KEY= -- npx -y @marswave/listenhub-mcp-server
```
Replace `` with the real API key.
* Codex CLI
Run in terminal:
```bash
codex mcp add listenhub --env LISTENHUB_API_KEY= -- npx -y @marswave/listenhub-mcp-server
```
Replace `` with the real API key.
* ChatWise
1. Open ChatWise settings, choose MCP, and click `+` to add a new MCP service
2. Fill in MCP config fields:
 * **Command**: `npx -y @marswave/listenhub-mcp-server@latest`
* Enable **Run tools automatically**
* Add environment variable `LISTENHUB_API_KEY` with your key value
3. Enable tools from the chat input area and start using them
* Other MCP clients
For other MCP-compatible clients, use the standard MCP format:
```json
{
"mcpServers": {
"listenhub": {
"command": "npx",
"args": ["-y", "@marswave/listenhub-mcp-server@latest"],
"env": {
"LISTENHUB_API_KEY": "your_api_key_here"
}
}
}
}
```
Replace `your_api_key_here` with the real API key.
Next Steps [#next-steps]
- **Usage Examples** -- Prompt-to-tool-call walkthroughs for the common flows. [/docs/en/mcp/usage-examples](/docs/en/mcp/usage-examples)
- **Available Tools** -- The 8 MCP tools, their inputs, constraints, and response shapes. [/docs/en/mcp/available-tools](/docs/en/mcp/available-tools)
# Transport Modes (/docs/en/mcp/transport-modes)
The server supports two ways for a client to talk to it: **stdio** and **HTTP**. stdio is the default and what almost everyone should use. HTTP is for setups where the client and the server are not the same process.
Which one to use [#which-one-to-use]
| Mode | Use it when | How the client connects |
| --------------- | ----------------------------------------------------------------------------------------------------------------------------- | ------------------------------------------------- |
| stdio (default) | A desktop or editor client launches the server for you — Claude Desktop, Cursor, Windsurf, Zed, Cline, Claude CLI, Codex CLI. | `command` + `args` in the client config. |
| HTTP | The server runs separately (a remote host, a container, a shared dev box) and the client connects over a URL. | A `url` pointing at the server's `/mcp` endpoint. |
If you followed [Quick Start](/docs/en/mcp/quick-start), you are already on stdio — no extra configuration needed.
stdio mode (default) [#stdio-mode-default]
The client starts the server as a child process and exchanges messages over standard input/output. Every config sample in [Quick Start](/docs/en/mcp/quick-start) uses this mode. The pattern is always the same:
```json
{
"mcpServers": {
"listenhub": {
"command": "npx",
"args": ["-y", "@marswave/listenhub-mcp-server@latest"],
"env": {
"LISTENHUB_API_KEY": "your_api_key_here"
}
}
}
}
```
Because the client owns the process, it passes your API key through `env`. There is no port and no URL.
HTTP mode [#http-mode]
Run the server yourself and let clients connect over the network. HTTP mode exposes two endpoints from the same process:
* **Streamable HTTP** at `/mcp` — the endpoint most HTTP-capable MCP clients expect.
* **Server-Sent Events (SSE)** at `/sse` — for clients that use the SSE transport.
Start the server:
**macOS / Linux:**
```bash
export LISTENHUB_API_KEY="your_api_key_here"
npx @marswave/listenhub-mcp-server --transport http --port 3000
```
**Windows:**
```bash
set LISTENHUB_API_KEY=your_api_key_here
npx @marswave/listenhub-mcp-server --transport http --port 3000
```
With `--port 3000`, the endpoints are:
* Streamable HTTP: `http://localhost:3000/mcp`
* SSE: `http://localhost:3000/sse`
Point the client at the streamable HTTP endpoint:
```json
{
"mcpServers": {
"listenhub": {
"url": "http://localhost:3000/mcp"
}
}
}
```
> In HTTP mode the API key lives with the server process (the `LISTENHUB_API_KEY` you exported before starting it), not in the client config. Anyone who can reach the URL can spend your account's credits, so keep the server on a trusted network and do not expose it publicly without your own access control.
Next [#next]
- **Quick Start** -- Install Node.js, get an API key, and connect a client over stdio. [/docs/en/mcp/quick-start](/docs/en/mcp/quick-start)
- **Available Tools** -- Tool names, inputs, and response shapes. [/docs/en/mcp/available-tools](/docs/en/mcp/available-tools)
# Usage Examples (/docs/en/mcp/usage-examples)
These walkthroughs show what to say to an MCP client and which tool the client calls in response. The client picks tools and fills inputs from your prompt — you do not write the JSON yourself. The JSON below is what a reasonable call looks like, so you can see how a prompt maps to inputs. Tool names, full input lists, and response shapes are in [Available Tools](/docs/en/mcp/available-tools).
Screenshots [#screenshots]
Generate a Chinese podcast:
 Generate an English podcast:
 Podcast from a topic [#podcast-from-a-topic]
> "Make a short English podcast about how LLMs changed search. Use two hosts."
The client first discovers speakers, then calls `create_podcast` with two `speakerIds`. `create_podcast` polls to completion and returns the finished episode, so you get the audio URL in one step.
```json
{
"tool": "create_podcast",
"input": {
"query": "How LLMs changed search",
"speakerIds": ["sp_aria_en", "sp_leo_en"],
"language": "en",
"mode": "quick"
}
}
```
For a head-to-head, two-host argument, ask for a debate. `debate` mode requires exactly 2 speaker IDs:
```json
{
"tool": "create_podcast",
"input": {
"query": "Is remote work better than office work?",
"speakerIds": ["sp_aria_en", "sp_leo_en"],
"language": "en",
"mode": "debate"
}
}
```
Podcast from a URL [#podcast-from-a-url]
> "Turn this article into a podcast: [https://example.com/post](https://example.com/post)"
URLs and text passages go in `sources`. You can combine `sources` with a `query` to steer the framing.
```json
{
"tool": "create_podcast",
"input": {
"sources": ["https://example.com/post"],
"query": "Focus on the practical takeaways",
"speakerIds": ["sp_aria_en"],
"language": "en",
"mode": "deep"
}
}
```
A single speaker ID produces a solo episode. Provide at least one of `query` or `sources`.
FlowSpeech narration [#flowspeech-narration]
> "Read this announcement out loud, word for word."
FlowSpeech is single-speaker narration. Use `direct` mode to read the source verbatim, or `smart` mode to let the model polish it first. `create_flowspeech` returns an `episodeId` and runs asynchronously — the client then polls `get_flowspeech_status` for the audio.
```json
{
"tool": "create_flowspeech",
"input": {
"sourceType": "text",
"sourceContent": "This quarter we shipped three major features...",
"speakerId": "sp_aria_en",
"language": "en",
"mode": "direct"
}
}
```
To narrate a web page instead, set `sourceType` to `url` and put the link in `sourceContent`.
Script-first: review before audio [#script-first-review-before-audio]
> "Write the script for a podcast on prompt engineering, let me read it, then make the audio."
This is a two-step flow. First generate the script only:
```json
{
"tool": "create_podcast_text_only",
"input": {
"query": "An introduction to prompt engineering",
"speakerIds": ["sp_aria_en", "sp_leo_en"],
"language": "en",
"mode": "quick"
}
}
```
The client gets back an `episodeId`. Read the script with `get_podcast_status`, edit any lines, then generate audio. Pass your edits as `customScripts` so the audio matches your version:
```json
{
"tool": "generate_podcast_audio",
"input": {
"episodeId": "664e0c2b9f1a2b3c4d5e6f70",
"customScripts": [
{ "speakerId": "sp_aria_en", "content": "Welcome back. Today: prompt engineering." },
{ "speakerId": "sp_leo_en", "content": "Let's start with what a prompt actually is." }
]
}
}
```
Omit `customScripts` to generate audio from the script as-is.
Discover speakers [#discover-speakers]
> "What English voices are available?"
`get_speakers` returns the voice library. Filter by language to narrow it down. Each item carries a `speakerId` to feed into the generation tools.
```json
{
"tool": "get_speakers",
"input": {
"language": "en"
}
}
```
Check your subscription [#check-your-subscription]
> "Do I have enough credits to make a deep-dive podcast?"
`get_user_subscription` takes no inputs and returns your plan and credit balances. Call it before a long generation to confirm `totalAvailableCredits` covers it.
```json
{
"tool": "get_user_subscription",
"input": {}
}
```
> Credit cost is not fixed per tool. For a precise estimate before generating, use the relevant `*/estimate-credits` endpoints in the [OpenAPI reference](https://docs.marswave.ai/listenhub.html), then check live balances with `get_user_subscription`.
Next [#next]
- **Available Tools** -- Every tool's inputs, constraints, and response shape. [/docs/en/mcp/available-tools](/docs/en/mcp/available-tools)
- **Core Capabilities** -- The full capability scope at a glance. [/docs/en/mcp/core-capabilities](/docs/en/mcp/core-capabilities)
# Authentication & Security (/docs/en/openapi/authentication)
Base URL [#base-url]
All API requests are sent to:
```text
https://api.marswave.ai/openapi
```
> For sandbox/test environment access, contact [support@marswave.ai](mailto:support@marswave.ai).
API Key [#api-key]
Get an API Key [#get-an-api-key]
1. Go to [API Key settings](https://listenhub.ai/en/settings/api-keys)
2. Click **Create API Key**
3. Copy and save the key
Usage [#usage]
Include the API key in the `Authorization` header of every request:
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/speakers/list" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/speakers/list', {
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
},
});
```
**Python:**
```python
import os
import requests
response = requests.get(
'https://api.marswave.ai/openapi/v1/speakers/list',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
```
Set Up Environment Variable [#set-up-environment-variable]
Store your API key as `LISTENHUB_API_KEY`. All code examples in this documentation use this variable name:
```bash
# Add to ~/.zshrc or ~/.bashrc
export LISTENHUB_API_KEY="your_api_key_here"
```
Or create a `.env` file in your project root (requires a library like `dotenv` to load):
```bash
# .env
LISTENHUB_API_KEY=your_api_key_here
```
Security Best Practices [#security-best-practices]
> Your API key is equivalent to account credentials. A leaked key can result in unauthorized credit consumption.
* Always use HTTPS
* Keep API key out of client-side code
* Never commit API key or `.env` files to Git repositories
* Store API key in environment variables
Rate Limits [#rate-limits]
| Limit | Value | Description |
| --------------------- | ------- | ------------------------------------ |
| Creation request rate | 3 RPM | Up to 3 creation requests per minute |
| Exceeded limit error | `29998` | Implement a backoff retry strategy |
> Read-only requests (such as querying episode status or listing speakers) are not subject to this limit.
Next Steps [#next-steps]
* [Quick Start](/docs/en/openapi/quick-start) — Make your first call in 5 minutes
* [Core Concepts](/docs/en/openapi/concepts) — Learn about generation modes and data flow
* [Error Handling](/docs/en/openapi/errors) — Error code reference and troubleshooting
# Core Concepts (/docs/en/openapi/concepts)
Basic Concepts [#basic-concepts]
* **Episode** — The basic content unit in ListenHub. Each episode has a unique `episodeId` and contains audio, scripts, and metadata.
* **Speaker** — Defines the voice characteristics used for generation. Identified by `speakerId`, with attributes such as language and gender. Call `GET /v1/speakers/list` to browse available voices, or see the [Speakers API reference](/docs/en/openapi/api-reference/speakers).
Generation Modes [#generation-modes]
| Mode | Sub-mode | Description | Generation Time | API Endpoint |
| --------------------------------------------------------------------- | ---------- | ---------------------------------------------------------------------------------------------------------- | --------------- | -------------------------- |
| [**Podcast**](/docs/en/openapi/api-reference/podcast) | **quick** | Faster generation prioritizing efficiency; best for news briefs and time-sensitive content | 1-2 min | `/v1/podcast/episodes` |
| | **debate** | Two-host debate format; best for opinion discussions and multi-angle analysis | 2-4 min | |
| | **deep** | In-depth analysis with higher content quality; best for professional knowledge sharing and deep commentary | 2-4 min | |
| [**Text to Speech**](/docs/en/openapi/api-reference/flowspeech) | **smart** | AI optimizes content before synthesis; best for fixing awkward sentences and typos | 1-2 min | `/v1/flow-speech/episodes` |
| | **direct** | Direct text-to-speech conversion; best for well-prepared scripts and announcements | 1-2 min | |
| [**Content Extract**](/docs/en/openapi/api-reference/content-extract) | — | Async URL content extraction; best for article parsing, research, and content analysis | 10-30 sec | `/v1/content/extract` |
> Podcast mode supports 1-2 speakers (single or dual host). Debate mode requires exactly 2 speakers.
Output Types [#output-types]
Each generated episode provides two types of data: script text and audio files.
Script Stream (Server-Sent Events) [#script-stream-server-sent-events]
While audio is being generated, you can retrieve outline and script data via SSE without waiting for the audio to finish:
* **Podcast**: available 20-60 seconds after creation
* **Text to Speech**: available \~3 seconds after creation
Audio Files [#audio-files]
Once generation completes, the response includes:
| Field | Format | Description |
| ---------------- | ------ | ------------------------------------------ |
| `audioStreamUrl` | M3U8 | Streaming playback, best for real-time use |
| `audioUrl` | MP3 | Full file download, best for offline use |
Playground [#playground]
ListenHub provides an online Playground for testing multi-speaker speech synthesis without writing code.
**URL**: [Multi-speaker TTS Playground](https://assets.listenhub.app/listenhub-public-prod/static/playgroud-tts.html)
* Multi-role dialogue — generate audio with multiple voices in a single request
* Flexible assignment — assign a different speaker to each script line
* Instant preview — edit scripts online and listen to results immediately
Suitable for audiobook/radio drama production, conversational content generation, and rapid product demo creation.
Next Steps [#next-steps]
* [Quick Start](/docs/en/openapi/quick-start) — Make your first API call in 5 minutes
* [Authentication](/docs/en/openapi/authentication) — Base URL, API key, and rate limits
* [Podcast Generation API](/docs/en/openapi/api-reference/podcast) — Full parameters and response reference
# Error Handling (/docs/en/openapi/errors)
> All ListenHub API responses use HTTP 200 status codes. Success and failure are distinguished by the `code` field in the response body: `code = 0` means success, `code ≠ 0` means failure.
Error Code Reference [#error-code-reference]
| Error Code | Description | Suggested Action |
| --------------- | ------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **0** | Request succeeded | — |
| **21007** | Invalid API key | Check that the `Authorization` header format is `Bearer $LISTENHUB_API_KEY` and verify the key is copied correctly |
| **25002** | Resource not found | Verify the `episodeId` is correct |
| **25008** | Invalid episode state | Only occurs in the script-first workflow. Wait for script generation to complete before submitting audio synthesis. See [Podcast API reference](/docs/en/openapi/api-reference/podcast) |
| **26004** | Insufficient credits | Call `GET /v1/user/subscription` to check balance, then [purchase credits](https://listenhub.ai/en/pricing/pack?from=pricing) |
| **29003** | Invalid parameters | Validate request payload against the API reference |
| **29998** | Rate limit exceeded | Over the 3 RPM limit — implement backoff retry |
| **91001** | Input content too short | Increase input content length |
| **91002** | Content policy violation | Review content for compliance |
| **91003-91007** | Content generation errors | Check the `message` field for details |
> For unlisted non-zero error codes, check the `message` field in the response for details, or contact [support@marswave.ai](mailto:support@marswave.ai).
Error Response Format [#error-response-format]
All error responses follow the same JSON structure:
```json
{
"code": 21007,
"message": "Invalid API key",
"data": null
}
```
Common Troubleshooting [#common-troubleshooting]
**API key issues (21007)**:
1. Confirm the `Authorization` header format is `Bearer $LISTENHUB_API_KEY` (note the space after Bearer)
2. Confirm the API key is fully copied with no extra whitespace
3. Visit [API Key settings](https://listenhub.ai/en/settings/api-keys) to verify key status
**Rate limiting (29998)**:
1. Creation requests are limited to 3 per minute (3 RPM)
2. Read-only requests are not subject to this limit
3. Implement exponential backoff retry
Next Steps [#next-steps]
* [Authentication](/docs/en/openapi/authentication) — API key setup and security practices
* [Credits & Pricing](/docs/en/openapi/pricing) — Solutions for insufficient credit balance
* [Support](/docs/en/openapi/support) — Contact the support team
# ListenHub OpenAPI (/docs/en/openapi)
Get Started [#get-started]
1. Get Your API Key [#get-your-api-key]
Sign up and get your API key from the [settings page](https://listenhub.ai/settings/api-keys).
2. Make Your First Call [#make-your-first-call]
Follow the [Quick Start](/docs/en/openapi/quick-start) to complete your first podcast generation API call in under 5 minutes.
3. Get Your Results [#get-your-results]
Audio is generated asynchronously. Poll the task status to retrieve results when your content is ready.
What You Can Build [#what-you-can-build]
- **ListenHub Voice** -- End-to-end audio: narration, sound effects, dialogue, cloning, or image-to-audio [/docs/en/openapi/api-reference/listenhub-voice](/docs/en/openapi/api-reference/listenhub-voice)
- **Voice Cloning** -- Turn reference audio into a reusable private voice, then speak with it [/docs/en/openapi/api-reference/voice-clone](/docs/en/openapi/api-reference/voice-clone)
- **Podcast Generation** -- Full AI podcasts from text or URLs [/docs/en/openapi/api-reference/podcast](/docs/en/openapi/api-reference/podcast)
- **Text to Speech** -- Natural-sounding speech with AI enhancement or direct conversion [/docs/en/openapi/api-reference/flowspeech](/docs/en/openapi/api-reference/flowspeech)
- **Music Generation** -- Generate songs, instrumentals, and soundtracks, and analyze existing audio [/docs/en/openapi/api-reference/music](/docs/en/openapi/api-reference/music)
- **AI Video** -- Generate short videos from text, images, video references, and audio references [/docs/en/openapi/api-reference/ai-video](/docs/en/openapi/api-reference/ai-video)
- **Content Extraction** -- Pull structured content from web articles, tweets, and YouTube videos [/docs/en/openapi/api-reference/content-extract](/docs/en/openapi/api-reference/content-extract)
- **Speakers** -- Browse all available voice personas to find the right voice for your use case [/docs/en/openapi/api-reference/speakers](/docs/en/openapi/api-reference/speakers)
- **Subscription & Credits** -- Check your current credit balance and subscription status [/docs/en/openapi/api-reference/subscription](/docs/en/openapi/api-reference/subscription)
Reference [#reference]
- **SDKs & CLI** -- Official JavaScript/TypeScript SDK and command-line tool for the API [/docs/en/tools](/docs/en/tools)
- **Credits & Pricing** -- Credit types, consumption reference, and rate limits [/docs/en/openapi/pricing](/docs/en/openapi/pricing)
- **Error Codes** -- Error code reference and troubleshooting guide [/docs/en/openapi/errors](/docs/en/openapi/errors)
- **Support** -- Contact information and FAQ [/docs/en/openapi/support](/docs/en/openapi/support)
# Credits & Pricing (/docs/en/openapi/pricing)
Credits Overview [#credits-overview]
ListenHub uses a credit-based billing system. Credits can be used for all API features including AI podcast generation, text-to-speech, AI video, image generation, and content extraction. New users receive 100 credits upon registration, so you can start using the API right away.
Credit Types [#credit-types]
| Type | Validity | How to Get |
| ------------------------ | ---------------------------------------------------- | -------------------------------------------------------- |
| **Monthly credits** | Valid within current billing cycle, reset at renewal | Auto-issued with subscription |
| **Permanent credits** | Never expire | Purchase credit packs, referral rewards, sharing rewards |
| **Limited-time credits** | Expire on specified date | Daily check-in, official campaigns |
Deduction order: **limited-time credits → monthly credits → permanent credits**.
Subscription Plans [#subscription-plans]
| Plan | Monthly Credits |
| ----- | -------------------- |
| Basic | 1,300 credits/month |
| Pro | 2,700 credits/month |
| Max | 30,000 credits/month |
In addition to subscriptions, you can [purchase credit packs](https://listenhub.ai/en/pricing/pack?from=pricing) for permanent credits.
Credit Consumption Reference [#credit-consumption-reference]
| Content Type | Approximate Cost |
| ------------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| 5-minute AI podcast | \~24 credits |
| 10-minute text-to-speech | \~40 credits |
| AI video generation | Varies by model, resolution, duration, aspect ratio, and whether a reference video is used. Call `POST /v1/video-generation/estimate-credits` before creating a task. |
| Content extraction | 5 credits minimum; 100 credits per 100,000 characters (max 500 credits) |
> Credit consumption values above are approximate. Actual consumption is
> calculated in real time by the system. Call `GET /v1/user/subscription` to
> check your balance at any time.
Content Extraction Credit Policy [#content-extraction-credit-policy]
Content extraction uses a pre-deduction model:
| Rule | Details |
| ------------------ | -------------------------------------------------------------------------------------------------------------------------- |
| **Pre-deduction** | 5 credits are reserved when a task starts |
| **Actual charge** | 100 credits per 100,000 characters of extracted content; if the actual amount is less than 5, the actual amount is charged |
| **Failure refund** | All pre-deducted credits are fully refunded if extraction fails |
| **Default limit** | 100,000 characters per request (100 credits) |
| **Maximum limit** | 500,000 characters per request (500 credits) |
Credits are calculated based on actual extracted content length. A 3,000-character article costs 3 credits (actual); a 100,000-character article costs 100 credits; a 250,000-character article costs 250 credits.
Rate Limits [#rate-limits]
| Limit | Value | Description |
| ------------------------ | ------- | ---------------------------------------------------------------------------------- |
| Creation request rate | 3 RPM | Up to 3 creation requests per minute |
| AI video generation rate | 5 RPM | Applied per user on `POST /v1/video-generation/generate` and the PixVerse endpoint |
| Exceeded limit error | `29998` | Implement a backoff retry strategy |
**Recommended strategies**:
* Implement a request queue to avoid burst requests
* Use exponential backoff for retries
* Monitor request frequency to prevent hitting limits
Check Credit Balance [#check-credit-balance]
Query your current credit details via the API:
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/user/subscription" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/user/subscription',
{
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
},
},
)
const data = await response.json()
console.log('Available credits:', data.data.totalAvailableCredits)
```
**Python:**
```python
import os
import requests
response = requests.get(
'https://api.marswave.ai/openapi/v1/user/subscription',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
data = response.json()
print('Available credits:', data['data']['totalAvailableCredits'])
```
The response includes monthly, permanent, limited-time, and total available credits. See [Subscription API](/docs/en/openapi/api-reference/subscription) for full details.
Next Steps [#next-steps]
* [Error Handling](/docs/en/openapi/errors) — Handle insufficient credits (26004) and other errors
* [Support](/docs/en/openapi/support) — Enterprise plans and custom requirements
* [Subscription API](/docs/en/openapi/api-reference/subscription) — Full credit query endpoint reference
# Quick Start (/docs/en/openapi/quick-start)
Prerequisites [#prerequisites]
**Get an API key**:
1. Go to [API Key settings](https://listenhub.ai/en/settings/api-keys)
2. Click **Create API Key**
3. Copy and store the API key securely
> The API key is only displayed once at creation. Copy and save it to a secure location immediately.
**Set up environment variable**:
Save your API key as an environment variable. All code examples in this guide reference it:
```bash
# Add to ~/.zshrc or ~/.bashrc to persist across sessions
export LISTENHUB_API_KEY="your_api_key_here"
```
For more setup options, see [Authentication](/docs/en/openapi/authentication#set-up-environment-variable).
Make Your First Call [#make-your-first-call]
Verify API Key [#verify-api-key]
Send a simple request to confirm the API key works:
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/speakers/list?language=en" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/speakers/list?language=en', {
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
},
});
const data = await response.json();
console.log(data);
```
**Python:**
```python
import os
import requests
response = requests.get(
'https://api.marswave.ai/openapi/v1/speakers/list',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
params={'language': 'en'}
)
data = response.json()
print(data)
```
Success response:
```json
{
"code": 0,
"message": "",
"data": {
"items": [
{
"name": "Ethan",
"speakerId": "EN-Man-General-01",
"demoAudioUrl": "https://example.com/demo-ethan.mp3",
"gender": "male",
"language": "en"
},
{
"name": "Sophia",
"speakerId": "EN-Woman-General-01",
"demoAudioUrl": "https://example.com/demo-sophia.mp3",
"gender": "female",
"language": "en"
}
]
}
}
```
Create Your First Podcast [#create-your-first-podcast]
Use `quick` mode to generate a single-speaker episode:
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/podcast/episodes" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"query": "Give a concise introduction to the history of artificial intelligence.",
"speakers": [{"speakerId": "EN-Man-General-01"}],
"language": "en",
"mode": "quick"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/podcast/episodes', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
query: 'Give a concise introduction to the history of artificial intelligence.',
speakers: [{ speakerId: 'EN-Man-General-01' }],
language: 'en',
mode: 'quick',
}),
});
const data = await response.json();
console.log('Episode ID:', data.data.episodeId);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/podcast/episodes',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'query': 'Give a concise introduction to the history of artificial intelligence.',
'speakers': [{'speakerId': 'EN-Man-General-01'}],
'language': 'en',
'mode': 'quick',
}
)
data = response.json()
print('Episode ID:', data['data']['episodeId'])
```
Success response:
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "{episodeId}"
}
}
```
> Podcast generation is asynchronous. The `episodeId` is the identifier you use to track generation progress.
Query Generation Result [#query-generation-result]
Poll the status using the returned `episodeId`:
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/podcast/episodes/{episodeId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/podcast/episodes/{episodeId}',
{
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
}
);
const data = await response.json();
console.log('Status:', data.data.processStatus);
```
**Python:**
```python
import os
import requests
response = requests.get(
'https://api.marswave.ai/openapi/v1/podcast/episodes/{episodeId}',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
data = response.json()
print('Status:', data['data']['processStatus'])
```
Response while processing (`processStatus` is `pending`):
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "{episodeId}",
"createdAt": 1760517419993,
"failCode": 0,
"processStatus": "pending",
"credits": 0,
"sourceProcessResult": {
"content": "Give a concise introduction to the history of artificial intelligence.",
"references": []
},
"title": "",
"outline": "",
"cover": "https://static.listenhub.ai/listenhub_default_cover061802.png",
"audioUrl": "",
"scripts": []
}
}
```
Response after completion (`processStatus` is `success`):
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "{episodeId}",
"createdAt": 1760517752411,
"failCode": 0,
"processStatus": "success",
"credits": 27,
"sourceProcessResult": {
"content": "Give a concise introduction to the history of artificial intelligence.",
"references": []
},
"title": "A Brief History of Artificial Intelligence",
"outline": "...",
"cover": "https://static.listenhub.ai/listenhub_default_cover061804.png",
"audioUrl": "https://assets.listenhub.app/listenhub-public-prod/podcast/{episodeId}.mp3",
"scripts": [
{
"speakerId": "EN-Man-General-01",
"speakerName": "Ethan",
"content": "Artificial intelligence has evolved from symbolic logic to modern large models..."
}
]
}
}
```
When `processStatus` becomes `success`, the `audioUrl` field contains the final MP3 audio URL.
Polling Best Practices [#polling-best-practices]
Podcast generation typically takes 1-4 minutes. Recommended polling strategy: **wait 60 seconds before the first poll, then poll every 10 seconds**.
**JavaScript:**
```javascript
async function pollEpisodeResult(episodeId, apiKey, timeout = 300000) {
const url = `https://api.marswave.ai/openapi/v1/podcast/episodes/${episodeId}`;
const headers = { 'Authorization': `Bearer ${apiKey}` };
const startTime = Date.now();
// Generation takes time, wait 60 seconds first
await new Promise(resolve => setTimeout(resolve, 60000));
while (Date.now() - startTime < timeout) {
const response = await fetch(url, { headers });
const data = await response.json();
if (data.code !== 0) throw new Error(`API error: ${data.message}`);
const status = data.data.processStatus;
if (status === 'success') return data.data;
if (status === 'failed') throw new Error(`Generation failed: ${data.data.message}`);
await new Promise(resolve => setTimeout(resolve, 10000));
}
throw new Error('Episode generation timeout');
}
```
**Python:**
```python
import time
import os
import requests
def poll_episode_result(episode_id, api_key, timeout=300):
"""Poll episode result until completion. Default timeout is 5 minutes."""
url = f"https://api.marswave.ai/openapi/v1/podcast/episodes/{episode_id}"
headers = {"Authorization": f"Bearer {api_key}"}
start_time = time.time()
# Generation takes time, wait 60 seconds first
time.sleep(60)
while time.time() - start_time < timeout:
response = requests.get(url, headers=headers)
data = response.json()
if data["code"] != 0:
raise Exception(f"API error: {data['message']}")
status = data["data"]["processStatus"]
if status == "success":
return data["data"]
if status == "failed":
raise Exception(f"Generation failed: {data['data'].get('message')}")
time.sleep(10)
raise TimeoutError("Episode generation timeout")
```
Next Steps [#next-steps]
* [Core Concepts](/docs/en/openapi/concepts) — Learn about episodes, speakers, and generation modes
* [Podcast Generation API](/docs/en/openapi/api-reference/podcast) — Full request parameters and response fields
* [Text to Speech API](/docs/en/openapi/api-reference/flowspeech) — Convert text to natural-sounding speech
# Support (/docs/en/openapi/support)
Contact [#contact]
**Technical support email**: [support@marswave.ai](mailto:support@marswave.ai)
**Enterprise plans**: For custom integrations and high-volume usage, see [Enterprise Pricing](https://listenhub.ai/en/pricing) or contact the support team directly.
**When reporting an issue, please include**:
* Full API request and response logs
* `episodeId` (when applicable)
* Error code and error message
* Expected behavior versus actual behavior
FAQ [#faq]
**Q: How do I get an API key?**
Go to [API Key settings](https://listenhub.ai/en/settings/api-keys) and click **Create API Key**. See [Authentication](/docs/en/openapi/authentication) for details.
**Q: Why do I get error code 21007?**
The API key is invalid. Check:
* `Authorization` header format is `Bearer $LISTENHUB_API_KEY`
* API key is fully copied
* API key is still active
**Q: What should I do when credits are insufficient?**
* [Purchase credit packs](https://listenhub.ai/en/pricing/pack?from=pricing) for permanent credits
* Upgrade your subscription plan for more monthly credits
* Enterprise users should contact the support team
**Q: How do I know when a task is complete?**
Poll the query endpoint. The task is complete when `processStatus` is `success`, or failed when it is `failed`. See the recommended polling strategy in [Quick Start](/docs/en/openapi/quick-start#polling-best-practices).
**Q: What audio formats are supported?**
* **M3U8** streaming audio (recommended for real-time playback)
* **MP3** full audio (recommended for download)
Glossary [#glossary]
| Term | Description |
| ----------- | ---------------------------------------- |
| **Episode** | Basic content unit in ListenHub |
| **Speaker** | Voice persona, identified by `speakerId` |
| **RPM** | Requests Per Minute |
| **SSE** | Server-Sent Events |
| **M3U8** | HLS streaming format |
# Content Extract (/docs/en/openapi/api-reference/content-extract)
Content Extract [#content-extract]
Extract text content from any URL asynchronously. Submit a URL to create a task, then poll for the result.
Supported Sources [#supported-sources]
- **X / Twitter** -- Profile pages and individual tweets — fetch recent posts from any public account, or extract a single tweet with its full context.
- **YouTube** -- Extract video transcripts and metadata from any public YouTube video URL.
- **WeChat Official Accounts** -- Extract article content from WeChat Official Account posts (mp.weixin.qq.com).
- **Web Articles** -- Any publicly accessible web page — article text, metadata, and reference links.
Use Cases [#use-cases]
* **Podcast source material** -- extract articles, tweets, or WeChat posts as input for podcast generation
* **Content summarization** -- pull long-form content and generate a summary in one call with `summarize`
* **Social media monitoring** -- batch-extract tweets from key accounts
* **Research aggregation** -- collect and structure content from multiple URLs
Create Extraction Task [#create-extraction-task]
`POST /v1/content/extract`
Submitting a task is non-blocking: the endpoint validates the request, reserves credits, kicks off extraction, and returns a `taskId` immediately. Use [Query Task Status](#query-task-status) to retrieve the result.
**Request example**:
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/content/extract" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"source": {
"type": "url",
"uri": "https://example.com/article"
}
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/content/extract', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
source: {
type: 'url',
uri: 'https://example.com/article',
},
}),
});
const data = await response.json();
const taskId = data.data.taskId;
console.log('Task ID:', taskId);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/content/extract',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'source': {
'type': 'url',
'uri': 'https://example.com/article',
}
}
)
data = response.json()
task_id = data['data']['taskId']
print('Task ID:', task_id)
```
**With options (summarize + max length)**:
Set `summarize: true` to have the extracted text condensed into an AI summary, and `maxLength` to cap the number of characters returned.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/content/extract" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"source": {
"type": "url",
"uri": "https://example.com/long-article"
},
"options": {
"summarize": true,
"maxLength": 5000
}
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/content/extract', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
source: {
type: 'url',
uri: 'https://example.com/long-article',
},
options: {
summarize: true,
maxLength: 5000,
},
}),
});
const data = await response.json();
console.log(data);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/content/extract',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'source': {
'type': 'url',
'uri': 'https://example.com/long-article',
},
'options': {
'summarize': True,
'maxLength': 5000,
},
}
)
data = response.json()
print(data)
```
**Twitter/X profile URL with tweet count**:
**cURL:**
```bash
# For Twitter/X profile URLs, use the twitter option to control how many tweets to fetch
curl -X POST "https://api.marswave.ai/openapi/v1/content/extract" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"source": {
"type": "url",
"uri": "https://x.com/elonmusk"
},
"options": {
"twitter": {
"count": 50
}
}
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/content/extract', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
source: {
type: 'url',
uri: 'https://x.com/elonmusk',
},
options: {
twitter: {
count: 50,
},
},
}),
});
const data = await response.json();
console.log(data);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/content/extract',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'source': {
'type': 'url',
'uri': 'https://x.com/elonmusk',
},
'options': {
'twitter': {
'count': 50,
},
},
}
)
data = response.json()
print(data)
```
**WeChat Official Account article**:
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/content/extract" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"source": {
"type": "url",
"uri": "https://mp.weixin.qq.com/s/XXXXXXXXXXXXXXXX"
}
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/content/extract', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
source: {
type: 'url',
uri: 'https://mp.weixin.qq.com/s/XXXXXXXXXXXXXXXX',
},
}),
});
const data = await response.json();
const taskId = data.data.taskId;
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/content/extract',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'source': {
'type': 'url',
'uri': 'https://mp.weixin.qq.com/s/XXXXXXXXXXXXXXXX',
}
}
)
data = response.json()
task_id = data['data']['taskId']
```
**Request body**:
| Field | Type | Required | Description |
| ----------------------- | ------- | -------- | ------------------------------------------------------------------------------ |
| `source` | object | Yes | Source to extract from |
| `source.type` | string | Yes | Must be `"url"` |
| `source.uri` | string | Yes | The URL to extract content from |
| `options` | object | No | Extraction options (defaults to `{}`) |
| `options.summarize` | boolean | No | Generate an AI summary of the extracted text (default `false`) |
| `options.maxLength` | integer | No | Maximum content length in characters (default `100000`, min `1`, max `500000`) |
| `options.twitter` | object | No | Twitter/X specific options |
| `options.twitter.count` | integer | No | Number of tweets to fetch from a profile URL (`1`–`100`, default `20`) |
**Response example**:
```json
{
"code": 0,
"message": "success",
"data": {
"taskId": "67f6a1b2c3d4e5f6a7b8c9d0"
}
}
```
The `taskId` is a 24-character hex string. Pass it to the status endpoint below.
***
Query Task Status [#query-task-status]
`GET /v1/content/extract/{taskId}`
Poll this endpoint until `status` is `completed` or `failed`. While the task is still running, the response carries only the status — the extracted content is withheld until extraction and credit settlement finish.
**Request example**:
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/content/extract/67f6a1b2c3d4e5f6a7b8c9d0" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const result = await fetch(`https://api.marswave.ai/openapi/v1/content/extract/${taskId}`, {
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
},
});
const data = await result.json();
console.log('Status:', data.data.status);
```
**Python:**
```python
import os
import requests
result = requests.get(
f'https://api.marswave.ai/openapi/v1/content/extract/{task_id}',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
data = result.json()
print('Status:', data['data']['status'])
```
**Path parameters**:
| Field | Type | Description |
| -------- | ------ | ------------------------------------------------------- |
| `taskId` | string | 24-character hex string returned by the create endpoint |
**Response while processing** (`status: "processing"`):
```json
{
"code": 0,
"message": "success",
"data": {
"taskId": "67f6a1b2c3d4e5f6a7b8c9d0",
"status": "processing",
"createdAt": 1744200000000
}
}
```
The `data` object (extracted content) is omitted until the task completes.
**Response when complete** (`status: "completed"`):
```json
{
"code": 0,
"message": "success",
"data": {
"taskId": "67f6a1b2c3d4e5f6a7b8c9d0",
"status": "completed",
"createdAt": 1744200000000,
"data": {
"content": "The extracted article text content...",
"metadata": {
"title": "Article Title",
"author": "Author Name"
},
"references": [
"https://example.com/related-article"
]
},
"credits": 100
}
}
```
**Response on failure** (`status: "failed"`):
```json
{
"code": 0,
"message": "success",
"data": {
"taskId": "67f6a1b2c3d4e5f6a7b8c9d0",
"status": "failed",
"createdAt": 1744200000000,
"failCode": 1001,
"message": "Failed to extract content from URL"
}
}
```
**Response fields**:
| Field | Type | Description |
| ----------------- | ------- | ------------------------------------------------------------ |
| `taskId` | string | Task identifier |
| `status` | string | `processing`, `completed`, or `failed` |
| `createdAt` | integer | Creation time as a 13-digit epoch-millisecond timestamp |
| `data` | object | Extracted content. Present only when `status` is `completed` |
| `data.content` | string | Extracted text content (summarized when `summarize: true`) |
| `data.metadata` | object | Page metadata such as title and author |
| `data.references` | array | Referenced URLs found in the content |
| `credits` | integer | Credits consumed (present when `status` is `completed`) |
| `failCode` | integer | Error code (present when `status` is `failed`) |
| `message` | string | Error description (present when `status` is `failed`) |
***
Notes [#notes]
**Twitter/X profile URLs**:
* When the source URL is a Twitter/X profile (e.g. `https://x.com/username`), the API fetches recent tweets.
* Use `options.twitter.count` to control how many tweets to retrieve (`1`–`100`, default `20`).
* This option is ignored for non-Twitter URLs.
**WeChat Official Accounts**:
* Use the full `mp.weixin.qq.com/s/...` article URL.
* Extracted content includes the article body text and metadata.
**Task lifecycle**:
| Status | Description |
| ------------ | --------------------------------------------------- |
| `processing` | Extraction is in progress |
| `completed` | Content extracted successfully |
| `failed` | Extraction failed -- check `failCode` and `message` |
**Polling recommendations**:
* Initial wait: 5 seconds after task creation
* Poll interval: 5 seconds
* Typical completion time: 10-30 seconds depending on URL complexity
**Credits**:
Content extraction reserves credits when the task starts and settles to the actual amount once the content length is known. The `credits` field in the completed response reflects the final charge.
| Rule | Details |
| -------------- | --------------------------------------------------------------------------------- |
| Pre-deduction | A small hold is reserved when the task starts |
| Actual charge | Based on the number of characters in the extracted content, capped by `maxLength` |
| Failure refund | All reserved credits are refunded if extraction fails |
Content extraction itself has no estimate endpoint — the final `credits` value is known only after the content length settles. Check your live balance with [`GET /v1/user/subscription`](/docs/en/openapi/api-reference/subscription), and see [Pricing](/docs/en/openapi/pricing) for the credit-to-feature mapping.
***
# Explainer Video (/docs/en/openapi/api-reference/explainer-video)
Explainer Video lets you create narrated visual content from text or URLs. Two modes are available:
| | `info` (default) | `story` |
| ---------------- | ------------------------------------------------ | --------------------------- |
| **Purpose** | Knowledge explainers, product intros | Story sharing, case studies |
| **Visual style** | Infographics, illustrations, data visualizations | Story scene illustrations |
| **Page 1** | Magazine-style cover | Story cover |
> The `mode` parameter is optional and defaults to `info`.
***
Create Episode [#create-episode]
`POST /v1/storybook/episodes`
Create an explainer video episode with AI-generated visuals and narration.
> `sources` accepts at most 1 item. `speakers` accepts at most 1 item.
**Info mode** (default):
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/storybook/episodes" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"sources": [
{"type": "url", "uri": "https://example.com/article", "content": "https://example.com/article"}
],
"speakers": [
{"speakerId": ""}
],
"language": "en",
"mode": "info"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/storybook/episodes', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
sources: [{ type: 'url', uri: 'https://example.com/article', content: 'https://example.com/article' }],
speakers: [{ speakerId: '' }],
language: 'en',
mode: 'info',
}),
});
const data = await response.json();
console.log(data);
```
**Python:**
```python
import os, requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/storybook/episodes',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'sources': [{'type': 'url', 'uri': 'https://example.com/article', 'content': 'https://example.com/article'}],
'speakers': [{'speakerId': ''}],
'language': 'en',
'mode': 'info',
}
)
print(response.json())
```
**Story mode**:
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/storybook/episodes" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"sources": [
{"type": "text", "content": "The founding story of a small startup that grew into a global platform..."}
],
"speakers": [
{"speakerId": ""}
],
"language": "en",
"mode": "story"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/storybook/episodes', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
sources: [{ type: 'text', content: 'The founding story of a small startup that grew into a global platform...' }],
speakers: [{ speakerId: '' }],
language: 'en',
mode: 'story',
}),
});
const data = await response.json();
console.log(data);
```
**Python:**
```python
import os, requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/storybook/episodes',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'sources': [{'type': 'text', 'content': 'The founding story of a small startup that grew into a global platform...'}],
'speakers': [{'speakerId': ''}],
'language': 'en',
'mode': 'story',
}
)
print(response.json())
```
**Response**:
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "{episodeId}"
}
}
```
Request Parameters [#request-parameters]
| Parameter | Type | Required | Description |
| --------------------- | -------- | --------------------------- | ------------------------------------------------------------ |
| sources | array(1) | Yes | Content source. Max 1 item. |
| sources\[].type | string | Yes | `"text"` or `"url"` |
| sources\[].content | string | Yes | Text content or URL |
| sources\[].uri | string | Required when type is `url` | Source URI |
| sources\[].metadata | object | No | Source metadata |
| speakers | array(1) | Yes | Voice config. Max 1 item. |
| speakers\[].speakerId | string | Yes | Speaker ID (see [Speakers](/openapi/api-reference/speakers)) |
| language | string | No | Language code (e.g. `"en"`, `"zh"`) |
| mode | string | No | `"info"` (default) or `"story"` |
| style | string | No | Visual style ID |
***
Query Episode Status [#query-episode-status]
`GET /v1/storybook/episodes/{episodeId}`
Poll with the returned `episodeId` until `processStatus` is `success`.
**cURL:**
```bash
curl "https://api.marswave.ai/openapi/v1/storybook/episodes/{episodeId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
`https://api.marswave.ai/openapi/v1/storybook/episodes/${episodeId}`,
{ headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` } }
);
const data = await response.json();
console.log('Status:', data.data.processStatus);
```
**Python:**
```python
import os, requests
response = requests.get(
f'https://api.marswave.ai/openapi/v1/storybook/episodes/{episode_id}',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
data = response.json()
print('Status:', data['data']['processStatus'])
```
**Response** (when `processStatus` is `success`):
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "{episodeId}",
"createdAt": 1700000000,
"mode": "info",
"processStatus": "success",
"credits": 30,
"title": "How AI Is Changing the World",
"cover": "https://assets.listenhub.app/covers/{episodeId}.png",
"audioUrl": "https://assets.listenhub.app/storybook/{episodeId}.mp3",
"audioDuration": 180,
"videoUrl": "",
"videoStatus": "not_generated",
"pages": [
{
"text": "Artificial intelligence has transformed industries worldwide...",
"pageNumber": 1,
"imageUrl": "https://assets.listenhub.app/pages/{episodeId}-1.png",
"audioTimestamp": 0
},
{
"text": "From healthcare to finance, AI applications continue to expand...",
"pageNumber": 2,
"imageUrl": "https://assets.listenhub.app/pages/{episodeId}-2.png",
"audioTimestamp": 25.3
}
]
}
}
```
> **Raw materials**: Each item in `pages[]` contains an `imageUrl` (AI-generated visual) and `text` (voiceover script). You can download these independently for your own content.
processStatus [#processstatus]
| Value | Meaning |
| --------- | ------------------------- |
| `pending` | Processing |
| `success` | Complete |
| `fail` | Failed (check `failCode`) |
videoStatus [#videostatus]
| Value | Meaning |
| --------------- | ---------------------------------- |
| `not_generated` | Video not yet triggered |
| `pending` | Video generating |
| `success` | Video ready (`videoUrl` available) |
| `fail` | Video generation failed |
> Generation typically takes 2–5 minutes. Recommended polling: wait 60 seconds, then poll every 10 seconds.
***
Generate Video [#generate-video]
`POST /v1/storybook/episodes/{episodeId}/video`
Trigger video generation for a completed episode. `processStatus` must be `success`.
> Wait until `processStatus` is `success` before calling this endpoint.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/storybook/episodes/{episodeId}/video" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
`https://api.marswave.ai/openapi/v1/storybook/episodes/${episodeId}/video`,
{
method: 'POST',
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
}
);
console.log(await response.json());
```
**Python:**
```python
import os, requests
response = requests.post(
f'https://api.marswave.ai/openapi/v1/storybook/episodes/{episode_id}/video',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
print(response.json())
```
**Response**:
```json
{
"code": 0,
"message": "",
"data": {
"success": true
}
}
```
After triggering, poll `GET /v1/storybook/episodes/{episodeId}` until `videoStatus` is `success`.
***
Complete Workflow [#complete-workflow]
1. Create Episode [#create-episode-1]
Call `POST /v1/storybook/episodes` with your source, speaker, and mode (`info` or `story`). Save the returned `episodeId`.
2. Poll for Completion [#poll-for-completion]
Poll `GET /v1/storybook/episodes/{episodeId}` every 10 seconds (after an initial 60-second wait) until `processStatus` is `success`.
3. Use Raw Materials (Optional) [#use-raw-materials-optional]
The `pages[]` array contains AI-generated images (`imageUrl`) and narration scripts (`text`) for each page. Use these directly without generating a video.
4. Generate Video [#generate-video-1]
Call `POST /v1/storybook/episodes/{episodeId}/video` to combine pages into a narrated video.
5. Poll Video Status [#poll-video-status]
Poll until `videoStatus` is `success`. The `videoUrl` field contains the download link.
# Text to Speech (/docs/en/openapi/api-reference/flowspeech)
ListenHub exposes several text-to-speech endpoints, each tuned for a different shape of work. They share the same base URL, authentication, and speaker IDs, but differ in latency, response type, and how many voices they support.
All requests go to `https://api.marswave.ai/openapi/v1` and authenticate with an API key:
```
Authorization: Bearer $LISTENHUB_API_KEY
```
Create keys at [listenhub.ai/settings/api-keys](https://listenhub.ai/settings/api-keys). Every JSON response is wrapped as `{ "code": 0, "message": "", "data": { ... } }`; a non-zero `code` signals an error. The streaming endpoints (`/v1/tts`, `/v1/audio/speech`) return raw binary audio instead of this envelope.
Choosing an endpoint [#choosing-an-endpoint]
| Endpoint | Voices | Sync / Async | Response | Best for |
| ------------------------------------------------------------------ | -------- | ------------ | -------------------- | -------------------------------------------------- |
| [`POST /v1/tts`](#streaming-tts) | Single | Sync | Binary audio stream | Real-time playback, in-app voice, low latency |
| [`POST /v1/audio/speech`](#openai-compatible-tts) | Single | Sync | Binary audio stream | Drop-in replacement for the OpenAI TTS endpoint |
| [`POST /v1/speech`](#multi-speaker-script-to-audio) | Multiple | Sync | JSON with `audioUrl` | Dialogue, audiobooks, prepared multi-voice scripts |
| [`POST /v1/flow-speech/episodes`](#long-form-text-to-speech) | Single | Async | Poll by `episodeId` | Article and newsletter narration, URL-to-audio |
| [`POST /v1/flow-speech/episodes/tts`](#multi-speaker-direct-async) | Multiple | Async | Poll by `episodeId` | Long multi-voice scripts converted verbatim |
Rule of thumb: reach for `/v1/tts` when you need audio bytes back immediately for one voice, `/v1/speech` when you have a short multi-voice script and want a hosted URL in one call, and the `/v1/flow-speech/episodes` endpoints when the job is long enough to run in the background.
> Credit cost scales with audio length and is returned on the relevant responses (`credits`) once a job completes. To estimate cost before generating, see the credits estimation endpoints in the API reference.
***
Streaming TTS [#streaming-tts]
`POST /v1/tts`
Low-latency single-voice synthesis. The response body is raw binary audio streamed as it is generated, so the first bytes arrive before the full clip is ready. Use this for real-time playback and interactive voice features.
This endpoint accepts the OpenAI text-to-speech request shape (`input` / `voice` / `response_format`), which makes it easy to migrate existing clients.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/tts" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"input": "Hello, welcome to ListenHub text-to-speech.",
"voice": "EN-Man-General-01",
"response_format": "mp3",
"speed": 1.25
}' \
--output output.mp3
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/tts', {
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
input: 'Hello, welcome to ListenHub text-to-speech.',
voice: 'EN-Man-General-01',
response_format: 'mp3',
speed: 1.25,
}),
});
const buffer = Buffer.from(await response.arrayBuffer());
// Write `buffer` to a file, or pipe `response.body` to a player
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/tts',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'input': 'Hello, welcome to ListenHub text-to-speech.',
'voice': 'EN-Man-General-01',
'response_format': 'mp3',
'speed': 1.25,
},
stream=True,
)
with open('output.mp3', 'wb') as f:
for chunk in response.iter_content(chunk_size=8192):
f.write(chunk)
```
Request parameters [#request-parameters]
| Field | Type | Required | Description |
| ----------------- | ------ | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `input` | string | Yes | Text to synthesize. Max 20,000 characters. |
| `voice` | string | Yes | Speaker ID (the `speakerId` value from [Speakers](/docs/en/openapi/api-reference/speakers)). |
| `response_format` | string | No | Requested audio format. One of `mp3`, `opus`, `aac`, `flac`, `wav`, `pcm`. Defaults to `mp3`. |
| `speed` | number | No | Generation speed multiplier — the speaking rate of the generated audio, not a player playback rate. Range `0.5`–`2.0`, at most two decimals. Defaults to `1` (original speed). |
> The response body is binary audio, not the JSON envelope — read it as a stream or blob. The delivered container is MP3 (`Content-Type: audio/mpeg`) for every format except `opus`, which is delivered as OGG/Opus (`Content-Type: audio/ogg`). If the request fails before audio starts, the response falls back to a JSON error object, so check the `Content-Type` before treating the body as audio.
***
OpenAI-compatible TTS [#openai-compatible-tts]
`POST /v1/audio/speech`
An exact alias of [`/v1/tts`](#streaming-tts) at the path the OpenAI SDK and OpenAI-compatible integrations call by default. The request body, `response_format` options, and streaming binary response are identical. Point an existing OpenAI TTS client at this URL with your ListenHub API key and a ListenHub `voice` ID to switch over without code changes.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/audio/speech" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"input": "This endpoint mirrors the OpenAI speech API.",
"voice": "EN-Woman-General-01",
"response_format": "mp3"
}' \
--output output.mp3
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/audio/speech', {
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
input: 'This endpoint mirrors the OpenAI speech API.',
voice: 'EN-Woman-General-01',
response_format: 'mp3',
}),
});
const buffer = Buffer.from(await response.arrayBuffer());
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/audio/speech',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'input': 'This endpoint mirrors the OpenAI speech API.',
'voice': 'EN-Woman-General-01',
'response_format': 'mp3',
},
stream=True,
)
with open('output.mp3', 'wb') as f:
for chunk in response.iter_content(chunk_size=8192):
f.write(chunk)
```
The request parameters and response behavior are the same as [Streaming TTS](#streaming-tts).
***
Multi-Speaker Script to Audio [#multi-speaker-script-to-audio]
`POST /v1/speech`
Generate one audio file from a prepared multi-voice script. Each line carries its own `speakerId`, so you can alternate voices for dialogue. The call is synchronous and returns a hosted audio URL plus subtitles in the response — no polling.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/speech" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"scripts": [
{ "content": "Welcome everyone to this episode.", "speakerId": "EN-Man-General-01" },
{ "content": "Today we are discussing an interesting topic.", "speakerId": "EN-Woman-General-01" },
{ "content": "Great, let us begin.", "speakerId": "EN-Man-General-01" }
]
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/speech', {
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
scripts: [
{ content: 'Welcome everyone to this episode.', speakerId: 'EN-Man-General-01' },
{ content: 'Today we are discussing an interesting topic.', speakerId: 'EN-Woman-General-01' },
{ content: 'Great, let us begin.', speakerId: 'EN-Man-General-01' },
],
}),
});
const { data } = await response.json();
console.log(data.audioUrl);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/speech',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'scripts': [
{'content': 'Welcome everyone to this episode.', 'speakerId': 'EN-Man-General-01'},
{'content': 'Today we are discussing an interesting topic.', 'speakerId': 'EN-Woman-General-01'},
{'content': 'Great, let us begin.', 'speakerId': 'EN-Man-General-01'},
]
},
)
data = response.json()['data']
print(data['audioUrl'])
```
Request parameters [#request-parameters-1]
| Field | Type | Required | Description |
| --------------------- | ------ | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `scripts` | array | Yes | One or more script lines, synthesized in order. |
| `scripts[].content` | string | Yes | Line text. Must be non-empty; combined length across all lines is capped at 20,000 characters. |
| `scripts[].speakerId` | string | Yes | Speaker ID for this line. Different lines may use different speakers. |
| `speed` | number | No | Generation speed multiplier — the speaking rate of the generated audio, not a player playback rate. Range `0.5`–`2.0`, at most two decimals. Defaults to `1` (original speed). |
Response [#response]
```json
{
"code": 0,
"message": "",
"data": {
"audioUrl": "https://assets.listenhub.app/listenhub-public-prod/podcast/example.mp3",
"audioDuration": 12500,
"subtitlesUrl": "https://assets.listenhub.app/listenhub-public-prod/podcast/example.srt",
"taskId": "1eed39d387a046c0a1213e6b8f139d77",
"credits": 12
}
}
```
| Field | Type | Description |
| --------------- | ------- | ---------------------------------------------------------------------------- |
| `audioUrl` | string | URL of the generated MP3 file. |
| `audioDuration` | integer | Audio duration in milliseconds. |
| `subtitlesUrl` | string | SRT subtitle file URL. Valid for 24 hours. |
| `taskId` | string | Task ID. Quote it when reporting an issue so support can locate the request. |
| `credits` | integer | Credits consumed by this request. |
***
Long-Form Text to Speech [#long-form-text-to-speech]
`POST /v1/flow-speech/episodes`
Convert a block of text or the contents of a URL into a single-voice narration. This endpoint runs asynchronously: the request returns an `episodeId` right away, and you poll for the audio once it finishes. It is built for longer inputs where waiting on a synchronous call would be impractical.
Two modes control how the source text is handled:
* **`smart`** (default) — cleans up the text first: fixes punctuation, grammar, and formatting so rough or pasted input still reads naturally.
* **`direct`** — synthesizes the text verbatim, with no rewriting. Use this when the script is already final.
Constraints: exactly one `sources` item, exactly one speaker, and a text source of at least 10 characters (up to 20,000).
Smart mode (AI polish) [#smart-mode-ai-polish]
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/flow-speech/episodes" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"sources": [
{
"type": "text",
"content": "welcome to listenhub this text is intentionally rough and punctuation will be improved automatically"
}
],
"speakers": [
{ "speakerId": "EN-Woman-General-01" }
],
"language": "en",
"mode": "smart"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/flow-speech/episodes', {
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
sources: [
{
type: 'text',
content: 'welcome to listenhub this text is intentionally rough and punctuation will be improved automatically',
},
],
speakers: [{ speakerId: 'EN-Woman-General-01' }],
language: 'en',
mode: 'smart',
}),
});
const { data } = await response.json();
console.log('Episode ID:', data.episodeId);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/flow-speech/episodes',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'sources': [
{
'type': 'text',
'content': 'welcome to listenhub this text is intentionally rough and punctuation will be improved automatically',
}
],
'speakers': [{'speakerId': 'EN-Woman-General-01'}],
'language': 'en',
'mode': 'smart',
},
)
print('Episode ID:', response.json()['data']['episodeId'])
```
Direct mode [#direct-mode]
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/flow-speech/episodes" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"sources": [
{
"type": "text",
"content": "Welcome to ListenHub. This script is already finalized and should be converted as-is."
}
],
"speakers": [
{ "speakerId": "EN-Man-General-01" }
],
"language": "en",
"mode": "direct"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/flow-speech/episodes', {
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
sources: [
{
type: 'text',
content: 'Welcome to ListenHub. This script is already finalized and should be converted as-is.',
},
],
speakers: [{ speakerId: 'EN-Man-General-01' }],
language: 'en',
mode: 'direct',
}),
});
const { data } = await response.json();
console.log('Episode ID:', data.episodeId);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/flow-speech/episodes',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'sources': [
{
'type': 'text',
'content': 'Welcome to ListenHub. This script is already finalized and should be converted as-is.',
}
],
'speakers': [{'speakerId': 'EN-Man-General-01'}],
'language': 'en',
'mode': 'direct',
},
)
print('Episode ID:', response.json()['data']['episodeId'])
```
Read content from a URL [#read-content-from-a-url]
Set `type` to `url` and pass the page address in `uri`. ListenHub fetches and extracts the readable content before synthesis. (`content` is still accepted in place of `uri` for backward compatibility.)
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/flow-speech/episodes" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"sources": [
{
"type": "url",
"uri": "https://example.com/article.html"
}
],
"speakers": [
{ "speakerId": "EN-Woman-General-01" }
],
"language": "en",
"mode": "smart"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/flow-speech/episodes', {
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
sources: [{ type: 'url', uri: 'https://example.com/article.html' }],
speakers: [{ speakerId: 'EN-Woman-General-01' }],
language: 'en',
mode: 'smart',
}),
});
const { data } = await response.json();
console.log('Episode ID:', data.episodeId);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/flow-speech/episodes',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'sources': [{'type': 'url', 'uri': 'https://example.com/article.html'}],
'speakers': [{'speakerId': 'EN-Woman-General-01'}],
'language': 'en',
'mode': 'smart',
},
)
print('Episode ID:', response.json()['data']['episodeId'])
```
Request parameters [#request-parameters-2]
| Field | Type | Required | Description |
| ---------------------- | ------ | ----------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `sources` | array | Yes | Content source. Exactly one item. |
| `sources[].type` | string | Yes | `text` or `url`. |
| `sources[].content` | string | For `text` | Text to narrate. Minimum 10 characters, maximum 20,000. For very short clips, use [`/v1/speech`](#multi-speaker-script-to-audio) instead. |
| `sources[].uri` | string | For `url` (recommended) | Page URL to read from. Either `uri` or `content` must be present for a `url` source. |
| `speakers` | array | Yes | Speaker list. Exactly one item. |
| `speakers[].speakerId` | string | Yes | Speaker ID. |
| `language` | string | No | Source language: `en`, `zh`, or `ja`. Inferred from the content when omitted. |
| `mode` | string | No | `smart` (AI polish) or `direct` (verbatim). Defaults to `smart`. |
| `speed` | number | No | Generation speed multiplier — the speaking rate of the generated audio, not a player playback rate. Range `0.5`–`2.0`, at most two decimals. Defaults to `1` (original speed). |
The response contains only the task ID:
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "665f1c2a9b3e4d0012a4c8e1"
}
}
```
Poll for results [#poll-for-results]
`GET /v1/flow-speech/episodes/{episodeId}`
Poll with the returned `episodeId` until `processStatus` is `success`.
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/flow-speech/episodes/{episodeId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
`https://api.marswave.ai/openapi/v1/flow-speech/episodes/${episodeId}`,
{ headers: { Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}` } },
);
const { data } = await response.json();
console.log('Status:', data.processStatus);
console.log('Audio URL:', data.audioUrl);
```
**Python:**
```python
import os
import requests
response = requests.get(
f'https://api.marswave.ai/openapi/v1/flow-speech/episodes/{episode_id}',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
)
data = response.json()['data']
print('Status:', data['processStatus'])
print('Audio URL:', data.get('audioUrl'))
```
When the job finishes (`processStatus` is `success`):
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "665f1c2a9b3e4d0012a4c8e1",
"createdAt": 1717430000000,
"processStatus": "success",
"completedTime": 1717430090000,
"title": "Article Title",
"outline": "...",
"cover": "https://assets.listenhub.app/.../cover.png",
"audioUrl": "https://assets.listenhub.app/listenhub-public-prod/podcast/665f1c2a9b3e4d0012a4c8e1.mp3",
"audioStreamUrl": "https://assets.listenhub.app/listenhub-public-prod/podcast/665f1c2a9b3e4d0012a4c8e1.m3u8",
"subtitlesUrl": "https://assets.listenhub.app/.../665f1c2a9b3e4d0012a4c8e1.srt",
"scripts": "Full narration script text..."
}
}
```
| Field | Type | Description |
| ---------------- | ------- | ---------------------------------------------------------------------------------------------------------------- |
| `episodeId` | string | The episode identifier. |
| `createdAt` | integer | Creation timestamp in milliseconds. |
| `processStatus` | string | Current state: `pending`, `success`, or `fail`. Poll until `success`; `fail` indicates the job did not complete. |
| `failCode` | integer | Present on failure; identifies the reason. |
| `completedTime` | integer | Completion timestamp in milliseconds. |
| `title` | string | Generated episode title. |
| `outline` | string | Generated outline of the narration. |
| `cover` | string | Cover image URL. |
| `audioUrl` | string | MP3 audio file URL. |
| `audioStreamUrl` | string | HLS streaming URL (`.m3u8`). |
| `subtitlesUrl` | string | SRT subtitle file URL. |
| `scripts` | string | Full narration script text. |
> Long-form jobs typically finish in one to two minutes. A practical polling strategy: wait 30 seconds after creation, then poll every 10 seconds. On failure, `processStatus` is `fail` and `failCode` carries the reason.
***
Multi-Speaker Direct (async) [#multi-speaker-direct-async]
`POST /v1/flow-speech/episodes/tts`
Convert a long, prepared multi-voice script into an episode. This is the asynchronous, multi-speaker counterpart to [`/v1/speech`](#multi-speaker-script-to-audio): every line keeps its own `speakerId`, the text is synthesized verbatim (direct mode), and the call returns an `episodeId` to poll. Reach for it when a multi-voice script is too long to handle in a single synchronous `/v1/speech` request.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/flow-speech/episodes/tts" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"title": "Roundtable Discussion",
"scripts": [
{ "content": "Thanks for joining the roundtable today.", "speakerId": "EN-Man-General-01" },
{ "content": "Happy to be here. Let us dig into the agenda.", "speakerId": "EN-Woman-General-01" }
]
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/flow-speech/episodes/tts', {
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
title: 'Roundtable Discussion',
scripts: [
{ content: 'Thanks for joining the roundtable today.', speakerId: 'EN-Man-General-01' },
{ content: 'Happy to be here. Let us dig into the agenda.', speakerId: 'EN-Woman-General-01' },
],
}),
});
const { data } = await response.json();
console.log('Episode ID:', data.episodeId);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/flow-speech/episodes/tts',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'title': 'Roundtable Discussion',
'scripts': [
{'content': 'Thanks for joining the roundtable today.', 'speakerId': 'EN-Man-General-01'},
{'content': 'Happy to be here. Let us dig into the agenda.', 'speakerId': 'EN-Woman-General-01'},
],
},
)
print('Episode ID:', response.json()['data']['episodeId'])
```
Request parameters [#request-parameters-3]
| Field | Type | Required | Description |
| --------------------- | ------ | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `scripts` | array | Yes | One or more script lines, synthesized in order. |
| `scripts[].content` | string | Yes | Line text. Must be non-empty; combined length across all lines is capped at 20,000 characters. |
| `scripts[].speakerId` | string | Yes | Speaker ID for this line. Different lines may use different speakers. |
| `title` | string | No | Custom episode title. Auto-generated when omitted. |
| `speed` | number | No | Generation speed multiplier — the speaking rate of the generated audio, not a player playback rate. Range `0.5`–`2.0`, at most two decimals. Defaults to `1` (original speed). |
The response returns an `episodeId`. Poll for results with the same status endpoint as long-form jobs, [`GET /v1/flow-speech/episodes/{episodeId}`](#poll-for-results).
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "665f1c2a9b3e4d0012a4c8e1"
}
}
```
***
Related [#related]
- **Speakers** -- List available voices and their speaker IDs. [/docs/en/openapi/api-reference/speakers](/docs/en/openapi/api-reference/speakers)
- **Authentication** -- Create and use API keys. [/docs/en/openapi/authentication](/docs/en/openapi/authentication)
# Image Generation (/docs/en/openapi/api-reference/image-generation)
The Image Generation API turns a text prompt (optionally guided by reference images) into one or
more images. You can call it three ways:
* **Synchronous** — `POST /v1/images/generation` blocks until the image is ready and returns the
raw model output (base64 image data) in the response body.
* **Asynchronous** — `POST /v1/images/generation/async` returns a `taskId` immediately; poll
`GET /v1/images/generation/tasks/{taskId}` for the result (hosted image URLs).
* **Estimate first** — `POST /v1/images/generation/estimate-credits` returns the credit cost and
whether your account can generate, without spending anything.
All endpoints require an API key (`Authorization: Bearer $LISTENHUB_API_KEY`). Create keys at
[listenhub.ai/settings/api-keys](https://listenhub.ai/settings/api-keys).
> The two generation endpoints return data differently. The **synchronous** endpoint returns the
> raw model JSON directly in the body (not wrapped in the standard `{ code, message, data }`
> envelope). The **async** and **estimate** endpoints use the standard wrapped envelope. See
> [Response Formats](#response-formats).
Generate Image (synchronous) [#generate-image-synchronous]
`POST /v1/images/generation`
Generate an image from a text prompt and block until it is ready. Optionally supply reference
images to guide the style or content. The response body is the raw model output — JSON containing
base64 image data.
Basic generation [#basic-generation]
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/images/generation" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"provider": "google",
"model": "gemini-3-pro-image",
"prompt": "A serene mountain landscape at sunset with a reflective lake",
"imageConfig": {
"aspectRatio": "16:9",
"imageSize": "2K"
}
}'
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/images/generation',
{
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
provider: 'google',
model: 'gemini-3-pro-image',
prompt: 'A serene mountain landscape at sunset with a reflective lake',
imageConfig: {
aspectRatio: '16:9',
imageSize: '2K',
},
}),
},
)
const data = await response.json()
// data.candidates[0].content.parts[0].inlineData holds the generated image
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/images/generation',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'provider': 'google',
'model': 'gemini-3-pro-image',
'prompt': 'A serene mountain landscape at sunset with a reflective lake',
'imageConfig': {
'aspectRatio': '16:9',
'imageSize': '2K',
},
},
)
data = response.json()
# data['candidates'][0]['content']['parts'][0]['inlineData'] holds the generated image
```
> To use GPT-Image-2, set `provider` to `"openai"` and `model` to `"gpt-image-2"`. The request and
> response format is the same — only `provider`, `model`, and the `imageConfig` differ. See the
> [Provider and Model Matrix](#provider-and-model-matrix).
Generation with reference images [#generation-with-reference-images]
Supply reference images to guide the output. Each reference image is either a URL (`fileData`) or
base64-encoded inline data (`inlineData`). You can mix both formats in one request.
Using image URLs [#using-image-urls]
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/images/generation" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"provider": "google",
"model": "gemini-3-pro-image",
"prompt": "Transform this scene into a watercolor painting style",
"referenceImages": [
{
"fileData": {
"fileUri": "https://example.com/my-photo.jpg",
"mimeType": "image/jpeg"
}
}
],
"imageConfig": {
"aspectRatio": "1:1",
"imageSize": "2K"
}
}'
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/images/generation',
{
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
provider: 'google',
model: 'gemini-3-pro-image',
prompt: 'Transform this scene into a watercolor painting style',
referenceImages: [
{
fileData: {
fileUri: 'https://example.com/my-photo.jpg',
mimeType: 'image/jpeg',
},
},
],
imageConfig: {
aspectRatio: '1:1',
imageSize: '2K',
},
}),
},
)
const data = await response.json()
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/images/generation',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'provider': 'google',
'model': 'gemini-3-pro-image',
'prompt': 'Transform this scene into a watercolor painting style',
'referenceImages': [
{
'fileData': {
'fileUri': 'https://example.com/my-photo.jpg',
'mimeType': 'image/jpeg',
}
}
],
'imageConfig': {
'aspectRatio': '1:1',
'imageSize': '2K',
},
},
)
data = response.json()
```
Using base64 inline data [#using-base64-inline-data]
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/images/generation" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"provider": "google",
"model": "gemini-3-pro-image",
"prompt": "Create a cartoon version of this portrait",
"referenceImages": [
{
"inlineData": {
"data": "",
"mimeType": "image/png"
}
}
]
}'
```
**JavaScript:**
```javascript
import { readFileSync } from 'fs'
const imageBase64 = readFileSync('reference.png').toString('base64')
const response = await fetch(
'https://api.marswave.ai/openapi/v1/images/generation',
{
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
provider: 'google',
model: 'gemini-3-pro-image',
prompt: 'Create a cartoon version of this portrait',
referenceImages: [
{
inlineData: {
data: imageBase64,
mimeType: 'image/png',
},
},
],
}),
},
)
const data = await response.json()
```
**Python:**
```python
import os
import base64
import requests
with open('reference.png', 'rb') as f:
image_base64 = base64.b64encode(f.read()).decode('utf-8')
response = requests.post(
'https://api.marswave.ai/openapi/v1/images/generation',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'provider': 'google',
'model': 'gemini-3-pro-image',
'prompt': 'Create a cartoon version of this portrait',
'referenceImages': [
{
'inlineData': {
'data': image_base64,
'mimeType': 'image/png',
}
}
],
},
)
data = response.json()
```
Request parameters [#request-parameters]
These parameters apply to `POST /v1/images/generation`, `POST /v1/images/generation/async`, and
`POST /v1/images/generation/estimate-credits` — the three endpoints share one request schema.
| Field | Type | Required | Description |
| --------------------------------------- | ------ | -------- | -------------------------------------------------------------------------------------------------- |
| `provider` | string | Yes¹ | Model provider: `google`, `openai`, or `bytedance` |
| `model` | string | No | Model name. Defaults to `gpt-image-2`. See [Provider and Model Matrix](#provider-and-model-matrix) |
| `prompt` | string | Yes² | Text description of the image to generate |
| `referenceImages` | array | No | Reference images to guide generation. See [Reference image limits](#reference-image-limits) |
| `referenceImages[].fileData` | object | No | Reference image supplied as a URL |
| `referenceImages[].fileData.fileUri` | string | Yes | Image URL — scheme must be `http`, `https`, or `gs` |
| `referenceImages[].fileData.mimeType` | string | Yes | MIME type: `image/png`, `image/jpeg`, `image/webp`, `image/heic`, or `image/heif` |
| `referenceImages[].inlineData` | object | No | Reference image supplied as base64-encoded data |
| `referenceImages[].inlineData.data` | string | Yes | Base64-encoded image data |
| `referenceImages[].inlineData.mimeType` | string | Yes | MIME type: `image/png`, `image/jpeg`, `image/webp`, `image/heic`, or `image/heif` |
| `imageConfig` | object | No | Image output configuration. Defaults to `{ "imageSize": "2K" }` |
| `imageConfig.imageSize` | string | No | Output resolution: `1K`, `2K` (default), or `4K` |
| `imageConfig.aspectRatio` | string | No | Aspect ratio. Defaults to `1:1`. See [Aspect ratios](#aspect-ratios) |
| `imageConfig.quality` | string | No | Render quality: `low`, `medium`, or `high`. Applies to GPT-Image-2; omit to let the model decide |
¹ `provider` is required on the two generation endpoints and optional on `estimate-credits`.
² `prompt` is required on the two generation endpoints; on `estimate-credits` it may be empty or
omitted (it only affects the input-token estimate).
> Each item in `referenceImages` must contain exactly one of `fileData` or `inlineData`, not both.
Provider and Model Matrix [#provider-and-model-matrix]
`provider` selects the vendor; `model` selects the specific model. The default model is
`gpt-image-2`.
| `provider` | `model` | Notes |
| ----------- | ------------------------ | ------------------------------------------------------------------------------------------------------- |
| `google` | `gemini-3-pro-image` | Higher quality, more detailed output. NanoBanana Pro |
| `google` | `gemini-3.1-flash-image` | Faster generation. Supports the extra `1:4` / `4:1` / `1:8` / `8:1` ratios |
| `openai` | `gpt-image-2` | Strong prompt following. At most 4 reference images. `aspectRatio` optional |
| `bytedance` | `seedream-5-0-pro` | Precise editing (coordinates / color codes go in `prompt`). Up to 10 reference images. `1K` / `2K` only |
> Legacy preview model IDs `gemini-3-pro-image-preview` and `gemini-3.1-flash-image-preview` are
> still accepted as input and normalized to their GA IDs above. Send the GA IDs for new
> integrations.
Aspect ratios [#aspect-ratios]
`imageConfig.aspectRatio` defaults to `1:1`. The following ratios are accepted by the schema:
| Ratio | Description |
| ------ | ----------------- |
| `1:1` | Square |
| `2:3` | Portrait |
| `3:2` | Landscape |
| `3:4` | Portrait |
| `4:3` | Landscape |
| `9:16` | Vertical / mobile |
| `16:9` | Widescreen |
| `21:9` | Ultra-wide |
| `1:4` | Flash only |
| `4:1` | Flash only |
| `1:8` | Flash only |
| `8:1` | Flash only |
> `1:4`, `4:1`, `1:8`, and `8:1` are accepted only by `gemini-3.1-flash-image` and `seedream-5-0-pro`. GPT-Image-2 supports
> the eight standard ratios (`1:1`, `2:3`, `3:2`, `3:4`, `4:3`, `9:16`, `16:9`, `21:9`) and lets you
> omit `aspectRatio` to choose automatically. A ratio unsupported by the selected model returns
> `400`.
Image sizes [#image-sizes]
`imageConfig.imageSize` accepts `1K`, `2K` (default), and `4K`. Larger sizes cost more credits and,
for GPT-Image-2, `4K` (and `high` quality) requires an active paid subscription. **Seedream 5.0 Pro
supports `1K` and `2K` only; `4K` returns `400`.** Do not hardcode
credit costs — call [estimate-credits](#estimate-credits) for the exact figure.
Reference image limits [#reference-image-limits]
| Model | Max reference images |
| ------------------------ | -------------------- |
| `gemini-3-pro-image` | 14 |
| `gemini-3.1-flash-image` | 14 |
| `gpt-image-2` | 4 |
| `seedream-5-0-pro` | 10 |
The schema caps `referenceImages` at 14 items overall. GPT-Image-2 enforces a tighter limit of 4 and
Seedream 5.0 Pro a limit of 10 — exceeding it returns `400`. Accepted MIME types for both `fileData` and `inlineData` are
`image/png`, `image/jpeg`, `image/webp`, `image/heic`, and `image/heif`.
Seedream 5.0 Pro precise editing [#seedream-50-pro-precise-editing]
Seedream 5.0 Pro supports **precise editing**: changing a specific region of an image instead of
regenerating the whole thing.
There is no separate edit endpoint and no mask or region parameter — editing uses the same
generation endpoint, with the source image in `referenceImages` and the "what to change, and how"
written into `prompt`. The model reads absolute pixel coordinates (origin at the top-left corner of
the image) and industry color codes directly.
```json
{
"provider": "bytedance",
"model": "seedream-5-0-pro",
"prompt": "Treating the top-left corner as the coordinate origin, change the content inside top-left:(376,363) bottom-right:(701,638) to green, and leave everything else unchanged",
"referenceImages": [
{
"fileData": {
"fileUri": "https://assets.listenhub.app/your-source-image.png",
"mimeType": "image/png"
}
}
],
"imageConfig": { "imageSize": "2K", "aspectRatio": "1:1" }
}
```
> If your product offers visual editing gestures (box select, lasso, arrows), translate them into
> coordinate strings in your own frontend — or bake the annotations into the reference image — before
> writing them into `prompt`. The server passes the prompt through verbatim and does not parse
> coordinates. Keep `aspectRatio` matching the source image's real ratio; a mismatch can make the
> model reconstruct the whole image instead of editing one region.
Estimate credits [#estimate-credits]
`POST /v1/images/generation/estimate-credits`
Returns the credit cost for a given configuration and whether your account can generate it, without
spending credits or calling the model. Use it to show a price before committing, or to check whether
a `4K` / `high` request needs a subscription. Accepts the same body as the generation endpoints;
`provider` and `prompt` are optional here.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/images/generation/estimate-credits" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "gpt-image-2",
"imageConfig": {
"imageSize": "2K",
"aspectRatio": "1:1",
"quality": "medium"
}
}'
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/images/generation/estimate-credits',
{
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
model: 'gpt-image-2',
imageConfig: { imageSize: '2K', aspectRatio: '1:1', quality: 'medium' },
}),
},
)
const { data } = await response.json()
console.log(data.credits, data.canGenerate)
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/images/generation/estimate-credits',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'model': 'gpt-image-2',
'imageConfig': {'imageSize': '2K', 'aspectRatio': '1:1', 'quality': 'medium'},
},
)
data = response.json()['data']
print(data['credits'], data['canGenerate'])
```
Estimate response [#estimate-response]
Wrapped in the standard envelope. The `data` object:
| Field | Type | Description |
| ---------------------- | ------- | --------------------------------------------------------------------- |
| `model` | string | Normalized GA model ID used for the estimate |
| `imageSize` | string | Resolved output size |
| `aspectRatio` | string | Resolved aspect ratio (absent when the model auto-selects) |
| `quality` | string | Resolved quality (absent when not applicable) |
| `pixels` | object | `{ "width": number, "height": number, "size": "WxH" }` when resolved |
| `credits` | number | Credits this configuration would cost |
| `canGenerate` | boolean | Whether the account has enough effective credit balance |
| `requiresSubscription` | boolean | `true` when the config needs an active paid plan (e.g. `4K`, `high`) |
| `pricing` | object | Pricing metadata: `pricingVersion`, `mode` (`token-estimate`/`fixed`) |
| `warnings` | array | Advisory strings, e.g. `reference_image_input_tokens_not_included` |
```json
{
"code": 0,
"message": "",
"data": {
"model": "gpt-image-2",
"imageSize": "2K",
"aspectRatio": "1:1",
"quality": "medium",
"pixels": { "width": 2048, "height": 2048, "size": "2048x2048" },
"credits": 6,
"canGenerate": true,
"requiresSubscription": false,
"pricing": { "pricingVersion": "...", "mode": "token-estimate" },
"warnings": []
}
}
```
Asynchronous generation [#asynchronous-generation]
For long-running or high-resolution jobs, submit the task and poll for the result instead of holding
a request open.
Create an async task [#create-an-async-task]
`POST /v1/images/generation/async`
Same request body as the synchronous endpoint. Returns `202` with a `taskId` immediately; generation
runs in the background and the resulting images are persisted as hosted URLs.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/images/generation/async" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"provider": "google",
"model": "gemini-3-pro-image",
"prompt": "An astronaut riding a horse on Mars, photorealistic",
"imageConfig": { "imageSize": "4K", "aspectRatio": "16:9" }
}'
```
**JavaScript:**
```javascript
const res = await fetch(
'https://api.marswave.ai/openapi/v1/images/generation/async',
{
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
provider: 'google',
model: 'gemini-3-pro-image',
prompt: 'An astronaut riding a horse on Mars, photorealistic',
imageConfig: { imageSize: '4K', aspectRatio: '16:9' },
}),
},
)
const { data } = await res.json()
const taskId = data.taskId
```
**Python:**
```python
import os
import requests
res = requests.post(
'https://api.marswave.ai/openapi/v1/images/generation/async',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'provider': 'google',
'model': 'gemini-3-pro-image',
'prompt': 'An astronaut riding a horse on Mars, photorealistic',
'imageConfig': {'imageSize': '4K', 'aspectRatio': '16:9'},
},
)
task_id = res.json()['data']['taskId']
```
Response (`202`):
```json
{
"code": 0,
"message": "",
"data": { "taskId": "65f0...", "status": "pending" }
}
```
Get a task [#get-a-task]
`GET /v1/images/generation/tasks/{taskId}`
Poll for the status and result of a single task. `status` is one of `pending`, `generating`,
`success`, or `fail`. On success, `images` holds the hosted result URLs.
```bash
curl "https://api.marswave.ai/openapi/v1/images/generation/tasks/65f0abc..." \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
```json
{
"code": 0,
"message": "",
"data": {
"taskId": "65f0abc...",
"status": "success",
"images": [
{ "url": "https://.../0.png", "mimeType": "image/png" }
],
"createdAt": 1750000000000,
"completedAt": 1750000020000
}
}
```
| Field | Type | Description |
| ------------- | ------ | ---------------------------------------------------- |
| `taskId` | string | Task identifier |
| `status` | string | `pending`, `generating`, `success`, or `fail` |
| `images` | array | Present on success; each item is `{ url, mimeType }` |
| `failMsg` | string | Failure message when `status` is `fail` |
| `createdAt` | number | Creation time (epoch milliseconds) |
| `completedAt` | number | Completion time (epoch milliseconds), when finished |
List tasks [#list-tasks]
`GET /v1/images/generation/tasks`
List your image tasks, newest first.
| Query param | Type | Default | Description |
| ----------- | ------ | ------- | ------------------------------------------------------- |
| `page` | number | `1` | Page number, minimum `1` |
| `pageSize` | number | `20` | Items per page, `1`–`100` |
| `status` | string | — | Filter by `pending`, `generating`, `success`, or `fail` |
```bash
curl "https://api.marswave.ai/openapi/v1/images/generation/tasks?page=1&pageSize=20&status=success" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
```json
{
"code": 0,
"message": "",
"data": {
"items": [
{ "taskId": "65f0...", "status": "success", "images": [/* ... */], "createdAt": 1750000000000, "completedAt": 1750000020000 }
],
"page": 1,
"pageSize": 20,
"total": 1
}
}
```
> Background tasks left in `pending` or `generating` for more than 30 minutes are swept to `fail`
> with a timeout `failMsg`. Treat a non-terminal status older than that as failed and retry.
Response formats [#response-formats]
| Endpoint | Wrapped envelope? | Body |
| --------------------------------------------- | ------------------- | -------------------------------------------- |
| `POST /v1/images/generation` | No — raw model JSON | Base64 image data (see below) |
| `POST /v1/images/generation/async` | Yes | `{ taskId, status }` |
| `POST /v1/images/generation/estimate-credits` | Yes | Estimate object |
| `GET /v1/images/generation/tasks` | Yes | Paginated `{ items, page, pageSize, total }` |
| `GET /v1/images/generation/tasks/{taskId}` | Yes | Task object |
The **synchronous** endpoint returns the raw model output directly (not wrapped). A successful body
contains the generated image as base64 data:
```json
{
"candidates": [
{
"content": {
"parts": [
{
"inlineData": {
"mimeType": "image/png",
"data": ""
}
}
]
}
}
]
}
```
Decode the `data` field from base64 to obtain the image file. The **async** path persists the image
for you and returns hosted `url`s on the task object — no base64 decoding needed.
NanoBanana Pro free quota [#nanobanana-pro-free-quota]
API key calls draw on the same account-level free-quota (`freeUsages`) balance as the web and
Labnana apps. You keep **earning** quota through sign-up, invites, and check-ins, then spend it
through the API. Query the live balance via
[`GET /v1/user/subscription`](/docs/en/openapi/api-reference/subscription) and read its `freeUsages`
map.
When the matching balance is greater than `0`, a `1K` / `2K` request spends one free generation
instead of credits. Once the balance hits `0`, the same request falls back to normal credit billing.
> Free quota applies only to **`1K` and `2K`** sizes. A `4K` request never draws from `freeUsages`
> and is always billed in credits.
**How a NanoBanana Pro relax call runs depends on your account type:**
* **Paid or charged accounts** (active subscription, recharge, or credit-pack purchase) get the
normal paid generation experience even while spending free quota — full priority, normal capacity,
normal fallback. The free quota only changes billing; it does not put you on a throttled lane.
* **Pure-free accounts** (never paid anything) run NanoBanana Pro relax on a lowest-priority free
lane with a fixed throughput cap. At peak times a request may be queued or rejected with a
retryable busy/timeout response. When that happens, **no credits are spent and the free quota is
not consumed** — retry later (it is faster late at night).
A pure-free relax failure returns machine-readable metadata so you can detect it without parsing
localized text:
* `failReason` is `free_relax_busy` or `free_relax_timeout`.
* `retryable` is `true`.
* `freeUsageRolledBack` is `true` once the free quota has been refunded.
* `userMessage` carries friendly, localizable copy.
For synchronous requests this appears in the error body; for async requests it appears on the failed
task detail (and in the task list). Treat both reasons as "retry later, nothing was charged".
Rate limiting and reference image mode [#rate-limiting-and-reference-image-mode]
Standard text-to-image requests are subject to per-user and global rate limits.
> **Reference image mode** (`referenceImages` with `inlineData`) is subject to additional
> server-side resource constraints. During peak periods, base64 requests may be throttled more
> aggressively. On a `429`, read the `Retry-After` header and back off before retrying. Implement
> exponential backoff in your client.
Error codes [#error-codes]
Errors use the standard envelope (`code` non-zero) or, for the synchronous endpoint, the raw error
body documented in [NanoBanana Pro free quota](#nanobanana-pro-free-quota).
| HTTP status | Meaning |
| ----------- | ----------------------------------------------------------------------------------- |
| `400` | Invalid request parameters (e.g. an aspect ratio unsupported by the selected model) |
| `402` | Insufficient credits |
| `429` | Rate limited or service busy — read `Retry-After` and retry |
| `500` | Image generation failed — retry the request |
Related [#related]
- **Subscription & Credits** -- Check your credit and free-quota balance [/docs/en/openapi/api-reference/subscription](/docs/en/openapi/api-reference/subscription)
- **Content Extraction** -- Turn URLs and files into structured content [/docs/en/openapi/api-reference/content-extract](/docs/en/openapi/api-reference/content-extract)
# ListenHub Voice (/docs/en/openapi/api-reference/listenhub-voice)
The ListenHub Voice API generates audio end to end — plain narration, sound effects, single-voice speech, multi-speaker dialogue, voice cloning from a reference clip, or image-to-audio. Generation is asynchronous: you submit a request and poll a task until it finishes. All endpoints live under `https://api.marswave.ai/openapi/v1/listenhub-voice` and authenticate with `Authorization: Bearer $LISTENHUB_API_KEY`.
> ListenHub Voice costs **30 credits per generated minute**. Billing uses the actual generated audio duration, with a minimum charge of **1 credit** per task.
> Every response is wrapped in `{ "code": 0, "message": "", "data": { ... } }`. A non-zero `code` means an error — see [Error Handling](/docs/en/openapi/errors). The examples below read fields from `data`.
Model and Limits [#model-and-limits]
| Item | Value |
| -------------- | -------------------------------------------------------------- |
| `model` | `listenhub-voice-1.0` (default, the only supported value) |
| Rate limit | 5 requests per minute, per user, on `/generate` |
| `text` | Up to 1400 characters |
| `voices` | 1–3 entries (omit for plain text / sound effects) |
| `durationHint` | 1–110 seconds (credit estimate + a hint for the target length) |
Voices [#voices]
`voices` controls who speaks. Each entry is one of two kinds:
| `type` | Required field | Description |
| ----------- | -------------- | -------------------------------------------------------------------------------------------------------------------------------------------------- |
| `speaker` | `id` | A built-in voice — a ListenHub voice code or a platform `voice_type`. Do not send `url` for this type. |
| `reference` | `url` | A custom reference audio URL (http/https) to clone the voice from. Up to 30s, ≤10MB, `wav`/`mp3`/`pcm`/`ogg_opus`. Do not send `id` for this type. |
For multi-speaker dialogue, list 2–3 voices and prefix each line of `text` with `@音频1`, `@音频2`, … to assign lines to voices in order. Omit `voices` entirely to generate plain narration or pure sound effects.
> `voices` and `image` are mutually exclusive — send at most one. A request that
> includes both is rejected. A `speaker` entry must carry only `id`; a
> `reference` entry must carry only `url`. Mixing them returns `33004` (invalid
> params).
Async Task Lifecycle [#async-task-lifecycle]
1. Submit a generation request to `POST /v1/listenhub-voice/generate`. The response carries a `taskId` and an initial `status` of `pending`.
2. Poll `GET /v1/listenhub-voice/tasks/{taskId}`. `status` moves through `pending` → `generating` → `uploading` → `success`.
3. On `success`, read `audioUrl`. On `failed`, read `errorMessage`.
| Status | Meaning |
| ------------ | ------------------------------------------------------------------------------------- |
| `pending` | Created, waiting to be submitted for generation. |
| `generating` | Generation in progress. `audioUrl` is not yet available. |
| `uploading` | Generation finished, transferring the audio to storage. |
| `success` | Done. `audioUrl` is available. |
| `failed` | Failed at some stage. `errorMessage` explains why; any reserved credits are refunded. |
Create a ListenHub Voice Task [#create-a-listenhub-voice-task]
`POST /v1/listenhub-voice/generate`
Submit text (optionally with voices or a reference image) for end-to-end audio generation. Sends JSON. Returns `202` with a `taskId`.
**cURL:**
```bash
# Plain text / sound effects (no voices)
curl -X POST "https://api.marswave.ai/openapi/v1/listenhub-voice/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"text": "A gentle rain falls on a quiet street at midnight.",
"durationHint": 20
}'
# Single voice (speaker)
curl -X POST "https://api.marswave.ai/openapi/v1/listenhub-voice/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"text": "Welcome to ListenHub. Here is your daily briefing.",
"voices": [{ "type": "speaker", "id": "zh_female_warm" }]
}'
# Voice cloning from a reference clip
curl -X POST "https://api.marswave.ai/openapi/v1/listenhub-voice/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"text": "@音频1 Hi there! @音频2 Hello, how can I help?",
"voices": [
{ "type": "reference", "url": "https://example.com/host.mp3" },
{ "type": "speaker", "id": "zh_male_calm" }
]
}'
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/listenhub-voice/generate',
{
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
text: 'Welcome to ListenHub. Here is your daily briefing.',
voices: [{ type: 'speaker', id: 'zh_female_warm' }],
durationHint: 20,
}),
},
)
const { data } = await response.json()
console.log('Task ID:', data.taskId)
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/listenhub-voice/generate',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'text': 'Welcome to ListenHub. Here is your daily briefing.',
'voices': [{'type': 'speaker', 'id': 'zh_female_warm'}],
'durationHint': 20,
},
)
data = response.json()['data']
print('Task ID:', data['taskId'])
```
For image-to-audio, send an `image` object instead of `voices` (the two are mutually exclusive):
```json
{
"text": "Describe this scene as a short narrated clip.",
"image": { "url": "https://example.com/scene.jpg" }
}
```
**Request parameters**:
| Field | Type | Required | Description |
| -------------- | ------- | -------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `model` | string | No | `listenhub-voice-1.0`. Defaults to `listenhub-voice-1.0` |
| `text` | string | Yes | Script to speak. Up to 1400 characters. Use `@音频N` prefixes to assign dialogue lines to voices |
| `voices` | array | No | 1–3 voice entries (see [Voices](#voices)). Omit for plain text / sound effects. Mutually exclusive with `image` |
| `image` | object | No | Reference image for image-to-audio. Provide exactly one of `url` (http/https) or `data` (Base64, optionally with a `data:image/...;base64,` prefix). One image, ≤10MB, `jpeg`/`png`/`webp`. Mutually exclusive with `voices` |
| `audioConfig` | object | No | Output tuning (see below) |
| `durationHint` | number | No | Target length, `1`–`110` seconds. Drives the credit estimate and hints the model |
| `watermark` | boolean | No | Add an audio watermark |
`audioConfig` fields:
| Field | Type | Required | Description |
| -------------- | ------ | -------- | -------------------------------------------- |
| `speechRate` | number | No | Speaking rate, `-50`–`100` |
| `loudnessRate` | number | No | Loudness, `-50`–`100` |
| `pitchRate` | number | No | Pitch, `-12`–`12` |
| `format` | string | No | `mp3` (default), `wav`, `pcm`, or `ogg_opus` |
Returns `202`:
```json
{
"code": 0,
"message": "",
"data": {
"taskId": "68e780390fc5c9a54f695a7e",
"status": "pending"
}
}
```
Get a Task [#get-a-task]
`GET /v1/listenhub-voice/tasks/{taskId}`
Fetch a single task. This is the endpoint you poll after submitting a generation request.
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/listenhub-voice/tasks/{taskId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
`https://api.marswave.ai/openapi/v1/listenhub-voice/tasks/${taskId}`,
{ headers: { Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}` } },
)
const { data } = await response.json()
console.log('Status:', data.status)
if (data.status === 'success') console.log('Audio:', data.audioUrl)
```
**Python:**
```python
import os
import requests
response = requests.get(
f'https://api.marswave.ai/openapi/v1/listenhub-voice/tasks/{task_id}',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
)
data = response.json()['data']
print('Status:', data['status'])
if data['status'] == 'success':
print('Audio:', data['audioUrl'])
```
A successful task:
```json
{
"code": 0,
"message": "",
"data": {
"id": "68e780390fc5c9a54f695a7e",
"status": "success",
"model": "listenhub-voice-1.0",
"params": {
"text": "Welcome to ListenHub. Here is your daily briefing.",
"voices": [{ "type": "speaker", "id": "zh_female_warm" }]
},
"audioUrl": "https://assets.listenhub.app/listenhub-voice/68e780390fc5c9a54f695a7e.mp3",
"audioDuration": 18.4,
"creditCharged": 10,
"creditRefunded": 0,
"createdAt": 1730000000000,
"updatedAt": 1730000040000
}
}
```
**Task response fields**:
| Field | Type | Description |
| ---------------- | ------ | ----------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `id` | string | Task ID |
| `status` | string | `pending`, `generating`, `uploading`, `success`, or `failed` |
| `model` | string | `listenhub-voice-1.0` |
| `params` | object | Echo of the submitted request (sensitive image/audio payloads are stripped; an inline image shows as `{ "hasData": true }` with an optional `thumbnailUrl`) |
| `audioUrl` | string | Finished audio URL. Returned only when `status` is `success` |
| `audioDuration` | number | Audio length in seconds (the billed duration) |
| `creditCharged` | number | Credits actually charged (`0` if not yet charged) |
| `creditRefunded` | number | Credits refunded on failure (for reconciliation) |
| `errorMessage` | string | Failure reason. Returned only when `status` is `failed` |
| `createdAt` | number | Creation time (ms timestamp) |
| `updatedAt` | number | Last update time (ms timestamp) |
List Tasks [#list-tasks]
`GET /v1/listenhub-voice/tasks`
List your ListenHub Voice tasks, newest first.
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/listenhub-voice/tasks?page=1&pageSize=20&status=success" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/listenhub-voice/tasks?page=1&pageSize=20',
{ headers: { Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}` } },
)
const { data } = await response.json()
console.log(`${data.total} tasks, showing ${data.items.length}`)
```
**Python:**
```python
import os
import requests
response = requests.get(
'https://api.marswave.ai/openapi/v1/listenhub-voice/tasks',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
params={'page': 1, 'pageSize': 20},
)
data = response.json()['data']
print(data['total'], 'tasks, showing', len(data['items']))
```
**Query parameters**:
| Field | Type | Required | Description |
| ---------- | ------- | -------- | ---------------------------------------------------------------------- |
| `page` | integer | No | Page number, min `1`. Defaults to `1` |
| `pageSize` | integer | No | Items per page, `1`–`100`. Defaults to `20` |
| `status` | string | No | Filter by `pending`, `generating`, `uploading`, `success`, or `failed` |
| `keyword` | string | No | Fuzzy match against the task `text`. Up to 64 characters |
Response:
```json
{
"code": 0,
"message": "",
"data": {
"items": [
{
"id": "68e780390fc5c9a54f695a7e",
"status": "success",
"model": "listenhub-voice-1.0",
"audioUrl": "https://assets.listenhub.app/listenhub-voice/68e780390fc5c9a54f695a7e.mp3",
"audioDuration": 18.4,
"creditCharged": 10,
"creditRefunded": 0,
"createdAt": 1730000000000,
"updatedAt": 1730000040000
}
],
"page": 1,
"pageSize": 20,
"total": 1
}
}
```
Each item carries the same fields as [Get a Task](#get-a-task).
Errors [#errors]
Business errors return HTTP `400` with the specific code in the top-level `code` field.
| Code | Meaning |
| ------- | ---------------------------------------------------------------------------------------------------- |
| `33001` | Task not found (or not owned by the current API user) |
| `33002` | Speaker not found for a `speaker` voice entry |
| `33003` | Generation service unavailable |
| `33004` | Invalid parameters (e.g. `voices` and `image` sent together, or a voice entry mixing `id` and `url`) |
| `33005` | Too many voices (max 3) |
| `33006` | Not enough credits |
| `33007` | Rate limited |
| `33008` | Generation timed out |
| `33009` | Per-user concurrency limit reached |
| HTTP status | Meaning |
| ----------- | -------------------------------------------------------------------- |
| `400` | Invalid parameters or a business error — see the `33xxx` codes above |
| `429` | Rate limit exceeded (5 RPM per user on `/generate`) |
Credits [#credits]
Credits are reserved at submission, confirmed on `success`, and refunded automatically on `failed`. Each task reports `creditCharged` (actually charged) and `creditRefunded` (refunded on failure) for reconciliation. The billed length is the actual generated `audioDuration`; the charge is `max(1, ceil(audioDuration × 30 / 60))` credits. Check your live balance with [`GET /v1/user/subscription`](/docs/en/openapi/api-reference/subscription), and see [Pricing](/docs/en/openapi/pricing) for credit-to-feature mapping.
# Music Generation (/docs/en/openapi/api-reference/music)
The Music API turns text, lyrics, images, or reference audio into music, and analyzes existing tracks. Generation is backed by [Mureka](https://www.mureka.ai/). All endpoints live under `https://api.marswave.ai/openapi/v1/music` and authenticate with `Authorization: Bearer $LISTENHUB_API_KEY`.
The API splits into two response patterns:
| Pattern | Endpoints | How results come back |
| -------------------- | -------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------- |
| **Async generation** | `/generate`, `/instrumental`, `/soundtrack`, `/track`, `/remix`, `/extend` | Returns `202` with a `taskId`. Poll `GET /v1/music/tasks/{taskId}` until `status` is `success`. |
| **Sync analysis** | `/recognize`, `/describe`, `/stem` | Returns `200` with the result in the same response. No polling. |
> Every response is wrapped in `{ "code": 0, "message": "", "data": { ... } }`. A non-zero `code` means an error — see [Error Handling](/docs/en/openapi/errors). The examples below read fields from `data`.
Models [#models]
Generation endpoints accept a `model` parameter using a provider-neutral contract. Mureka models:
| Model | Notes |
| ------------ | --------------------------------------- |
| `auto` | Default. Lets the service pick a model. |
| `mureka-7.6` | |
| `mureka-8` | |
| `mureka-9` | Not available for `/instrumental`. |
| `mureka-o2` | |
Stem separation (`/stem`) uses a different model set: `audio-separation-1` (default) or `audio-separation-2` (also produces MIDI).
Async Task Lifecycle [#async-task-lifecycle]
1. Submit a generation request. The response carries a `taskId` and an initial `status` of `pending`.
2. Poll `GET /v1/music/tasks/{taskId}`. `status` moves through `pending` → `generating` → `uploading` → `success`.
3. On `success`, read the finished `tracks` array (title, tags, duration, signed `audioUrl`). On `failed`, read `errorMessage`.
Recommended polling: wait \~30 seconds after submission, then poll every 10 seconds. A music task usually completes in 1–3 minutes.
```json
{
"code": 0,
"message": "",
"data": {
"id": "68e780390fc5c9a54f695a7e",
"provider": "mureka",
"taskType": "GENERATE",
"status": "success",
"params": {
"model": "auto",
"prompt": "r&b, slow, passionate, male vocal",
"instrumental": false
},
"tracks": [
{
"title": "Night Walk",
"tags": "r&b, slow",
"duration": 142.5,
"audioUrl": "https://assets.listenhub.app/.../track-1.mp3"
}
],
"creditCost": 20,
"createdAt": 1730000000000,
"updatedAt": 1730000180000
}
}
```
> Track `audioUrl` values are signed and expire about 1 hour after the task is fetched. Download the audio or re-fetch the task to refresh the URLs before they expire.
Generate from Text or Lyrics [#generate-from-text-or-lyrics]
`POST /v1/music/generate`
Create a song from a style prompt and/or lyrics. Sends JSON. For Mureka, non-instrumental requests should include `lyrics`.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/music/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"prompt": "r&b, slow, passionate, male vocal",
"lyrics": "[verse]\nWalking down the empty street at night\n[chorus]\nFeel the rhythm, feel the light",
"title": "Night Walk",
"model": "auto"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/music/generate', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
prompt: 'r&b, slow, passionate, male vocal',
lyrics: '[verse]\nWalking down the empty street at night\n[chorus]\nFeel the rhythm, feel the light',
title: 'Night Walk',
model: 'auto',
}),
});
const { data } = await response.json();
console.log('Task ID:', data.taskId);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/music/generate',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'prompt': 'r&b, slow, passionate, male vocal',
'lyrics': '[verse]\nWalking down the empty street at night\n[chorus]\nFeel the rhythm, feel the light',
'title': 'Night Walk',
'model': 'auto',
},
)
data = response.json()['data']
print('Task ID:', data['taskId'])
```
**Request parameters**:
| Field | Type | Required | Description |
| ---------------- | ------- | -------- | -------------------------------------------------------------- |
| `prompt` | string | No | Style/description prompt |
| `lyrics` | string | No | Lyrics. Required for Mureka when not instrumental |
| `style` | string | No | Style tag. Used as a fallback for `prompt` |
| `title` | string | No | Track title |
| `instrumental` | boolean | No | Generate without vocals |
| `model` | string | No | See [Models](#models). Defaults to `auto` |
| `vocalId` | string | No | Reuse a Mureka vocal id |
| `provider` | string | No | `default` (Mureka), `mureka`, or `suno`. Defaults to `default` |
| `providerParams` | object | No | Provider-specific parameters |
Returns `202` with `{ "taskId": "...", "status": "pending" }`. Poll the task to get the result.
Generate an Instrumental [#generate-an-instrumental]
`POST /v1/music/instrumental`
Create a standalone instrumental from a text prompt **or** a reference audio file. Provide exactly one of `prompt` or `referenceAudio`. Sends `multipart/form-data`.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/music/instrumental" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-F "prompt=lofi hip hop, mellow, rainy night" \
-F "model=auto"
```
**JavaScript:**
```javascript
const form = new FormData();
form.append('prompt', 'lofi hip hop, mellow, rainy night');
form.append('model', 'auto');
const response = await fetch('https://api.marswave.ai/openapi/v1/music/instrumental', {
method: 'POST',
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
body: form,
});
const { data } = await response.json();
console.log('Task ID:', data.taskId);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/music/instrumental',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
data={'prompt': 'lofi hip hop, mellow, rainy night', 'model': 'auto'},
)
data = response.json()['data']
print('Task ID:', data['taskId'])
```
**Request parameters**:
| Field | Type | Required | Description |
| ---------------- | ------ | -------- | --------------------------------------------------------------------- |
| `prompt` | string | One of | Style/genre description. Mutually exclusive with `referenceAudio` |
| `referenceAudio` | file | One of | Reference audio (mp3/m4a, max 10MB). Mutually exclusive with `prompt` |
| `model` | string | No | `auto`, `mureka-7.6`, `mureka-8`, or `mureka-o2`. Defaults to `auto` |
Generate a Soundtrack from Image or Video [#generate-a-soundtrack-from-image-or-video]
`POST /v1/music/soundtrack`
Generate music that matches an image or video. Provide exactly one of `image` or `video`. Sends `multipart/form-data`.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/music/soundtrack" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-F "image=@scene.jpg" \
-F "prompt=cinematic, hopeful, orchestral" \
-F "model=auto"
```
**JavaScript:**
```javascript
import { readFile } from 'node:fs/promises';
const form = new FormData();
form.append('image', new Blob([await readFile('scene.jpg')]), 'scene.jpg');
form.append('prompt', 'cinematic, hopeful, orchestral');
form.append('model', 'auto');
const response = await fetch('https://api.marswave.ai/openapi/v1/music/soundtrack', {
method: 'POST',
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
body: form,
});
const { data } = await response.json();
console.log('Task ID:', data.taskId);
```
**Python:**
```python
import os
import requests
with open('scene.jpg', 'rb') as f:
response = requests.post(
'https://api.marswave.ai/openapi/v1/music/soundtrack',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
files={'image': f},
data={'prompt': 'cinematic, hopeful, orchestral', 'model': 'auto'},
)
data = response.json()['data']
print('Task ID:', data['taskId'])
```
**Request parameters**:
| Field | Type | Required | Description |
| -------- | ------ | -------- | -------------------------------------------------------------------------------- |
| `image` | file | One of | Image (jpg/jpeg/png/webp). Mutually exclusive with `video` |
| `video` | file | One of | Video (mp4/mov/avi/mkv/webm). Mutually exclusive with `image` |
| `prompt` | string | No | Style/description prompt |
| `model` | string | No | `auto`, `mureka-7.6`, `mureka-8`, `mureka-9`, or `mureka-o2`. Defaults to `auto` |
Generate a Single Track [#generate-a-single-track]
`POST /v1/music/track`
Generate one instrument or vocal track from a reference audio file **or** an existing Mureka `providerSongId`. Provide exactly one of `audio` or `providerSongId`. Sends `multipart/form-data`.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/music/track" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-F "audio=@reference.mp3" \
-F "generateType=Drums" \
-F "prompt=funk, tight groove, 110 bpm"
```
**JavaScript:**
```javascript
import { readFile } from 'node:fs/promises';
const form = new FormData();
form.append('audio', new Blob([await readFile('reference.mp3')]), 'reference.mp3');
form.append('generateType', 'Drums');
form.append('prompt', 'funk, tight groove, 110 bpm');
const response = await fetch('https://api.marswave.ai/openapi/v1/music/track', {
method: 'POST',
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
body: form,
});
const { data } = await response.json();
console.log('Task ID:', data.taskId);
```
**Python:**
```python
import os
import requests
with open('reference.mp3', 'rb') as f:
response = requests.post(
'https://api.marswave.ai/openapi/v1/music/track',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
files={'audio': f},
data={'generateType': 'Drums', 'prompt': 'funk, tight groove, 110 bpm'},
)
data = response.json()['data']
print('Task ID:', data['taskId'])
```
**Request parameters**:
| Field | Type | Required | Description |
| ---------------- | ------ | ------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `generateType` | string | Yes | Target track type. One of `Vocals`, `Instrumental`, `Drums`, `Bass`, `Guitar`, `Keyboard`, `Percussion`, `Strings`, `Synth`, `FX`, `Brass`, `Woodwinds` |
| `prompt` | string | Yes | Style/genre description |
| `audio` | file | One of | Reference audio (mp3/m4a/wav, max 10MB). Mutually exclusive with `providerSongId` |
| `providerSongId` | string | One of | Mureka song id from a previous result. Mutually exclusive with `audio` |
| `lyrics` | string | When `Vocals` | Lyrics. Required when `generateType` is `Vocals` |
| `vocalGender` | string | No | `male` or `female`. Only for `generateType=Vocals` |
| `generateStart` | number | No | Range start in seconds |
| `generateEnd` | number | No | Range end in seconds |
Remix an Existing Song [#remix-an-existing-song]
`POST /v1/music/remix`
Re-perform an existing song with new lyrics. Provide the source audio in exactly one way: an uploaded `audio` file, an internal ListenHub `audioUrl`, or a Mureka `providerSongId`. Sends `multipart/form-data`.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/music/remix" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-F "audio=@original.mp3" \
-F "lyrics=[verse]\nA brand new story to tell" \
-F "prompt=upbeat pop, bright synths"
```
**JavaScript:**
```javascript
import { readFile } from 'node:fs/promises';
const form = new FormData();
form.append('audio', new Blob([await readFile('original.mp3')]), 'original.mp3');
form.append('lyrics', '[verse]\nA brand new story to tell');
form.append('prompt', 'upbeat pop, bright synths');
const response = await fetch('https://api.marswave.ai/openapi/v1/music/remix', {
method: 'POST',
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
body: form,
});
const { data } = await response.json();
console.log('Task ID:', data.taskId);
```
**Python:**
```python
import os
import requests
with open('original.mp3', 'rb') as f:
response = requests.post(
'https://api.marswave.ai/openapi/v1/music/remix',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
files={'audio': f},
data={
'lyrics': '[verse]\nA brand new story to tell',
'prompt': 'upbeat pop, bright synths',
},
)
data = response.json()['data']
print('Task ID:', data['taskId'])
```
**Request parameters**:
| Field | Type | Required | Description |
| ---------------- | ------ | ---------- | -------------------------------------------------------------- |
| `lyrics` | string | Yes | New lyrics |
| `prompt` | string | Yes | Style/genre description |
| `audio` | file | One source | Audio file (mp3/m4a, max 10MB) |
| `audioUrl` | string | One source | Internal ListenHub audio URL (must belong to you or be public) |
| `providerSongId` | string | One source | Mureka song id from a previous result |
Extend a Song [#extend-a-song]
`POST /v1/music/extend`
Continue an existing song from a chosen point in time. Sends `multipart/form-data`. Supply the source via `audio`, `uploadUrl`, or `providerSongId`.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/music/extend" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-F "audio=@original.mp3" \
-F "model=mureka-8" \
-F "extendAt=30" \
-F "extendType=tail"
```
**JavaScript:**
```javascript
import { readFile } from 'node:fs/promises';
const form = new FormData();
form.append('audio', new Blob([await readFile('original.mp3')]), 'original.mp3');
form.append('model', 'mureka-8');
form.append('extendAt', '30');
form.append('extendType', 'tail');
const response = await fetch('https://api.marswave.ai/openapi/v1/music/extend', {
method: 'POST',
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
body: form,
});
const { data } = await response.json();
console.log('Task ID:', data.taskId);
```
**Python:**
```python
import os
import requests
with open('original.mp3', 'rb') as f:
response = requests.post(
'https://api.marswave.ai/openapi/v1/music/extend',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
files={'audio': f},
data={'model': 'mureka-8', 'extendAt': '30', 'extendType': 'tail'},
)
data = response.json()['data']
print('Task ID:', data['taskId'])
```
**Request parameters** (Mureka path):
| Field | Type | Required | Description |
| ---------------- | ------- | ---------- | -------------------------------------------------------------------------------------- |
| `audio` | file | One source | Audio file (mp3/m4a, max 10MB). Mutually exclusive with `uploadUrl` / `providerSongId` |
| `uploadUrl` | string | One source | Audio URL (any reachable external link or internal GCS URL) |
| `providerSongId` | string | One source | Mureka song id from a previous result |
| `model` | string | No | See [Models](#models) |
| `extendAt` | number | No | Time offset (seconds, 8–420) to extend from |
| `extendType` | string | No | `tail` (forward, default) or `head` (backward, `mureka-8` only) |
| `lyrics` | string | No | Lyrics for the new section |
| `prompt` | string | No | Style/description |
| `style` | string | No | Music style |
| `title` | string | No | Track title |
| `instrumental` | boolean | No | Generate the new section without vocals |
> `/extend` also supports a Suno path with `continueAt`, `uploadUrl`, and Suno model versions. Pass `provider=suno` and the Suno-specific fields. Mureka is the default provider.
Recognize Lyrics [#recognize-lyrics]
`POST /v1/music/recognize`
Transcribe lyrics with timestamped sections from an audio file. **Synchronous** — the result is in the response. Sends `multipart/form-data`.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/music/recognize" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-F "audio=@song.mp3"
```
**JavaScript:**
```javascript
import { readFile } from 'node:fs/promises';
const form = new FormData();
form.append('audio', new Blob([await readFile('song.mp3')]), 'song.mp3');
const response = await fetch('https://api.marswave.ai/openapi/v1/music/recognize', {
method: 'POST',
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
body: form,
});
const { data } = await response.json();
console.log('Sections:', data.result.lyricsSections.length);
```
**Python:**
```python
import os
import requests
with open('song.mp3', 'rb') as f:
response = requests.post(
'https://api.marswave.ai/openapi/v1/music/recognize',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
files={'audio': f},
)
data = response.json()['data']
print('Sections:', len(data['result']['lyricsSections']))
```
**Request parameters**:
| Field | Type | Required | Description |
| ------- | ---- | -------- | ------------------------------ |
| `audio` | file | Yes | Audio file (mp3/m4a, max 10MB) |
The `data.result` object contains `duration` and a `lyricsSections` array.
Describe Audio [#describe-audio]
`POST /v1/music/describe`
Analyze an audio file and return a description plus tags, genres, and instruments. **Synchronous.** Sends `multipart/form-data`.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/music/describe" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-F "audio=@song.mp3"
```
**JavaScript:**
```javascript
import { readFile } from 'node:fs/promises';
const form = new FormData();
form.append('audio', new Blob([await readFile('song.mp3')]), 'song.mp3');
const response = await fetch('https://api.marswave.ai/openapi/v1/music/describe', {
method: 'POST',
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
body: form,
});
const { data } = await response.json();
console.log(data.result.description, data.result.genres);
```
**Python:**
```python
import os
import requests
with open('song.mp3', 'rb') as f:
response = requests.post(
'https://api.marswave.ai/openapi/v1/music/describe',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
files={'audio': f},
)
data = response.json()['data']
print(data['result']['description'], data['result']['genres'])
```
**Request parameters**:
| Field | Type | Required | Description |
| ------- | ---- | -------- | ----------------------------------------- |
| `audio` | file | Yes | Audio file to analyze (mp3/m4a, max 10MB) |
The `data.result` object contains `description`, `tags`, `genres`, and `instruments`.
Separate Stems [#separate-stems]
`POST /v1/music/stem`
Split an audio file into stems (vocals, bass, drums, other) and return download URLs. **Synchronous.** Sends `multipart/form-data`.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/music/stem" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-F "audio=@song.mp3" \
-F "model=audio-separation-1"
```
**JavaScript:**
```javascript
import { readFile } from 'node:fs/promises';
const form = new FormData();
form.append('audio', new Blob([await readFile('song.mp3')]), 'song.mp3');
form.append('model', 'audio-separation-1');
const response = await fetch('https://api.marswave.ai/openapi/v1/music/stem', {
method: 'POST',
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
body: form,
});
const { data } = await response.json();
console.log('Stems ZIP:', data.result.zipUrl);
```
**Python:**
```python
import os
import requests
with open('song.mp3', 'rb') as f:
response = requests.post(
'https://api.marswave.ai/openapi/v1/music/stem',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
files={'audio': f},
data={'model': 'audio-separation-1'},
)
data = response.json()['data']
print('Stems ZIP:', data['result']['zipUrl'])
```
**Request parameters**:
| Field | Type | Required | Description |
| ------- | ------ | -------- | --------------------------------------------------------------------------- |
| `audio` | file | Yes | Audio file to separate (mp3/m4a, max 10MB) |
| `model` | string | No | `audio-separation-1` (default) or `audio-separation-2` (also produces MIDI) |
The `data.result` object contains `zipUrl`, `midiZipUrl` (when `audio-separation-2`), and `expiresAt`. Download links expire about 24 hours after generation.
List Tasks [#list-tasks]
`GET /v1/music/tasks`
List your music tasks, newest first.
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/music/tasks?page=1&pageSize=20&status=success" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/music/tasks?page=1&pageSize=20',
{ headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` } }
);
const { data } = await response.json();
console.log(`${data.length} tasks`);
```
**Python:**
```python
import os
import requests
response = requests.get(
'https://api.marswave.ai/openapi/v1/music/tasks',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
params={'page': 1, 'pageSize': 20},
)
print(len(response.json()['data']), 'tasks')
```
**Query parameters**:
| Field | Type | Required | Description |
| ---------- | ------- | -------- | ---------------------------------------------------------------------- |
| `page` | integer | No | Page number, min `1`. Defaults to `1` |
| `pageSize` | integer | No | Items per page, `1`–`100`. Defaults to `20` |
| `status` | string | No | Filter by `pending`, `generating`, `uploading`, `success`, or `failed` |
Get a Task [#get-a-task]
`GET /v1/music/tasks/{taskId}`
Fetch a single task. This is the endpoint you poll after submitting an async generation request.
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/music/tasks/{taskId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
`https://api.marswave.ai/openapi/v1/music/tasks/${taskId}`,
{ headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` } }
);
const { data } = await response.json();
console.log('Status:', data.status);
if (data.status === 'success') console.log('Audio:', data.tracks[0].audioUrl);
```
**Python:**
```python
import os
import requests
response = requests.get(
f'https://api.marswave.ai/openapi/v1/music/tasks/{task_id}',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
)
data = response.json()['data']
print('Status:', data['status'])
if data['status'] == 'success':
print('Audio:', data['tracks'][0]['audioUrl'])
```
**Task response fields**:
| Field | Type | Description |
| -------------- | ------ | ------------------------------------------------------------------------- |
| `id` | string | Task ID |
| `provider` | string | `default`, `mureka`, or `suno` |
| `taskType` | string | `GENERATE`, `INSTRUMENTAL`, `REMIX`, `EXTEND`, `COVER` |
| `status` | string | `pending`, `generating`, `uploading`, `success`, `failed` |
| `params` | object | Echo of the generation request |
| `tracks` | array | Finished tracks: `title`, `tags`, `duration` (seconds), signed `audioUrl` |
| `creditCost` | number | Credits consumed |
| `errorMessage` | string | Failure reason (only when `status` is `failed`) |
| `createdAt` | number | Creation time (ms timestamp) |
| `updatedAt` | number | Last update time (ms timestamp) |
Credits [#credits]
Each endpoint consumes credits by model tier. For async generation, credits are reserved at submission, confirmed on `success`, and refunded automatically on `failure`. The exact cost is returned per task as `creditCost` (and per analysis call as `creditCost` in the result). Check your live balance with [`GET /v1/user/subscription`](/docs/en/openapi/api-reference/subscription), and see [Pricing](/docs/en/openapi/pricing) for credit-to-feature mapping.
SDK and CLI [#sdk-and-cli]
The official SDK and CLI wrap every endpoint on this page, including async polling.
- **JavaScript SDK** -- OpenAPIClient.createMusicGenerate / createMusicInstrumental / createMusicSoundtrack / createMusicTrack / createMusicRemix, plus recognizeMusic / describeMusic / stemMusic and getMusicTask / listMusicTasks. [/docs/en/openapi/quick-start](/docs/en/openapi/quick-start)
- **CLI** -- listenhub openapi music generate | instrumental | soundtrack | track | remix | recognize | describe | stem | list | get — with --no-wait and --timeout for polling. [/docs/en/openapi/quick-start](/docs/en/openapi/quick-start)
# Podcast (/docs/en/openapi/api-reference/podcast)
The Podcast API turns a prompt and optional reference sources into a fully produced episode: a written script with assigned voices, rendered audio, and subtitles. You can generate everything in one call, or split it into two stages — generate the script first, review or edit it, then render audio.
All requests use the base URL `https://api.marswave.ai/openapi/v1` and require an API key:
```
Authorization: Bearer $LISTENHUB_API_KEY
```
Create keys at [listenhub.ai/settings/api-keys](https://listenhub.ai/settings/api-keys). Every response is wrapped in `{ "code": 0, "message": "", "data": { ... } }`; a non-zero `code` indicates an error.
***
Create a Podcast [#create-a-podcast]
`POST /v1/podcast/episodes`
Generate a complete episode (script + audio) in a single call. The request returns immediately with an `episodeId`; generation runs asynchronously, so [poll the episode](#query-episode-status) until it finishes.
Request parameters [#request-parameters]
| Field | Type | Required | Description |
| ---------- | ------ | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `query` | string | No | The prompt or topic to generate from. May be empty when `sources` carries the material. |
| `sources` | array | No | Reference material. Each item is `{ "type": "text" \| "url", "content": "..." }`. For `url`, `content` is the link; for `text`, `content` is the raw text. |
| `speakers` | array | Yes | 1 to 2 speakers, each `{ "speakerId": "..." }`. One speaker produces a monologue; two produce a conversation. `debate` mode requires exactly 2. |
| `language` | string | No | Output language, e.g. `en`, `zh`, `ja`. When omitted, the language is inferred from the input. |
| `mode` | string | No | Generation mode. One of `quick`, `deep`, `debate`. Defaults to `quick`. |
| `speed` | number | No | Generation speed multiplier — the speaking rate of the generated audio, not a player playback rate. Range `0.5`–`2.0`, at most two decimals. Defaults to `1` (original speed). |
Provide at least one of `query` or `sources`. Look up `speakerId` values with the [Speakers API](/docs/en/openapi/api-reference/speakers).
Modes [#modes]
| Mode | Speakers | Best for |
| -------- | --------- | --------------------------------------------------------------- |
| `quick` | 1 or 2 | Fast turnaround on time-sensitive content. The default. |
| `deep` | 1 or 2 | In-depth, research-style episodes on professional topics. |
| `debate` | Exactly 2 | A two-sided discussion where speakers argue distinct positions. |
> Credit cost depends on the mode and length. Do not assume a fixed price — the `credits` field on the episode reflects the actual charge, and you can check your live balance with [`GET /v1/user/subscription`](/docs/en/openapi/api-reference/subscription). See [Pricing](/docs/en/openapi/pricing) for the credit-to-feature mapping.
Single-speaker example [#single-speaker-example]
A monologue in `quick` mode:
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/podcast/episodes" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"query": "Give a short technology news briefing for today.",
"speakers": [
{"speakerId": ""}
],
"language": "en",
"mode": "quick"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/podcast/episodes', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
query: 'Give a short technology news briefing for today.',
speakers: [{ speakerId: '' }],
language: 'en',
mode: 'quick',
}),
});
const data = await response.json();
console.log(data);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/podcast/episodes',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'query': 'Give a short technology news briefing for today.',
'speakers': [{'speakerId': ''}],
'language': 'en',
'mode': 'quick',
}
)
data = response.json()
print(data)
```
Dual-speaker example [#dual-speaker-example]
A two-host `deep` episode:
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/podcast/episodes" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"query": "Analyze the technical foundations and future outlook of large language models.",
"speakers": [
{"speakerId": ""},
{"speakerId": ""}
],
"language": "en",
"mode": "deep"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/podcast/episodes', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
query: 'Analyze the technical foundations and future outlook of large language models.',
speakers: [
{ speakerId: '' },
{ speakerId: '' },
],
language: 'en',
mode: 'deep',
}),
});
const data = await response.json();
console.log(data);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/podcast/episodes',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'query': 'Analyze the technical foundations and future outlook of large language models.',
'speakers': [
{'speakerId': ''},
{'speakerId': ''},
],
'language': 'en',
'mode': 'deep',
}
)
data = response.json()
print(data)
```
Debate mode [#debate-mode]
`debate` requires exactly 2 speakers:
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/podcast/episodes" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"query": "Should remote work become the default model?",
"speakers": [
{"speakerId": ""},
{"speakerId": ""}
],
"language": "en",
"mode": "debate"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/podcast/episodes', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
query: 'Should remote work become the default model?',
speakers: [
{ speakerId: '' },
{ speakerId: '' },
],
language: 'en',
mode: 'debate',
}),
});
const data = await response.json();
console.log(data);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/podcast/episodes',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'query': 'Should remote work become the default model?',
'speakers': [
{'speakerId': ''},
{'speakerId': ''},
],
'language': 'en',
'mode': 'debate',
}
)
data = response.json()
print(data)
```
With reference sources [#with-reference-sources]
Pass `sources` to ground the episode in specific material. Each entry is either a URL to fetch or raw text:
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/podcast/episodes" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"query": "Summarize and discuss the core ideas in this article.",
"sources": [
{
"type": "url",
"content": "https://blog.samaltman.com/reflections"
}
],
"speakers": [
{"speakerId": ""},
{"speakerId": ""}
],
"language": "en",
"mode": "deep"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/podcast/episodes', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
query: 'Summarize and discuss the core ideas in this article.',
sources: [
{ type: 'url', content: 'https://blog.samaltman.com/reflections' },
],
speakers: [
{ speakerId: '' },
{ speakerId: '' },
],
language: 'en',
mode: 'deep',
}),
});
const data = await response.json();
console.log(data);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/podcast/episodes',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'query': 'Summarize and discuss the core ideas in this article.',
'sources': [
{'type': 'url', 'content': 'https://blog.samaltman.com/reflections'}
],
'speakers': [
{'speakerId': ''},
{'speakerId': ''},
],
'language': 'en',
'mode': 'deep',
}
)
data = response.json()
print(data)
```
Response [#response]
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "665f1c2a9b3e4d0012a8c7e1"
}
}
```
`episodeId` is the handle for every follow-up call. Save it and poll for status.
***
Query Episode Status [#query-episode-status]
`GET /v1/podcast/episodes/{episodeId}`
Fetch the current state and, once finished, the produced assets. Poll this endpoint after creating an episode until generation completes.
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/podcast/episodes/{episodeId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
`https://api.marswave.ai/openapi/v1/podcast/episodes/${episodeId}`,
{ headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` } }
);
const data = await response.json();
console.log('Status:', data.data.processStatus);
console.log('Audio URL:', data.data.audioUrl);
```
**Python:**
```python
import os
import requests
response = requests.get(
f'https://api.marswave.ai/openapi/v1/podcast/episodes/{episode_id}',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
data = response.json()
print('Status:', data['data']['processStatus'])
print('Audio URL:', data['data']['audioUrl'])
```
Response fields [#response-fields]
| Field | Type | Description |
| --------------------- | ------ | -------------------------------------------------------------------------------------------------------------------------------------------------- |
| `episodeId` | string | The episode identifier. |
| `createdAt` | number | Creation timestamp (epoch milliseconds). |
| `processStatus` | string | Overall job status: `pending`, `success`, or `fail`. |
| `contentStatus` | string | Stage-level status, present in the two-stage workflow: `text-success`, `text-fail`, `audio-success`, `audio-fail`. Absent for one-shot generation. |
| `failCode` | number | Failure reason code; `0` when there is no failure. |
| `message` | string | Human-readable status detail. |
| `completedTime` | number | Completion timestamp (epoch milliseconds). |
| `credits` | number | Credits consumed so far. |
| `title` | string | Generated episode title. |
| `outline` | string | Generated outline. |
| `cover` | string | Cover image URL. |
| `audioUrl` | string | Final audio file URL (MP3). |
| `audioStreamUrl` | string | Streaming audio URL (HLS `.m3u8`). |
| `subtitlesUrl` | string | Subtitle file URL (SRT). |
| `sourceProcessResult` | object | Processed source material: `content` plus a `references` array of citations. |
| `scripts` | array | Per-line script: each item is `{ "speakerId", "speakerName", "content" }`. |
Response when generation is complete (`processStatus: "success"`):
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "665f1c2a9b3e4d0012a8c7e1",
"processStatus": "success",
"failCode": 0,
"credits": 27,
"title": "The Story of AI: How the Intelligent Age Was Born",
"audioUrl": "https://assets.listenhub.app/listenhub-public-prod/podcast/665f1c2a9b3e4d0012a8c7e1.mp3",
"audioStreamUrl": "https://assets.listenhub.app/listenhub-public-prod/podcast/665f1c2a9b3e4d0012a8c7e1.m3u8",
"scripts": [
{
"speakerId": "",
"speakerName": "Ethan",
"content": "These days it feels like AI news surrounds us everywhere."
}
]
}
}
```
> Podcast generation typically takes 1 to 4 minutes. Recommended polling: wait 60 seconds before the first request, then poll every 10 seconds. On failure, `processStatus` is `fail` and `failCode` indicates the reason.
Stream script and outline (SSE) [#stream-script-and-outline-sse]
`GET /v1/podcast/episodes/{episodeId}/text-stream?event={script|outline}`
While the script or outline is being generated, subscribe to a Server-Sent Events stream to receive text incrementally instead of polling. The `event` query parameter selects which stream:
* `outline` — the outline as it is written.
* `script` — the line-by-line script as it is written.
```bash
curl -N "https://api.marswave.ai/openapi/v1/podcast/episodes/{episodeId}/text-stream?event=script" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
The response is an `text/event-stream`; read it as a stream rather than parsing it as a single JSON body. Use it for live progress UIs. To read the final assets (audio, subtitles), use the [status endpoint](#query-episode-status) once generation completes.
***
Two-Stage Generation [#two-stage-generation]
Split generation into two independent calls: produce the script first, inspect or edit it, then render audio. This is the right pattern when you need a human or automated review step before committing to audio, or when you want to account for text-generation and audio-generation credits separately.
The flow has two endpoints:
1. `POST /v1/podcast/episodes/text-content` — generate the script only.
2. `POST /v1/podcast/episodes/{episodeId}/audio` — render audio from the (optionally edited) script.
> `language` is **required** in `text-content`, and each speaker's language must match the `language` value. A mismatch returns a `Speaker language mismatch` error.
1. Generate the script [#generate-the-script]
`POST /v1/podcast/episodes/text-content` accepts the same `query`, `sources`, `speakers`, and `mode` fields as one-shot creation, but `language` is required here. It produces the script with no audio:
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/podcast/episodes/text-content" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"query": "Discuss the current state of quantum computing.",
"speakers": [
{"speakerId": ""},
{"speakerId": ""}
],
"language": "en",
"mode": "deep"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/podcast/episodes/text-content', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
query: 'Discuss the current state of quantum computing.',
speakers: [
{ speakerId: '' },
{ speakerId: '' },
],
language: 'en',
mode: 'deep',
}),
});
const data = await response.json();
const episodeId = data.data.episodeId;
console.log('Episode ID:', episodeId);
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/podcast/episodes/text-content',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'query': 'Discuss the current state of quantum computing.',
'speakers': [
{'speakerId': ''},
{'speakerId': ''},
],
'language': 'en',
'mode': 'deep',
}
)
data = response.json()
episode_id = data['data']['episodeId']
print('Episode ID:', episode_id)
```
**Response:**
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "665f1c2a9b3e4d0012a8c7e1",
"message": "Text content generation started. Audio generation can be triggered later."
}
}
```
2. Wait for the script [#wait-for-the-script]
Poll `GET /v1/podcast/episodes/{episodeId}` until `contentStatus` is `text-success`. In the two-stage flow, `contentStatus` is the field that tells you which stage is done — check it rather than `processStatus`.
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/podcast/episodes/{episodeId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const result = await fetch(`https://api.marswave.ai/openapi/v1/podcast/episodes/${episodeId}`, {
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
});
const status = await result.json();
console.log('Content status:', status.data.contentStatus);
```
**Python:**
```python
import os
import requests
result = requests.get(
f'https://api.marswave.ai/openapi/v1/podcast/episodes/{episode_id}',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
status = result.json()
print('Content status:', status['data']['contentStatus'])
```
Script-ready response (`contentStatus: "text-success"`):
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "665f1c2a9b3e4d0012a8c7e1",
"processStatus": "success",
"contentStatus": "text-success",
"credits": 15,
"title": "Quantum Computing: Present and Future",
"outline": "...",
"scripts": [
{
"speakerId": "",
"speakerName": "Ethan",
"content": "Welcome to this discussion on quantum computing..."
},
{
"speakerId": "",
"speakerName": "Sophia",
"content": "Quantum computing is exciting and rapidly evolving..."
}
]
}
}
```
> For a live progress UI, subscribe to the SSE stream at `/v1/podcast/episodes/{episodeId}/text-stream?event=script` instead of polling.
3. (Optional) Edit the script [#optional-edit-the-script]
Take the `scripts` array from the previous response and rewrite line content as needed.
> Only `content` may change. Keep each line's `speakerId` exactly as returned, and keep the script to the same 1 to 2 distinct speakers — this is a hard API constraint.
Pass the edited array as the request body in the next step.
4. Render audio [#render-audio]
`POST /v1/podcast/episodes/{episodeId}/audio`. Send an empty body to render the original script, or pass a `scripts` array (each item `{ "content", "speakerId" }`) to render your edited version. Add `speed` to change how fast the audio is spoken — range `0.5`–`2.0`, at most two decimals, default `1`:
**cURL:**
```bash
# Render the original script
curl -X POST "https://api.marswave.ai/openapi/v1/podcast/episodes/{episodeId}/audio" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json"
# Render an edited script
curl -X POST "https://api.marswave.ai/openapi/v1/podcast/episodes/{episodeId}/audio" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"scripts": [
{
"content": "Welcome to this episode. Today we go deeper into quantum computing...",
"speakerId": ""
},
{
"content": "This field has moved quickly from theory to practical experiments...",
"speakerId": ""
}
]
}'
```
**JavaScript:**
```javascript
// Render the original script
await fetch(`https://api.marswave.ai/openapi/v1/podcast/episodes/${episodeId}/audio`, {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
});
// Render an edited script
await fetch(`https://api.marswave.ai/openapi/v1/podcast/episodes/${episodeId}/audio`, {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
scripts: [
{ content: 'Welcome to this episode. Today we go deeper into quantum computing...', speakerId: '' },
{ content: 'This field has moved quickly from theory to practical experiments...', speakerId: '' },
],
}),
});
```
**Python:**
```python
import os
import requests
# Render the original script
requests.post(
f'https://api.marswave.ai/openapi/v1/podcast/episodes/{episode_id}/audio',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
# Render an edited script
requests.post(
f'https://api.marswave.ai/openapi/v1/podcast/episodes/{episode_id}/audio',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'scripts': [
{'content': 'Welcome to this episode. Today we go deeper into quantum computing...', 'speakerId': ''},
{'content': 'This field has moved quickly from theory to practical experiments...', 'speakerId': ''},
]
}
)
```
**Response:**
```json
{
"code": 0,
"message": "",
"data": {
"success": true,
"message": "Audio generation started",
"episodeId": "665f1c2a9b3e4d0012a8c7e1",
"status": "submit"
}
}
```
5. Wait for audio [#wait-for-audio]
Continue polling `GET /v1/podcast/episodes/{episodeId}` until `contentStatus` is `audio-success`. The audio, streaming, and subtitle URLs are then populated:
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "665f1c2a9b3e4d0012a8c7e1",
"processStatus": "success",
"contentStatus": "audio-success",
"credits": 42,
"title": "Quantum Computing: Present and Future",
"audioUrl": "https://assets.listenhub.app/podcast/665f1c2a9b3e4d0012a8c7e1.mp3",
"audioStreamUrl": "https://assets.listenhub.app/podcast/665f1c2a9b3e4d0012a8c7e1.m3u8",
"subtitlesUrl": "https://assets.listenhub.app/podcast/665f1c2a9b3e4d0012a8c7e1.srt",
"scripts": [ ]
}
}
```
contentStatus reference [#contentstatus-reference]
| Value | Meaning | Next step |
| --------------- | -------------------------- | --------------------- |
| `text-success` | Script generation complete | Render audio |
| `text-fail` | Script generation failed | Recreate the episode |
| `audio-success` | Audio generation complete | Done |
| `audio-fail` | Audio generation failed | Retry audio rendering |
**Credits:** Stage 1 consumes text-generation credits; Stage 2 consumes audio-generation credits. The `credits` field accumulates across both stages and reflects the actual charge. Check your live balance with [`GET /v1/user/subscription`](/docs/en/openapi/api-reference/subscription), and see [Pricing](/docs/en/openapi/pricing) for the credit-to-feature mapping.
***
Related [#related]
- **Speakers** -- List available voices and their speakerId values [/docs/en/openapi/api-reference/speakers](/docs/en/openapi/api-reference/speakers)
- **FlowSpeech** -- Render raw text or scripts directly to audio [/docs/en/openapi/api-reference/flowspeech](/docs/en/openapi/api-reference/flowspeech)
# Slides (/docs/en/openapi/api-reference/slides)
Slides mode generates professional presentation-style content with AI visuals and voiceover scripts — ideal for meetings, business reports, and conference talks.
| | Detail |
| ---------------- | --------------------------------------------------------- |
| **Visual style** | PPT layouts (grid, process flow, big number hero) |
| **Page 1** | Presentation title page |
| **Best for** | Meeting presentations, business reports, conference talks |
> To export as a PPT file, use the ListenHub platform directly — PPT export is not available via the OpenAPI.
***
Create Slides Episode [#create-slides-episode]
`POST /v1/storybook/episodes`
Create a slides episode with AI-generated presentation visuals and voiceover scripts.
> `sources` accepts at most 1 item. `speakers` accepts at most 1 item.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/storybook/episodes" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"sources": [
{"type": "text", "content": "Q3 revenue grew 45% year-over-year, driven by expansion in APAC markets..."}
],
"speakers": [
{"speakerId": ""}
],
"language": "en",
"mode": "slides"
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/storybook/episodes', {
method: 'POST',
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
sources: [{ type: 'text', content: 'Q3 revenue grew 45% year-over-year, driven by expansion in APAC markets...' }],
speakers: [{ speakerId: '' }],
language: 'en',
mode: 'slides',
}),
});
const data = await response.json();
console.log(data);
```
**Python:**
```python
import os, requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/storybook/episodes',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'sources': [{'type': 'text', 'content': 'Q3 revenue grew 45% year-over-year, driven by expansion in APAC markets...'}],
'speakers': [{'speakerId': ''}],
'language': 'en',
'mode': 'slides',
}
)
print(response.json())
```
**Response**:
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "{episodeId}"
}
}
```
Request Parameters [#request-parameters]
| Parameter | Type | Required | Description |
| --------------------- | -------- | -------- | ------------------------------------------------------------ |
| sources | array(1) | Yes | Content source. Max 1 item. |
| sources\[].type | string | Yes | `"text"` or `"url"` |
| sources\[].content | string | Yes | Text content or URL |
| sources\[].uri | string | No | Source URI |
| sources\[].metadata | object | No | Source metadata |
| speakers | array(1) | Yes | Voice config. Max 1 item. |
| speakers\[].speakerId | string | Yes | Speaker ID (see [Speakers](/openapi/api-reference/speakers)) |
| language | string | No | Language code (e.g. `"en"`, `"zh"`) |
| mode | string | Yes | Must be `"slides"` |
| style | string | No | Visual style ID |
***
Query Episode Status [#query-episode-status]
`GET /v1/storybook/episodes/{episodeId}`
Poll with the returned `episodeId` until `processStatus` is `success`.
**cURL:**
```bash
curl "https://api.marswave.ai/openapi/v1/storybook/episodes/{episodeId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
`https://api.marswave.ai/openapi/v1/storybook/episodes/${episodeId}`,
{ headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` } }
);
const data = await response.json();
console.log('Status:', data.data.processStatus);
```
**Python:**
```python
import os, requests
response = requests.get(
f'https://api.marswave.ai/openapi/v1/storybook/episodes/{episode_id}',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
data = response.json()
print('Status:', data['data']['processStatus'])
```
**Response** (when `processStatus` is `success`):
```json
{
"code": 0,
"message": "",
"data": {
"episodeId": "{episodeId}",
"createdAt": 1700000000,
"mode": "slides",
"processStatus": "success",
"credits": 30,
"title": "Q3 Business Review",
"cover": "https://assets.listenhub.app/covers/{episodeId}.png",
"audioUrl": "https://assets.listenhub.app/storybook/{episodeId}.mp3",
"audioDuration": 180,
"videoUrl": "",
"videoStatus": "not_generated",
"pages": [
{
"text": "Welcome to the Q3 business review. This quarter saw remarkable growth...",
"pageNumber": 1,
"imageUrl": "https://assets.listenhub.app/pages/{episodeId}-1.png",
"audioTimestamp": 0
},
{
"text": "Revenue grew 45% year-over-year, primarily driven by APAC expansion...",
"pageNumber": 2,
"imageUrl": "https://assets.listenhub.app/pages/{episodeId}-2.png",
"audioTimestamp": 25.3
}
]
}
}
```
> **Slides + voiceover scripts**: Each item in `pages[]` contains an `imageUrl` (slide visual) and `text` (voiceover script, \~80–100 words per slide). Download these to build your own presentations or remix the content.
processStatus [#processstatus]
| Value | Meaning |
| --------- | ------------------------- |
| `pending` | Processing |
| `success` | Complete |
| `fail` | Failed (check `failCode`) |
videoStatus [#videostatus]
| Value | Meaning |
| --------------- | ---------------------------------- |
| `not_generated` | Video not yet triggered |
| `pending` | Video generating |
| `success` | Video ready (`videoUrl` available) |
| `fail` | Video generation failed |
> Generation typically takes 2–5 minutes. Recommended polling: wait 60 seconds, then poll every 10 seconds.
***
Generate Video [#generate-video]
`POST /v1/storybook/episodes/{episodeId}/video`
Trigger video generation for a completed slides episode. `processStatus` must be `success`.
> Wait until `processStatus` is `success` before calling this endpoint.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/storybook/episodes/{episodeId}/video" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
`https://api.marswave.ai/openapi/v1/storybook/episodes/${episodeId}/video`,
{
method: 'POST',
headers: { 'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}` },
}
);
console.log(await response.json());
```
**Python:**
```python
import os, requests
response = requests.post(
f'https://api.marswave.ai/openapi/v1/storybook/episodes/{episode_id}/video',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
print(response.json())
```
**Response**:
```json
{
"code": 0,
"message": "",
"data": {
"success": true
}
}
```
After triggering, poll `GET /v1/storybook/episodes/{episodeId}` until `videoStatus` is `success`.
***
Complete Workflow [#complete-workflow]
1. Create Slides Episode [#create-slides-episode-1]
Call `POST /v1/storybook/episodes` with `mode: "slides"`, your source, and speaker. Save the returned `episodeId`.
2. Poll for Completion [#poll-for-completion]
Poll `GET /v1/storybook/episodes/{episodeId}` every 10 seconds (after an initial 60-second wait) until `processStatus` is `success`.
3. Use Slides + Scripts (Optional) [#use-slides--scripts-optional]
The `pages[]` array contains slide visuals (`imageUrl`) and voiceover scripts (`text`). Download these to build your own presentations without generating a video.
4. Generate Video [#generate-video-1]
Call `POST /v1/storybook/episodes/{episodeId}/video` to combine slides into a narrated video.
5. Poll Video Status [#poll-video-status]
Poll until `videoStatus` is `success`. The `videoUrl` field contains the download link.
# Speakers (/docs/en/openapi/api-reference/speakers)
List Available Speakers [#list-available-speakers]
`GET /v1/speakers/list`
Retrieve all available speakers, including cloned voices, for content generation. The endpoint returns both your private (cloned) voices and the public catalog. Filter by `language` to narrow the list to a single locale.
> Only this endpoint returns your cloned voices, and it requires an API key. If you just need the public catalogue — to pick a voice by ear, or to give an agent the whole list in one request — [`listenhub.ai/voices.txt`](https://listenhub.ai/voices.txt) serves every official voice as plain text with no authentication, and [`listenhub.ai/voices`](https://listenhub.ai/voices) is the same catalogue with audio previews.
**Query parameters**:
| Parameter | Type | Required | Description |
| ---------- | ------- | -------- | --------------------------------------------------------------------------------------------- |
| `language` | string | No | Filter by language code, e.g. `en`, `zh`, `ja`. Omit to return speakers in all languages. |
| `status` | integer | No | Catalog status filter. `3` returns published speakers (default), `1` returns active speakers. |
**Request examples**:
**cURL:**
```bash
# List Chinese speakers
curl -X GET "https://api.marswave.ai/openapi/v1/speakers/list?language=zh" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
# List English speakers
curl -X GET "https://api.marswave.ai/openapi/v1/speakers/list?language=en" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/speakers/list?language=en', {
headers: {
'Authorization': `Bearer ${process.env.LISTENHUB_API_KEY}`,
},
});
const data = await response.json();
console.log(data);
```
**Python:**
```python
import os
import requests
response = requests.get(
'https://api.marswave.ai/openapi/v1/speakers/list',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
params={'language': 'en'}
)
data = response.json()
print(data)
```
**Response example**:
```json
{
"code": 0,
"message": "",
"data": {
"items": [
{
"name": "Marcus",
"speakerId": "Marcus-9aa6846b",
"demoAudioUrl": "https://assets.listenhub.app/listenhub-public-prod/audios/Marcus-9aa6846b_demo_audio.mp3",
"gender": "male",
"language": "en",
"profile": {
"pitch": ["medium-high"],
"speed": ["medium-fast"],
"traits": ["clear", "bright", "friendly", "fluent"],
"styles": ["professional", "friendly", "energetic"],
"scenes": ["podcast", "narration", "advertising"],
"accent": "American English",
"description": "A clear, bright, and energetic male voice, ideal for creating engaging podcasts and professional narration.",
"descriptionLocalized": {
"zh": "清晰明亮、充满活力的男声,适合制作引人入胜的播客和专业旁白。",
"en": "A clear, bright, and energetic male voice, ideal for creating engaging podcasts and professional narration."
}
}
}
]
}
}
```
**Response fields**:
| Field | Type | Description |
| ------------------------------ | --------- | ------------------------------------------------------ |
| `name` | string | Display name of the speaker |
| `speakerId` | string | Unique identifier, used when creating content |
| `demoAudioUrl` | string | URL to the speaker's demo audio |
| `gender` | string | `"male"` or `"female"` |
| `language` | string | Language code, e.g. `"en"`, `"zh"` |
| `profile` | object | Voice profile describing the listening experience |
| `profile.pitch` | string\[] | Pitch range, e.g. `["medium-high"]` |
| `profile.speed` | string\[] | Speaking speed, e.g. `["medium-fast"]` |
| `profile.traits` | string\[] | Voice characteristics, e.g. `["clear", "bright"]` |
| `profile.styles` | string\[] | Emotional styles, e.g. `["professional", "friendly"]` |
| `profile.scenes` | string\[] | Recommended use cases, e.g. `["podcast", "narration"]` |
| `profile.accent` | string | Accent description, e.g. `"American English"` |
| `profile.description` | string | Overall voice description in English |
| `profile.descriptionLocalized` | object | Localized descriptions keyed by language code |
***
Voice Preview [#voice-preview]
The `demoAudioUrl` field in the API response provides a direct link to each speaker's demo audio. You can use it to let your users preview a voice before selecting it for content generation.
**All available English voices:**
| Speaker | ID | Gender | Description | Preview |
| ---------------- | ------------------------------------------------------------------- | ------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------------ | -------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Mia | | Female | A clear, bright voice at a moderately fast pace with a warm, friendly narration style, suitable for various narration and audio content. | |
| Leo | | Male | A clear, bright young male voice with a slight nasal quality, suitable for conversational content like podcasts, vlogs, and presentations. | |
| Marcus | | Male | A clear, bright, and energetic male voice, ideal for creating engaging podcasts and professional narration. | |
| Aoede | | Female | A clear, bright female voice at a moderate pace with a calm, elegant narrative style, suitable for audiobooks and documentary narration. | |
| David | | Male | A clear, steady male voice that is professional and confident, suitable for business presentations, knowledge sharing, and narration. | |
| Reed | | Female | A clear, professional, and confident voice, suitable for business presentations, news broadcasts, and educational content, conveying authority and composure. | |
| Sarah | | Female | Clear and bright with a moderate pace, full of energy, suitable for professional settings like podcasts, business presentations, and teaching. | |
| Ashley | | Female | A clear, bright, and energetic voice, perfect for sharing life experiences and friendly conversations. | |
| Leda | | Female | Clear and soft with a moderate pace, mellow and steady tone, suitable for audiobooks and documentary narration. | |
| Mars | | Male | A clear, steady, and magnetic voice, suitable for podcast narration, documentary commentary, and various professional content. | |
| Catherine | | Female | A clear, steady female voice with warm tones, full of confidence and guidance, suitable for business presentations, knowledge sharing, and narration. | |
| Arthur | | Male | A clear, confident, and professional male voice with medium-low pitch and moderately fast pace, ideal for business, news, and documentary narration. | |
| Iris | | Female | A clear, warm female voice at a moderate pace, full of approachability, suitable for audiobooks and customer service. | |
| Host Maya | | Female | A clear, bright, and energetic female voice with a friendly, approachable tone, suitable for podcasts, explainers, and promotional content. | |
| Host Sam | | Male | A clear, bright male voice at a moderately fast pace, full of energy and enthusiasm, suitable for podcasts, travel vlogs, and casual narration. | |
| Host John | | Male | An energetic and enthusiastic male voice, ideal for game streaming and esports commentary. | |
| Host Claire | | Female | A clear, bright, and energetic female voice with a warm, friendly style, suitable for live streaming, podcasts, and welcome speeches. | |
| Meditation Nate | | Male | A deep, soft, and magnetic male voice at a slow pace, ideal for guiding meditation, sleep aid, and deep relaxation. | |
| Meditation Kate | | Female | A soft, warm female voice at a slow pace, suitable for meditation, sleep aid, and guided relaxation. | |
| Story Pixie | | Male | A clear, bright, and charming voice, perfect for telling fantasy stories and children's content. | |
| Storyteller Finn | | Male | A clear, warm male voice at a moderate pace with a magnetic quality, suitable for telling mysterious and engaging stories. | |
| Eliot (ASMR) | | Male | A deep, magnetic, breathy male voice at a slow, gentle pace, ideal for ASMR sleep aid, meditation, and relaxation, delivering ultimate calm and comfort. | |
| Lily (ASMR) | | Female | A soft, calm, breathy voice at a slow pace, suitable for ASMR, bedtime stories, and meditation, providing a soothing and relaxing experience. | |
| Charon | | Male | A deep, magnetic voice with a steady pace, full of mystery and narrative quality, suitable for horror, suspense narration, or audiobooks. | |
| Orus | | Male | A steady, magnetic male voice at a moderately fast pace with clear pronunciation, suitable for history, science, and educational narration or audiobooks. | |
| Noah | | Male | A warm, mellow voice at a moderate pace, suitable for various professional broadcasts and communication scenarios. | |
| Michael | | Male | A clear, steady, and professional male voice, suitable for business presentations, podcasts, and various educational training content. | |
| Daniel | | Male | A clear, steady, and professional male voice, suitable for knowledge sharing, business presentations, and news broadcasts. | |
| Olivia | | Female | A clear, warm female voice suitable for narration and professional content. | |
| Owen | | Male | A clear, steady male voice with a magnetic and professional quality at a moderate pace, suitable for documentary narration, corporate videos, and news broadcasts. | |
***
# Subscription (/docs/en/openapi/api-reference/subscription)
Query Subscription and Credit Balance [#query-subscription-and-credit-balance]
`GET /v1/user/subscription`
Query account credits, subscription status, and related metadata.
**Request example**:
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/user/subscription" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/user/subscription',
{
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
},
},
)
const data = await response.json()
console.log(data)
```
**Python:**
```python
import os
import requests
response = requests.get(
'https://api.marswave.ai/openapi/v1/user/subscription',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'}
)
data = response.json()
print(data)
```
**Response example**:
```json
{
"code": 0,
"message": "",
"data": {
"subscriptionStartedAt": 1735660800000,
"subscriptionExpiresAt": 1767196800000,
"usageAvailableMonthlyCredits": 500,
"usageTotalMonthlyCredits": 1000,
"usageAvailablePermanentCredits": 300,
"usageTotalPermanentCredits": 500,
"usageAvailableLimitedTimeCredits": 200,
"totalAvailableCredits": 1000,
"resetAt": 1735660800000,
"platform": "web",
"renewStatus": false,
"paidStatus": true,
"subscriptionPlan": {
"name": "pro",
"duration": "monthly",
"platform": "web"
},
"freeUsages": {
"gemini-3-pro-image-relax-1k-2k": {
"remaining": 2,
"resourceType": "image",
"resourceKey": "gemini-3-pro-image-relax-1k-2k",
"unit": "generation"
},
"wan2.7-image": {
"remaining": 1,
"resourceType": "image",
"resourceKey": "wan2.7-image",
"unit": "generation"
},
"gpt-image-2": {
"remaining": 1,
"resourceType": "image",
"resourceKey": "gpt-image-2",
"unit": "generation"
}
}
}
}
```
**Response fields**:
All timestamps are 13-digit epoch-millisecond numbers. Fields tied to a plan (`subscriptionStartedAt`, `subscriptionExpiresAt`, `subscriptionPlan.*`) are only populated while a subscription is active; on a free account `subscriptionPlan` is `{}`.
| Field | Type | Description |
| ---------------------------------- | ------- | ------------------------------------------------------------------------- |
| `totalAvailableCredits` | integer | Total credits you can spend right now: monthly + permanent + time-limited |
| `usageAvailableMonthlyCredits` | integer | Monthly credits remaining this cycle |
| `usageTotalMonthlyCredits` | integer | Monthly credit allotment for the cycle |
| `usageAvailablePermanentCredits` | integer | Permanent credits remaining (do not reset) |
| `usageTotalPermanentCredits` | integer | Total permanent credits granted |
| `usageAvailableLimitedTimeCredits` | integer | Time-limited credits remaining |
| `resetAt` | integer | When monthly credits reset (epoch ms) |
| `subscriptionStartedAt` | integer | Subscription start time (epoch ms) |
| `subscriptionExpiresAt` | integer | Subscription expiration time (epoch ms) |
| `platform` | string | Billing platform, e.g. `web`, `ios`, `android`. Defaults to `web` |
| `renewStatus` | boolean | Whether auto-renew is on |
| `paidStatus` | boolean | Whether the subscription is a paid (non-trial) active plan |
| `subscriptionPlan` | object | Active plan details, or `{}` when no plan is active |
| `subscriptionPlan.name` | string | Plan name, e.g. `pro`, `max` |
| `subscriptionPlan.duration` | string | Billing cycle, e.g. `monthly`, `yearly` |
| `subscriptionPlan.platform` | string | Platform the plan was purchased on |
| `freeUsages` | object | Free-quota balances keyed by resource key (see below) |
Each `freeUsages` entry has the following shape:
| Field | Type | Description |
| -------------- | ------- | --------------------------------------------------- |
| `remaining` | integer | Free generations left for this resource |
| `resourceType` | string | Resource category, e.g. `image` |
| `resourceKey` | string | The model/resource identifier (matches the map key) |
| `unit` | string | Unit of the quota, e.g. `generation` |
API key calls draw down `freeUsages` before any credits are spent.
Free Quota (freeUsages) [#free-quota-freeusages]
API key calls consume the same account-level free-quota balance shown here as the web and Labnana apps. Your account can earn free quota through sign-up, invites, and check-ins; calling the API does not grant a separate allowance.
| Resource key | Model | Sizes | Notes |
| -------------------------------- | ---------------------- | ---------------- | -------------------------------------------------------------- |
| `gemini-3-pro-image-relax-1k-2k` | NanoBanana Pro (relax) | `1K` / `2K` only | The headline free benefit. `4K` never draws from this balance. |
| `wan2.7-image` | Wan 2.7 | `1K` / `2K` only | Bonus free quota. |
| `gpt-image-2` | GPT-Image-2 | `1K` / `2K` only | Bonus free quota. |
> When `freeUsages[].remaining > 0`, a matching `1K`/`2K` generation through your API key spends the free quota instead of credits. Once it reaches `0`, the same request falls back to ordinary credit billing. `4K` always uses credits.
> NanoBanana Pro free quota can keep refilling through sign-up, invites, and
> check-ins — it does **not** mean unlimited API calls. The balance is finite at
> any moment, and how a Pro relax call runs depends on your account type (see
> [Image Generation → NanoBanana Pro Free
> Quota](/docs/en/openapi/api-reference/image-generation#nanobanana-pro-free-quota)).
618 Campaign (Pro / Max monthly credits) [#618-campaign-pro--max-monthly-credits]
From **2026-06-18** through **2026-06-24** (Asia/Shanghai), active Pro and Max subscribers receive **+50% monthly credits** for their eligible membership cycle. Both monthly and annual billing participate; a Max subscriber's bonus is based on Max's own monthly credit amount.
> The 618 bonus is a one-week boost to your **monthly credits**
> (`usageTotalMonthlyCredits` / `usageAvailableMonthlyCredits`). It is not a
> permanent plan upgrade, not a NanoBanana Pro free-quota (`freeUsages`)
> allowance, and not an upfront annual lump sum. The bonus resets with your
> current membership month, the same as ordinary monthly credits.
# Voice Cloning (/docs/en/openapi/api-reference/voice-clone)
The Voice Cloning API turns a short recording into a **reusable private voice**. Upload reference audio, poll until cloning finishes, confirm the result, and you get a `speakerId` that works on `/v1/speech`, `/v1/tts` and `/v1/audio/speech` like any other voice. Cloned voices belong to the account behind your API key and show up in `GET /v1/speakers/list`.
All endpoints live under `https://api.marswave.ai/openapi/v1/voice-clone` and authenticate with `Authorization: Bearer $LISTENHUB_API_KEY`.
> Cloning a voice requires the consent of the person being cloned. Every create request must carry `consentConfirmed=true`, which is your declaration that you hold that consent — the request is rejected without it, and the declaration is stored with the task. You remain responsible for obtaining and honoring that consent.
> Every response is wrapped in `{ "code": 0, "message": "", "data": { ... } }`. A non-zero `code` means an error — see [Error Handling](/docs/en/openapi/errors). The examples below read fields from `data`.
Limits and Cost [#limits-and-cost]
| Item | Value |
| ----------------- | ---------------------------------------------------------------------- |
| Reference audio | 1–6 files, single file ≤5MB, ≤20MB total |
| Languages | `en`, `zh`, `ja`, `es`, `pt`, `fr`, `de`, `tr`, `ko`, `it`, `th`, `vi` |
| Rate limit | 5 create requests per minute, per user |
| Plan | Paid plans only — a free-tier confirmation returns `NEED_UPGRADE` |
| Confirmations | Free within your plan's per-period quota, then **300 credits** each |
| Stored voices | Capped per plan (`maxSpeakers`); deleting a voice frees a slot |
| Unconfirmed tasks | Expire after 7 days — confirm the voice to keep it |
Beyond the quota, a confirmation only charges when you pass `useCredits=true`. Without it the request returns `NEED_CREDIT` and nothing is charged.
Two Ways to Clone [#two-ways-to-clone]
**Two-step (default)** — upload, listen to the preview, then decide:
1. `POST /v1/voice-clone/clone` returns a `taskId`.
2. Poll `GET /v1/voice-clone/clone/{taskId}` until `status` is `completed`; the response carries `demoAudioUrl`, a preview of the temporary voice.
3. `POST /v1/voice-clone/confirm` with a name and gender turns the task into a permanent private voice and returns its `speakerId`.
**One-shot** — set `autoConfirm=true` (plus `name` and `gender`) on the create call. The poll that first sees cloning finish also confirms the voice and returns `speakerId` in that same response. No second request.
> With `autoConfirm=true`, the polling request is what charges credits. Repeated or concurrent polls never double-charge — confirmation is guarded by an atomic lock, and a second attempt is rejected as already confirmed.
Reading the Poll Response [#reading-the-poll-response]
`GET /v1/voice-clone/clone/{taskId}` has three terminal shapes. Check them in this order:
| Outcome | How to detect | What you get |
| --------------------- | ---------------------------------------- | ------------------------------------------------------- |
| Cloning failed | `status: "failed"` | `errorCode` and `errorMessage` |
| Cloned, not confirmed | `status: "completed"` and no `speakerId` | `demoAudioUrl`; `confirmError` when auto-confirm failed |
| Confirmed | `speakerId` present | `speakerId`, ready for the speech endpoints |
The middle row is the one that is easy to miss with `autoConfirm=true`: cloning succeeded but saving the voice did not — out of credits, quota full, or the voice limit reached. `confirmError` says which. The clone is still there; fix the cause and call `POST /v1/voice-clone/confirm` explicitly.
| Status | Meaning |
| ------------ | ---------------------------------------------------------- |
| `pending` | Task created, waiting to be processed |
| `processing` | Cloning in progress |
| `completed` | Cloning finished — preview available, may not be confirmed |
| `failed` | Cloning failed; `errorMessage` explains why |
Retrying [#retrying]
| Status | When | What to do |
| ------ | -------------------------------------------------------------------------------------------- | ------------------------------------------------ |
| `429` | Another confirmation for the same account is in flight, or you exceeded 5 creates per minute | Wait for `Retry-After` (2s by default) and retry |
| `503` | The confirmation dependency is temporarily unavailable | Wait for `Retry-After` (5s by default) and retry |
Both are safe to retry — neither charges credits.
Create a Clone Task [#create-a-clone-task]
`POST /v1/voice-clone/clone`
Sends `multipart/form-data`, not JSON. Repeat the `audioFiles` field once per file.
**cURL:**
```bash
# Two-step
curl -X POST "https://api.marswave.ai/openapi/v1/voice-clone/clone" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-F "audioFiles=@reference.mp3" \
-F "language=en" \
-F "consentConfirmed=true"
# One-shot: clone and confirm in the same flow
curl -X POST "https://api.marswave.ai/openapi/v1/voice-clone/clone" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-F "audioFiles=@part-1.mp3" \
-F "audioFiles=@part-2.mp3" \
-F "language=ja" \
-F "consentConfirmed=true" \
-F "autoConfirm=true" \
-F "name=My API Voice" \
-F "gender=female" \
-F "useCredits=true"
```
**JavaScript:**
```javascript
import { readFile } from 'node:fs/promises'
const form = new FormData()
form.append('audioFiles', new Blob([await readFile('reference.mp3')]), 'reference.mp3')
form.append('language', 'en')
form.append('consentConfirmed', 'true')
const response = await fetch('https://api.marswave.ai/openapi/v1/voice-clone/clone', {
method: 'POST',
headers: { Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}` },
body: form,
})
const { data } = await response.json()
console.log('Task:', data.taskId)
```
**Python:**
```python
import os
import requests
with open('reference.mp3', 'rb') as audio:
response = requests.post(
'https://api.marswave.ai/openapi/v1/voice-clone/clone',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
files=[('audioFiles', ('reference.mp3', audio, 'audio/mpeg'))],
data={'language': 'en', 'consentConfirmed': 'true'},
)
data = response.json()['data']
print('Task:', data['taskId'])
```
**Request parameters**:
| Field | Type | Required | Description |
| ------------------ | ------- | ------------------ | ---------------------------------------------------------------------------------- |
| `audioFiles` | file | Yes | 1–6 reference audio files. Repeat the field for multiple files |
| `language` | string | Yes | One of `en`, `zh`, `ja`, `es`, `pt`, `fr`, `de`, `tr`, `ko`, `it`, `th`, or `vi` |
| `consentConfirmed` | boolean | Yes | Must be `true` — your declaration that you hold the cloned person's consent |
| `mode` | string | No | `upload` (default and only accepted value) |
| `autoConfirm` | boolean | No | Confirm the voice inside the poll that finds cloning finished. Defaults to `false` |
| `name` | string | With `autoConfirm` | Voice name, up to 50 characters |
| `gender` | string | With `autoConfirm` | `male`, `female`, or `other` |
| `useCredits` | boolean | No | Authorizes the 300-credit charge once your quota is used up. Defaults to `false` |
Returns:
```json
{
"code": 0,
"message": "",
"data": {
"taskId": "6915bde9cca4d3c8ecb3eaf5",
"status": "pending"
}
}
```
Poll a Clone Task [#poll-a-clone-task]
`GET /v1/voice-clone/clone/{taskId}`
**cURL:**
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/voice-clone/clone/{taskId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**JavaScript:**
```javascript
const response = await fetch(
`https://api.marswave.ai/openapi/v1/voice-clone/clone/${taskId}`,
{ headers: { Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}` } },
)
const { data } = await response.json()
if (data.status === 'failed') throw new Error(data.errorMessage)
if (data.speakerId) console.log('Ready to speak with:', data.speakerId)
else if (data.confirmError) console.warn('Cloned but not saved:', data.confirmError)
else if (data.demoAudioUrl) console.log('Preview:', data.demoAudioUrl)
```
**Python:**
```python
import os
import requests
response = requests.get(
f'https://api.marswave.ai/openapi/v1/voice-clone/clone/{task_id}',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
)
data = response.json()['data']
if data['status'] == 'failed':
raise RuntimeError(data['errorMessage'])
if data.get('speakerId'):
print('Ready to speak with:', data['speakerId'])
elif data.get('confirmError'):
print('Cloned but not saved:', data['confirmError'])
elif data.get('demoAudioUrl'):
print('Preview:', data['demoAudioUrl'])
```
Cloned, waiting for confirmation:
```json
{
"code": 0,
"message": "",
"data": {
"status": "completed",
"demoAudioUrl": "https://assets.listenhub.app/voice-clone/demo-6915bde9.mp3"
}
}
```
Confirmed:
```json
{
"code": 0,
"message": "",
"data": {
"status": "completed",
"demoAudioUrl": "https://assets.listenhub.app/voice-clone/demo-6915bde9.mp3",
"speakerId": "voice-clone-6915bde9cca4d3c8ecb3eaf5"
}
}
```
Confirm a Clone Task [#confirm-a-clone-task]
`POST /v1/voice-clone/confirm`
Turns a completed task into a permanent private voice. Repeating it for the same task returns `ALREADY_CONFIRMED` and charges nothing.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/voice-clone/confirm" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"taskId": "6915bde9cca4d3c8ecb3eaf5",
"name": "My API Voice",
"gender": "female",
"useCredits": true
}'
```
**JavaScript:**
```javascript
const response = await fetch('https://api.marswave.ai/openapi/v1/voice-clone/confirm', {
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({ taskId, name: 'My API Voice', gender: 'female', useCredits: true }),
})
const { data } = await response.json()
console.log('Speaker:', data.speakerId)
```
| Field | Type | Required | Description |
| ------------ | ------- | -------- | ----------------------------------------------------------------------- |
| `taskId` | string | Yes | A completed clone task |
| `name` | string | Yes | Voice name, up to 50 characters |
| `gender` | string | Yes | `male`, `female`, or `other` |
| `useCredits` | boolean | No | Authorizes the 300-credit charge beyond your quota. Defaults to `false` |
Returns:
```json
{
"code": 0,
"message": "",
"data": { "speakerId": "voice-clone-6915bde9cca4d3c8ecb3eaf5" }
}
```
Speak with a Cloned Voice [#speak-with-a-cloned-voice]
Pass the `speakerId` wherever a voice is expected:
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/speech" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"scripts": [
{
"content": "This sentence is spoken by my own cloned voice.",
"speakerId": "voice-clone-6915bde9cca4d3c8ecb3eaf5"
}
]
}'
```
List Private Voices [#list-private-voices]
`GET /v1/voice-clone/speakers`
```bash
curl -X GET "https://api.marswave.ai/openapi/v1/voice-clone/speakers" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
```json
{
"code": 0,
"message": "",
"data": {
"speakers": [
{
"id": "6915c0a2cca4d3c8ecb3eb01",
"name": "My API Voice",
"speakerInnerId": "voice-clone-6915bde9cca4d3c8ecb3eaf5",
"language": "en",
"gender": "female",
"demoAudioUrl": "https://assets.listenhub.app/voice-clone/demo-6915bde9.mp3",
"createdAt": "2026-07-30T09:10:11.000Z"
}
],
"quota": 2,
"isLimitReached": false,
"maxSpeakers": 2,
"remainingConfirmations": 1
}
}
```
| Field | Description |
| --------------------------- | --------------------------------------------------- |
| `speakers[].speakerInnerId` | The ID to pass to the speech and TTS endpoints |
| `quota` | Confirmations included per subscription period |
| `remainingConfirmations` | Confirmations left in the current period |
| `maxSpeakers` | How many private voices your plan may keep at once |
| `isLimitReached` | `true` once this period's confirmations are used up |
Get, Rename, or Delete a Voice [#get-rename-or-delete-a-voice]
| Method | Path | Description |
| -------- | -------------------------------------- | ------------------------------------------------- |
| `GET` | `/v1/voice-clone/speakers/{speakerId}` | One private voice |
| `PUT` | `/v1/voice-clone/speakers/{speakerId}` | Update `name` and/or `gender` (send at least one) |
| `DELETE` | `/v1/voice-clone/speakers/{speakerId}` | Delete the voice |
```bash
# Rename
curl -X PUT "https://api.marswave.ai/openapi/v1/voice-clone/speakers/{speakerId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{ "name": "Narrator (EN)" }'
# Delete — frees one slot against maxSpeakers
curl -X DELETE "https://api.marswave.ai/openapi/v1/voice-clone/speakers/{speakerId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
`GET` and `PUT` return the voice:
```json
{
"code": 0,
"message": "",
"data": {
"id": "6915c0a2cca4d3c8ecb3eb01",
"speakerInnerId": "voice-clone-6915bde9cca4d3c8ecb3eaf5",
"name": "Narrator (EN)",
"language": "en",
"gender": "female",
"demoAudioUrl": "https://assets.listenhub.app/voice-clone/demo-6915bde9.mp3",
"createdAt": "2026-07-30T09:10:11.000Z",
"updatedAt": "2026-07-30T10:02:44.000Z"
}
}
```
`DELETE` returns `{ "speakerId": "..." }`. Deleting frees a slot; the confirmations already spent this period are not returned.
Errors [#errors]
| Error | Meaning |
| ------------------------ | ----------------------------------------------------------------------- |
| `NEED_UPGRADE` | Voice cloning requires a paid plan |
| `NEED_CREDIT` | Quota used up and `useCredits` was not set — nothing was charged |
| `SPEAKER_LIMIT_REACHED` | You already hold the maximum number of private voices; delete one first |
| `ALREADY_CONFIRMED` | This task was already confirmed; no second charge |
| `AUDIO_DURATION_INVALID` | The reference audio is too short or too long |
| `NO_VALID_SPEECH` | No speech detected in the reference audio |
| `TASK_FAILED` | Cloning failed; `errorMessage` carries the detail |
See [Error Handling](/docs/en/openapi/errors) for the full error envelope.
# HappyHorse (/docs/en/openapi/api-reference/ai-video/happyhorse)
HappyHorse runs on the shared video generation endpoint. For the endpoint, request flow, content items, polling, task listing, and error codes, see the [AI Video overview](/docs/en/openapi/api-reference/ai-video). This page covers only what is specific to HappyHorse.
Model [#model]
| Model | Best for | Rate limit |
| ------------ | -------------------------- | ---------- |
| `happyhorse` | HappyHorse model workflows | 5 RPM |
Pass `"model": "happyhorse"` in `POST /v1/video-generation/generate`.
Limits [#limits]
| Limit | HappyHorse |
| -------------------- | --------------------------------------------------------- |
| Resolution | `720p`, `1080p` (no `480p`) |
| Duration | 3-15s |
| Aspect ratios | `16:9`, `4:3`, `1:1`, `3:4`, `9:16`, `21:9`, `4:5`, `5:4` |
| `inputVideoDuration` | 3-60s (reference video input) |
> HappyHorse does not support `480p`. It does not support `last_frame` (no
> end-frame control) or `audio_url` (no reference-audio input). HappyHorse is the
> only family that adds the `4:5` and `5:4` aspect ratios, and it accepts a
> longer reference-video input window (3-60s) than Seedance (2-15s).
Example [#example]
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/video-generation/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "happyhorse",
"content": [
{ "type": "text", "text": "Restyle the subject as a polished product launch clip" },
{ "type": "video_url", "role": "reference_video", "video_url": { "url": "https://example.com/reference.mp4" } }
],
"resolution": "1080p",
"ratio": "4:5",
"duration": 6,
"inputVideoDuration": 8,
"audioSetting": "auto"
}'
```
See the [AI Video overview](/docs/en/openapi/api-reference/ai-video#request-parameters) for the full parameter list and the text-to-video / image-to-video request shapes.
# AI Video (/docs/en/openapi/api-reference/ai-video)
AI Video creates short videos asynchronously. Submit a generation request, then poll the task until it reaches `success` or `failed`.
Seedance, Wan 3.0, MiniMax H3, and HappyHorse share one endpoint — `POST /v1/video-generation/generate` — and you pick a model with the `model` field. PixVerse runs on its own endpoint with a different request shape. Tasks from all five families are read back through the same task, list, and detail endpoints.
> All endpoints on this page use the OpenAPI base URL
> `https://api.marswave.ai/openapi` and authenticate with your API key via the
> `Authorization: Bearer $LISTENHUB_API_KEY` header. Create keys at
> [listenhub.ai/settings/api-keys](https://listenhub.ai/settings/api-keys).
Choose a model [#choose-a-model]
Seven models span five families. Use this table to pick one, then open the model's page for its exact limits and pricing notes.
| Model | Family | Generate endpoint | Best for | Resolution | Duration |
| ------------------------------------ | ---------- | ---------------------------------------- | -------------------------------------------------------------------------------------- | ------------------------------- | -------- |
| `doubao-seedance-2-fast` *(default)* | Seedance | `/v1/video-generation/generate` | Fast text / image / video generation | `480p`, `720p` | 4-15s |
| `doubao-seedance-2-pro` | Seedance | `/v1/video-generation/generate` | Higher-quality Seedance generation, up to `1080p` | `480p`, `720p`, `1080p` | 4-15s |
| `wan3.0-video` | Wan 3.0 | `/v1/video-generation/generate` | Clips up to 30s with natively generated audio | `480p`, `720p`, `1080p` | 2-30s |
| `wan3.0-video-prime` | Wan 3.0 | `/v1/video-generation/generate` | The same capabilities at a markedly faster turnaround | `480p`, `720p`, `1080p` | 2-30s |
| `MiniMax-H3` | MiniMax | `/v1/video-generation/generate` | A native sound track, a closing frame on its own, reference audio | `768p`, `2k` | 4-15s |
| `happyhorse` | HappyHorse | `/v1/video-generation/generate` | Reference-video editing, portrait ratios, longer reference clips | `720p`, `1080p` | 3-15s |
| `pixverse` | PixVerse | `/v1/video-generation/pixverse/generate` | Nine capability modes: transitions, fusion, restyle, mimic, lip sync, marketing agents | `360p`, `540p`, `720p`, `1080p` | 1-60s |
`doubao-seedance-2-fast` is the default when `model` is omitted on the shared endpoint. PixVerse has no `model` default of its own on the shared endpoint — you reach it through its dedicated `pixverse/generate` path and select a version (`pixverse`, `v6`, `v5`, `v4.5`) with that endpoint's own `model` field.
| Model | Aspect ratios | Rate limit |
| ------------------------ | --------------------------------------------------------- | ---------- |
| `doubao-seedance-2-fast` | `16:9`, `4:3`, `1:1`, `3:4`, `9:16`, `21:9` | 5 RPM |
| `doubao-seedance-2-pro` | `16:9`, `4:3`, `1:1`, `3:4`, `9:16`, `21:9` | 5 RPM |
| `wan3.0-video` | `16:9`, `4:3`, `1:1`, `3:4`, `9:16` | 5 RPM |
| `wan3.0-video-prime` | `16:9`, `4:3`, `1:1`, `3:4`, `9:16` | 5 RPM |
| `MiniMax-H3` | `16:9`, `4:3`, `1:1`, `3:4`, `9:16`, `21:9` | 5 RPM |
| `happyhorse` | `16:9`, `4:3`, `1:1`, `3:4`, `9:16`, `21:9`, `4:5`, `5:4` | 5 RPM |
| `pixverse` | `9:16`, `16:9`, `1:1`, `4:3`, `3:4` | 5 RPM |
> Model limits differ. `doubao-seedance-2-fast` does not support `1080p`.
> Seedance models do not support `4:5` or `5:4`. Wan 3.0 supports neither those
> two nor `21:9`, and takes no reference-video or reference-audio input.
> `MiniMax-H3` is the only model that takes `768p` and `2k`, and the only one
> that takes neither `480p`, `720p`, nor `1080p`; it rejects `4:5` and `5:4`,
> and ignores `ratio` entirely for image-to-video. `happyhorse` does not
> support `480p`, `last_frame`, or `audio_url`. Requests that combine an
> unsupported model, ratio, resolution, or duration return `400`.
- **Seedance** -- doubao-seedance-2-pro and doubao-seedance-2-fast: limits and pricing notes. [/docs/en/openapi/api-reference/ai-video/seedance](/docs/en/openapi/api-reference/ai-video/seedance)
- **Wan 3.0** -- wan3.0-video and wan3.0-video-prime: 30-second clips, native audio, and per-tier pricing. [/docs/en/openapi/api-reference/ai-video/wan3](/docs/en/openapi/api-reference/ai-video/wan3)
- **MiniMax H3** -- MiniMax-H3: 768p and 2k, a native sound track, and a closing frame on its own. [/docs/en/openapi/api-reference/ai-video/minimax-h3](/docs/en/openapi/api-reference/ai-video/minimax-h3)
- **HappyHorse** -- happyhorse: portrait ratios, reference-video editing, and longer input windows. [/docs/en/openapi/api-reference/ai-video/happyhorse](/docs/en/openapi/api-reference/ai-video/happyhorse)
- **PixVerse** -- Nine capability modes on a dedicated endpoint, from lip sync to marketing agents. [/docs/en/openapi/api-reference/ai-video/pixverse](/docs/en/openapi/api-reference/ai-video/pixverse)
Workflow [#workflow]
The shared endpoint covers Seedance, Wan 3.0, MiniMax H3, and HappyHorse. PixVerse follows the same three-step flow on its own generate and estimate paths; see the [PixVerse](/docs/en/openapi/api-reference/ai-video/pixverse) page.
1. Estimate Credits [#estimate-credits]
Call `POST /v1/video-generation/estimate-credits` (or `POST /v1/video-generation/pixverse/estimate-credits` for PixVerse) before generation when you need to show a cost confirmation.
2. Create a Task [#create-a-task]
Call `POST /v1/video-generation/generate` (or `POST /v1/video-generation/pixverse/generate`). The response returns a `taskId` and `episodeId`.
3. Poll for Result [#poll-for-result]
Poll `GET /v1/video-generation/tasks/{taskId}` until `status` is `success` or `failed`. This endpoint is shared across all model families.
Content Items [#content-items]
The `content` array accepts 1-16 items. It can include at most one text prompt, up to nine images, up to three videos, and up to three audio files; `MiniMax-H3` caps images at five. This array applies to the shared Seedance / Wan 3.0 / MiniMax H3 / HappyHorse endpoint; PixVerse uses top-level `images`, `videos`, and `audios` fields instead.
| Type | Required fields | Role | Notes |
| ----------- | --------------- | ---------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------- |
| `text` | `text` | None | Max 2500 characters. Seedance models accept up to 500 characters. |
| `image_url` | `image_url.url` | `first_frame`, `last_frame`, `reference_image` | `last_frame` requires a `first_frame`, except on `MiniMax-H3`, which takes one on its own. Frame roles cannot be mixed with reference roles. |
| `video_url` | `video_url.url` | `reference_video` | Requires `inputVideoDuration`. Seedance and MiniMax H3 accept 2-15s input; HappyHorse accepts 3-60s input; Wan 3.0 does not accept video input. |
| `audio_url` | `audio_url.url` | `reference_audio` | Requires at least one image or video item. Not supported by `happyhorse` or Wan 3.0. |
> Use frame roles (`first_frame`, optionally `last_frame`) for image-to-video.
> Use reference roles (`reference_image`, `reference_video`, `reference_audio`)
> for multimodal reference generation. Do not mix frame roles and reference
> roles in one request.
Create Video Task [#create-video-task]
`POST /v1/video-generation/generate`
Create an asynchronous video generation task on the shared Seedance / Wan 3.0 / MiniMax H3 / HappyHorse endpoint. Credits are charged when the task is created and refunded automatically if generation fails. For PixVerse, use [`POST /v1/video-generation/pixverse/generate`](/docs/en/openapi/api-reference/ai-video/pixverse).
Text to Video [#text-to-video]
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/video-generation/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "doubao-seedance-2-fast",
"content": [
{
"type": "text",
"text": "A cinematic aerial shot of a quiet coastal city at sunrise"
}
],
"resolution": "720p",
"ratio": "16:9",
"duration": 5,
"generateAudio": true
}'
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/video-generation/generate',
{
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
model: 'doubao-seedance-2-fast',
content: [
{
type: 'text',
text: 'A cinematic aerial shot of a quiet coastal city at sunrise',
},
],
resolution: '720p',
ratio: '16:9',
duration: 5,
generateAudio: true,
}),
},
)
const data = await response.json()
console.log('Task ID:', data.data.taskId)
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/video-generation/generate',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'model': 'doubao-seedance-2-fast',
'content': [
{
'type': 'text',
'text': 'A cinematic aerial shot of a quiet coastal city at sunrise',
}
],
'resolution': '720p',
'ratio': '16:9',
'duration': 5,
'generateAudio': True,
},
)
data = response.json()
print('Task ID:', data['data']['taskId'])
```
**Response**:
```json
{
"code": 0,
"message": "",
"data": {
"taskId": "665f1d4e8b3a3f001234abcd",
"episodeId": "665f1d4e8b3a3f001234abce",
"status": "generating"
}
}
```
Image to Video [#image-to-video]
Use `first_frame` to start from one image. Add `last_frame` only when you want to control the ending frame.
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/video-generation/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "doubao-seedance-2-pro",
"content": [
{
"type": "text",
"text": "The camera slowly pushes in while mist moves through the scene"
},
{
"type": "image_url",
"role": "first_frame",
"image_url": {
"url": "https://example.com/start-frame.jpg"
}
}
],
"resolution": "1080p",
"ratio": "16:9",
"duration": 5
}'
```
Video Reference [#video-reference]
When `content` contains `video_url`, set `inputVideoDuration` to the reference video's duration in seconds.
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/video-generation/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "happyhorse",
"content": [
{
"type": "text",
"text": "Restyle the subject as a polished product launch clip"
},
{
"type": "video_url",
"role": "reference_video",
"video_url": {
"url": "https://example.com/reference.mp4"
}
},
{
"type": "image_url",
"role": "reference_image",
"image_url": {
"url": "https://example.com/style-reference.jpg"
}
}
],
"resolution": "720p",
"ratio": "9:16",
"duration": 5,
"inputVideoDuration": 8,
"audioSetting": "auto"
}'
```
Request Parameters [#request-parameters]
| Parameter | Type | Required | Default | Description |
| -------------------- | ------- | -------- | ------------------------ | ---------------------------------------------------------------------------------------------------------------------------- |
| `model` | string | No | `doubao-seedance-2-fast` | `doubao-seedance-2-pro`, `doubao-seedance-2-fast`, `wan3.0-video`, `wan3.0-video-prime`, `MiniMax-H3`, or `happyhorse`. |
| `content` | array | Yes | - | Input items. See [Content Items](#content-items). |
| `resolution` | string | No | `720p` | `480p`, `720p`, `1080p`, or — on `MiniMax-H3` only — `768p` or `2k`, subject to model limits. |
| `ratio` | string | No | `16:9` | `16:9`, `4:3`, `1:1`, `3:4`, `9:16`, `21:9`, `4:5`, or `5:4`, subject to model limits. |
| `duration` | integer | No | `5` | Output duration in seconds. Seedance and MiniMax H3 require 4-15; Wan 3.0 accepts 2-30; HappyHorse accepts 3-15. |
| `generateAudio` | boolean | No | `true` | Whether to generate audio with the video. Ignored by `MiniMax-H3`, whose output always has a sound track. |
| `seed` | integer | No | `-1` | Random seed, `-1` to `4294967295`. Use `-1` for random generation. Ignored by `MiniMax-H3`. |
| `inputVideoDuration` | integer | No | `0` | Required when using `video_url`. Seedance and MiniMax H3 accept 2-15; HappyHorse accepts 3-60; Wan 3.0 takes no video input. |
| `audioSetting` | string | No | `auto` | For video-edit workflows. `auto` generates audio; `origin` keeps original video audio. |
> Resolution, ratio, duration, and `inputVideoDuration` limits vary by model.
> See [Seedance](/docs/en/openapi/api-reference/ai-video/seedance),
> [Wan 3.0](/docs/en/openapi/api-reference/ai-video/wan3),
> [MiniMax H3](/docs/en/openapi/api-reference/ai-video/minimax-h3), and
> [HappyHorse](/docs/en/openapi/api-reference/ai-video/happyhorse) for the
> per-model rules.
Get Task [#get-task]
`GET /v1/video-generation/tasks/{taskId}`
Poll the task detail endpoint until the task reaches a terminal state. This endpoint returns tasks from every model family, including PixVerse.
```bash
curl "https://api.marswave.ai/openapi/v1/video-generation/tasks/{taskId}" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
**Task statuses**:
| Status | Meaning |
| ------------ | ---------------------------------------------------------------------- |
| `pending` | Task created and waiting to be submitted. |
| `generating` | Provider generation is in progress. |
| `uploading` | Provider output is ready and ListenHub is storing it. |
| `success` | Video is ready. Use `videoUrl` for the stored output. |
| `failed` | Generation failed. Credits are refunded automatically when applicable. |
**Response**:
```json
{
"code": 0,
"message": "",
"data": {
"id": "665f1d4e8b3a3f001234abcd",
"taskId": "665f1d4e8b3a3f001234abcd",
"episodeId": "665f1d4e8b3a3f001234abce",
"status": "success",
"model": "doubao-seedance-2-fast",
"params": {
"content": [
{
"type": "text",
"text": "A cinematic aerial shot of a quiet coastal city at sunrise"
}
],
"resolution": "720p",
"ratio": "16:9",
"duration": 5,
"generateAudio": true,
"seed": -1
},
"videoUrl": "https://assets.listenhub.app/video-generation/output.mp4",
"coverUrl": "https://assets.listenhub.app/video-generation/cover.jpg",
"providerVideoUrl": "https://provider.example/video.mp4",
"duration": 5,
"resolution": "720p",
"ratio": "16:9",
"seed": 123456,
"creditCharged": 12,
"enabledShare": false,
"createdAt": 1700000000000,
"updatedAt": 1700000300000
}
}
```
List Tasks [#list-tasks]
`GET /v1/video-generation/tasks`
List the current API user's video generation tasks in reverse chronological order. Tasks from all model families appear in the same list.
```bash
curl "https://api.marswave.ai/openapi/v1/video-generation/tasks?page=1&pageSize=20&status=success" \
-H "Authorization: Bearer $LISTENHUB_API_KEY"
```
Query Parameters [#query-parameters]
| Parameter | Type | Required | Default | Description |
| ---------- | ------- | -------- | ------- | ------------------------------------------------------------------------------ |
| `page` | integer | No | `1` | Page number. |
| `pageSize` | integer | No | `20` | Items per page, max 100. |
| `status` | string | No | - | Optional filter: `pending`, `generating`, `uploading`, `success`, or `failed`. |
**Response**:
```json
{
"code": 0,
"message": "",
"data": {
"items": [
{
"id": "665f1d4e8b3a3f001234abcd",
"episodeId": "665f1d4e8b3a3f001234abce",
"status": "success",
"model": "doubao-seedance-2-fast",
"title": "A cinematic aerial shot of a quiet coastal city at sunrise",
"prompt": "A cinematic aerial shot of a quiet coastal city at sunrise",
"params": {
"content": [],
"resolution": "720p",
"ratio": "16:9",
"duration": 5,
"generateAudio": true,
"seed": -1
},
"videoUrl": "https://assets.listenhub.app/video-generation/output.mp4",
"coverUrl": "https://assets.listenhub.app/video-generation/cover.jpg",
"providerVideoUrl": "https://provider.example/video.mp4",
"seed": 123456,
"creditCharged": 12,
"createdAt": 1700000000000
}
],
"page": 1,
"pageSize": 20,
"total": 1
}
}
```
Estimate Credits [#estimate-credits-1]
`POST /v1/video-generation/estimate-credits`
Estimate the credit cost before creating a task on the shared Seedance / Wan 3.0 / MiniMax H3 / HappyHorse endpoint. PixVerse has its own estimate at [`POST /v1/video-generation/pixverse/estimate-credits`](/docs/en/openapi/api-reference/ai-video/pixverse#estimate-credits). Credit cost is never fixed — always call the matching estimate endpoint to read the exact value for your parameters.
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/video-generation/estimate-credits" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "doubao-seedance-2-fast",
"resolution": "720p",
"duration": 5,
"hasVideoInput": false,
"ratio": "16:9"
}'
```
Request Parameters [#request-parameters-1]
| Parameter | Type | Required | Default | Description |
| -------------------- | ------- | -------- | ------- | ----------------------------------------------------------------------------------------------------------------------- |
| `model` | string | Yes | - | `doubao-seedance-2-pro`, `doubao-seedance-2-fast`, `wan3.0-video`, `wan3.0-video-prime`, `MiniMax-H3`, or `happyhorse`. |
| `resolution` | string | Yes | - | `480p`, `720p`, `1080p`, `768p`, or `2k`, subject to model limits. |
| `duration` | integer | Yes | - | Output duration in seconds. |
| `hasVideoInput` | boolean | No | `false` | Set to `true` when the generation request includes `video_url`. |
| `inputVideoDuration` | integer | No | `0` | Required when `hasVideoInput` is `true`. |
| `ratio` | string | No | `16:9` | Aspect ratio. |
**Response**:
```json
{
"code": 0,
"message": "",
"data": {
"tokens": 155520,
"credits": 12
}
}
```
Errors [#errors]
| HTTP status | Meaning |
| ----------- | ------------------------------------------------------------------------------------------------------- |
| `400` | Invalid parameters, unsupported model/ratio/resolution combination, or missing required media duration. |
| `402` | Not enough credits. |
| `403` | The task exists but does not belong to the current API user. |
| `404` | Task not found. |
| `429` | Rate limit exceeded (5 RPM per user on the generate endpoints). |
PixVerse returns its own numeric `code` values alongside these HTTP statuses — see [PixVerse error codes](/docs/en/openapi/api-reference/ai-video/pixverse#error-codes).
# MiniMax H3 (/docs/en/openapi/api-reference/ai-video/minimax-h3)
MiniMax H3 runs on the shared video generation endpoint. For the endpoint, request flow, content items, polling, task listing, and error codes, see the [AI Video overview](/docs/en/openapi/api-reference/ai-video). This page covers only what is specific to MiniMax H3.
Models [#models]
| Model | Best for | Rate limit |
| ------------ | ------------------------------------------------------------------ | ---------- |
| `MiniMax-H3` | Clips with a native sound track, closing-frame and audio reference | 5 RPM |
Pass the model in the `model` field of `POST /v1/video-generation/generate`. The literal is case-sensitive: `MiniMax-H3`.
Limits [#limits]
| Limit | MiniMax H3 |
| -------------------- | ------------------------------------------- |
| Resolution | `768p`, `2k` |
| Duration | 4-15s, whole seconds only |
| Aspect ratios | `16:9`, `4:3`, `1:1`, `3:4`, `9:16`, `21:9` |
| Prompt length | up to 2500 characters, required |
| Reference images | up to 5 per request |
| Reference videos | up to 3 per request |
| Reference audio | up to 3 per request |
| `inputVideoDuration` | 2-15s, required with a reference video |
`768p` sizes the short edge to 768 pixels — 1344×768 at `16:9`. `2k` sizes the long edge to 2560 pixels. Both are exclusive to MiniMax H3: every other model on the shared endpoint rejects them, and MiniMax H3 in turn rejects `480p`, `720p`, and `1080p`.
MiniMax H3 accepts `first_frame`, `last_frame`, or both. It is the only model on this endpoint that takes a `last_frame` on its own — everywhere else a closing frame is only valid alongside an opening one, so a "land on this shot" request needs no filler first frame here. Frame roles and reference roles (`reference_image`, `reference_video`, `reference_audio`) cannot be combined in one request.
In image-to-video the provider derives the aspect ratio from the input image, so `ratio` is accepted and then ignored. Set the framing by cropping the image you send rather than by the parameter.
> MiniMax H3 takes `768p` and `2k` only — `480p`, `720p`, and `1080p` return
> `400`, and no other model accepts `768p` or `2k`. Duration is 4-15s. The
> `4:5` and `5:4` aspect ratios are rejected, and `ratio` is ignored entirely
> for image-to-video. `seed` and `generateAudio` are accepted for
> compatibility but have no effect: generation is not seed-reproducible, and
> the output always carries an audio track. `reference_image` is capped at 5
> per request, not the 9 the shared endpoint allows elsewhere.
Pricing [#pricing]
Credits scale with resolution and duration. The total is rounded up to a whole credit.
| Resolution | Credits / second | 4s | 10s | 15s |
| ---------- | ---------------- | -- | --- | --- |
| `768p` | 9.3075 | 38 | 94 | 140 |
| `2k` | 15.1247 | 61 | 152 | 227 |
Call `POST /v1/video-generation/estimate-credits` with the MiniMax H3 `model`, `resolution`, and `duration` for the exact cost before generating. Credits are charged on task creation and refunded automatically on failure.
Example [#example]
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/video-generation/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "MiniMax-H3",
"content": [
{ "type": "text", "text": "The camera pushes in slowly as the city lights come up" },
{ "type": "image_url", "role": "first_frame", "image_url": { "url": "https://example.com/open.jpg" } },
{ "type": "image_url", "role": "last_frame", "image_url": { "url": "https://example.com/close.jpg" } }
],
"resolution": "768p",
"ratio": "16:9",
"duration": 8
}'
```
See the [AI Video overview](/docs/en/openapi/api-reference/ai-video#request-parameters) for the full parameter list and the text-to-video / image-to-video request shapes.
# PixVerse Video (/docs/en/openapi/api-reference/ai-video/pixverse)
PixVerse generates short videos asynchronously across nine capabilities. Submit a generation request, then poll the task until it reaches `success` or `failed`. Tasks created here are queried through the same [AI Video](/docs/en/openapi/api-reference/ai-video) task, list, share, and delete endpoints.
> All endpoints on this page use the OpenAPI base URL
> `https://api.marswave.ai/openapi` and authenticate with your API key via the
> `Authorization: Bearer $LISTENHUB_API_KEY` header.
Endpoints [#endpoints]
| Method | Path | Purpose |
| ------ | ------------------------------------------------ | ----------------------------------- |
| `POST` | `/v1/video-generation/pixverse/generate` | Create a PixVerse generation task. |
| `POST` | `/v1/video-generation/pixverse/estimate-credits` | Estimate credits before generation. |
> Region routing follows `language`. The default `en` uses the PixVerse
> international service; `zh` uses the China service. PixVerse provider keys,
> internal media IDs, trace IDs, and raw provider responses are never returned to
> the client.
Capabilities [#capabilities]
`capability` is required. It selects the generation mode and decides which assets and nested fields are needed.
| Capability | What it does | Required input |
| ------------------ | ------------------------------------------- | ------------------------------------------------------------------------------ |
| `text_to_video` | Generate from a text prompt only | `prompt`; no assets |
| `image_to_video` | Animate from one or more images | `prompt` + 1-10 `images` |
| `transition` | Transition between two images | exactly 2 `images` + `prompt` |
| `multi_transition` | Multi-clip transition sequence | `pixverse.multiTransition` (2-7 clips); no top-level assets |
| `fusion` | Compose subjects/backgrounds by reference | `pixverse.imageReferences` (1-8) + `prompt` containing each `@refName` |
| `restyle` | Restyle a prior PixVerse video | `sourceTaskId` (or `pixverse.sourceVideoId`) + `pixverse.restyleId`; no assets |
| `mimic` | Apply a motion video to a subject image | exactly 1 `image` + 1 `video` |
| `lip_sync` | Lip-sync a video to audio or TTS | 1 `video` (or `sourceTaskId`) + 1 `audio` **or** `pixverse.tts` |
| `agent` | Marketing agent (`ad_master` / `promo_mix`) | `pixverse.agentType` + product images |
Request Parameters [#request-parameters]
`POST /v1/video-generation/pixverse/generate`
| Parameter | Type | Required | Default | Description |
| -------------- | ------- | -------- | ---------- | ------------------------------------------------------------------------------------------------------- |
| `capability` | string | Yes | - | One of the nine capabilities above. |
| `model` | string | No | `pixverse` | PixVerse model version: `pixverse`, `v6`, `v5`, or `v4.5`. |
| `language` | string | No | `en` | Service region: `en` (international) or `zh` (China). |
| `prompt` | string | No | - | Up to 2048 characters. Required for `text_to_video`, `image_to_video`, `transition`, `fusion`, `agent`. |
| `quality` | string | No | `720p` | `360p`, `540p`, `720p`, or `1080p`. `multi_transition` defaults to `360p`. |
| `aspectRatio` | string | No | `16:9` | `9:16`, `16:9`, `1:1`, `4:3`, or `3:4`. `agent` defaults to `9:16`. |
| `duration` | integer | No | `5` | Output seconds, 1-60. `agent` accepts only `20`, `30`, or `60` (default `30`). |
| `sourceTaskId` | string | No | - | A prior succeeded PixVerse task to reuse (restyle / lip\_sync source video). |
| `images` | array | No | `[]` | Up to 10 items, each `{ url, duration? }`. |
| `videos` | array | No | `[]` | Up to 2 items, each `{ url, duration? }`. |
| `audios` | array | No | `[]` | Up to 1 item, `{ url, duration? }`. |
| `pixverse` | object | No | `{}` | Capability-specific options. See [Nested `pixverse` Object](#nested-pixverse-object). |
Each asset's `url` is required; the optional `duration` is in seconds (0-180).
Nested pixverse Object [#nested-pixverse-object]
| Field | Type | Used by | Description |
| --------------------- | ------------- | -------------------- | ------------------------------------------------------------------------------------------------------------------------------------- |
| `agentType` | string | `agent` | `ad_master` or `promo_mix`. |
| `motionMode` | string | optional | Motion preset. |
| `cameraMovement` | string | optional | Camera movement preset. |
| `templateId` | string/number | optional | Template identifier. |
| `sourceVideoId` | string/number | `restyle`/`lip_sync` | Provider source video id (alternative to `sourceTaskId`). |
| `restyleId` | string/number | `restyle` | Required restyle style id. |
| `multiTransition` | array | `multi_transition` | 2-7 clips, each `{ imageUrl, duration (0-30), prompt }`. |
| `imageReferences` | array | `fusion` | 1-8 refs, each `{ type: subject\|background, imageUrl, refName }`. |
| `tts` | object | `lip_sync` | `{ speakerId, content }` to drive lip sync from synthesized speech. |
| `soundEffectSwitch` | boolean | optional | Enable generated sound effects. |
| `soundEffectContent` | string | optional | Sound-effect description. |
| `lipSyncTtsSwitch` | boolean | optional | Enable TTS-driven lip sync. |
| `lipSyncTtsSpeakerId` | string | optional | Speaker id for TTS lip sync. |
| `lipSyncTtsContent` | string | optional | Spoken text for TTS lip sync. |
| `brandSticker` | object | `agent` | `{ imageUrl, position }`; position is one of `up`, `down`, `left`, `right`, `upper_left`, `lower_left`, `upper_right`, `lower_right`. |
| `introOutroClip` | object | `agent` | `{ videoUrl, position }`; position is `start` or `end`. |
refName Format [#refname-format]
A `refName` must match `^[A-Za-z][A-Za-z0-9_]{0,31}$` — it starts with a letter and contains only letters, digits, and underscores.
Per-Capability Constraints [#per-capability-constraints]
> The generation request is validated per capability. The most common rules:
| Capability | Constraint |
| ------------------- | ---------------------------------------------------------------------------------------------------------------------------------------- |
| `mimic` | `quality` is locked to `720p`. Needs exactly 1 image + 1 video. Video duration, if given, must be 5-30s. |
| `agent` | `quality` must be `720p` or `1080p`; `duration` must be `20`, `30`, or `60`. |
| `agent` `promo_mix` | Needs at least 4 product images. |
| `agent` `ad_master` | Needs at least 1 product image and no video. |
| `multi_transition` | Default `quality` is `360p`. Use `pixverse.multiTransition`; no top-level `images`/`videos`/`audios`. |
| `fusion` | The `prompt` must contain `@refName` for every entry in `pixverse.imageReferences`. |
| `transition` | Exactly 2 images. |
| `restyle` | Requires a source (`sourceTaskId` or `pixverse.sourceVideoId`) plus `pixverse.restyleId`. |
| `lip_sync` | Needs a source video (1 `video` or `sourceTaskId`) plus exactly one audio source — either 1 `audio` (5-60s) or `pixverse.tts`, not both. |
Pricing [#pricing]
PixVerse uses a provider-credit pricing model: ListenHub credits are derived from the provider's quoted cost. Because cost depends on capability, quality, duration, and asset mix, always call `estimate-credits` before `generate` to show the user an accurate cost. Credits are charged when the task is created and refunded automatically if generation fails.
Create PixVerse Task [#create-pixverse-task]
`POST /v1/video-generation/pixverse/generate`
Returns a `taskId` and `episodeId`. Poll [`GET /v1/video-generation/tasks/{taskId}`](/docs/en/openapi/api-reference/ai-video#get-task) until the task is `success` or `failed`.
Text to Video [#text-to-video]
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/video-generation/pixverse/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"capability": "text_to_video",
"model": "pixverse",
"language": "en",
"prompt": "A neon-lit street in the rain, cinematic slow dolly shot",
"quality": "720p",
"aspectRatio": "16:9",
"duration": 5
}'
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/video-generation/pixverse/generate',
{
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
capability: 'text_to_video',
model: 'pixverse',
language: 'en',
prompt: 'A neon-lit street in the rain, cinematic slow dolly shot',
quality: '720p',
aspectRatio: '16:9',
duration: 5,
}),
},
)
const data = await response.json()
console.log('Task ID:', data.data.taskId)
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/video-generation/pixverse/generate',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'capability': 'text_to_video',
'model': 'pixverse',
'language': 'en',
'prompt': 'A neon-lit street in the rain, cinematic slow dolly shot',
'quality': '720p',
'aspectRatio': '16:9',
'duration': 5,
},
)
data = response.json()
print('Task ID:', data['data']['taskId'])
```
Lip Sync [#lip-sync]
Provide one source video (or a `sourceTaskId`) plus exactly one audio source: either one `audios` item or `pixverse.tts`.
**cURL:**
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/video-generation/pixverse/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"capability": "lip_sync",
"quality": "720p",
"videos": [
{ "url": "https://example.com/talking-head.mp4", "duration": 12 }
],
"pixverse": {
"tts": {
"speakerId": "en_male_001",
"content": "Welcome back to the channel. Today we are shipping something new."
}
}
}'
```
**JavaScript:**
```javascript
const response = await fetch(
'https://api.marswave.ai/openapi/v1/video-generation/pixverse/generate',
{
method: 'POST',
headers: {
Authorization: `Bearer ${process.env.LISTENHUB_API_KEY}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
capability: 'lip_sync',
quality: '720p',
videos: [
{ url: 'https://example.com/talking-head.mp4', duration: 12 },
],
pixverse: {
tts: {
speakerId: 'en_male_001',
content:
'Welcome back to the channel. Today we are shipping something new.',
},
},
}),
},
)
const data = await response.json()
console.log('Task ID:', data.data.taskId)
```
**Python:**
```python
import os
import requests
response = requests.post(
'https://api.marswave.ai/openapi/v1/video-generation/pixverse/generate',
headers={'Authorization': f'Bearer {os.environ["LISTENHUB_API_KEY"]}'},
json={
'capability': 'lip_sync',
'quality': '720p',
'videos': [
{'url': 'https://example.com/talking-head.mp4', 'duration': 12}
],
'pixverse': {
'tts': {
'speakerId': 'en_male_001',
'content': 'Welcome back to the channel. Today we are shipping something new.',
}
},
},
)
data = response.json()
print('Task ID:', data['data']['taskId'])
```
**Response**:
```json
{
"code": 0,
"message": "",
"data": {
"taskId": "665f1d4e8b3a3f001234abcd",
"episodeId": "665f1d4e8b3a3f001234abce",
"status": "generating"
}
}
```
Estimate Credits [#estimate-credits]
`POST /v1/video-generation/pixverse/estimate-credits`
Estimate the credit cost before creating a task.
| Parameter | Type | Required | Default | Description |
| -------------------- | ------- | -------- | ---------- | ---------------------------------------------------------------- |
| `capability` | string | Yes | - | One of the nine capabilities. |
| `model` | string | No | `pixverse` | `pixverse`, `v6`, `v5`, or `v4.5`. |
| `language` | string | No | `en` | `en` (international) or `zh` (China). |
| `duration` | integer | No | `5` | 1-60 seconds (`agent`: `20`, `30`, or `60`). |
| `quality` | string | No | `720p` | `360p`, `540p`, `720p`, or `1080p` (`multi_transition`: `360p`). |
| `pixverse.agentType` | string | No | - | `ad_master` or `promo_mix` (required for `agent`). |
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/video-generation/pixverse/estimate-credits" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"capability": "text_to_video",
"model": "pixverse",
"quality": "720p",
"duration": 5
}'
```
**Response**:
```json
{
"code": 0,
"message": "",
"data": {
"tokens": 155520,
"credits": 12
}
}
```
Rate Limit [#rate-limit]
PixVerse generation shares the AI video generation rate limit of **5 RPM** per user on the generate endpoint. Exceeding it returns error `29998` (`429`). Implement exponential backoff on retries.
Error Codes [#error-codes]
| Code | HTTP | Meaning |
| ------- | ----- | -------------------------------------------------------------------------------------------------------------------------- |
| `32001` | `404` | Task not found. |
| `32002` | `402` | Not enough credits. |
| `32003` | `500` | Provider error during generation. |
| `32004` | `400` | Invalid parameters or unsupported capability combination. |
| `32005` | `403` | The task exists but does not belong to the current API user. |
| `32006` | `400` | Audio input requires at least one image or video. |
| `32007` | `429` | Upstream provider throttling or video concurrency-slot exhaustion (distinct from the per-user `29998` request-rate limit). |
| `32008` | `400` | Content rejected by moderation. |
# Seedance (/docs/en/openapi/api-reference/ai-video/seedance)
Seedance runs on the shared video generation endpoint. For the endpoint, request flow, content items, polling, task listing, and error codes, see the [AI Video overview](/docs/en/openapi/api-reference/ai-video). This page covers only what is specific to Seedance.
Models [#models]
| Model | Best for | Rate limit |
| ------------------------ | ---------------------------------- | ---------- |
| `doubao-seedance-2-pro` | Higher-quality Seedance generation | 5 RPM |
| `doubao-seedance-2-fast` | Fast text/image/video generation | 5 RPM |
Pass the model in the `model` field of `POST /v1/video-generation/generate`. `doubao-seedance-2-fast` is the default model when `model` is omitted.
Limits [#limits]
| Limit | `doubao-seedance-2-pro` | `doubao-seedance-2-fast` |
| -------------------- | ------------------------------------------- | ----------------------------- |
| Resolution | `480p`, `720p`, `1080p` | `480p`, `720p` (no `1080p`) |
| Duration | 4-15s | 4-15s |
| Aspect ratios | `16:9`, `4:3`, `1:1`, `3:4`, `9:16`, `21:9` | same as pro |
| Prompt length | up to 500 characters | up to 500 characters |
| `inputVideoDuration` | 2-15s (reference video input) | 2-15s (reference video input) |
> `doubao-seedance-2-fast` does not support `1080p`. Neither Seedance model
> supports the `4:5` or `5:4` aspect ratios — those are HappyHorse-only. Seedance
> text prompts are capped at 500 characters (the shared endpoint allows up to
> 2500, but Seedance models truncate beyond 500).
Pricing [#pricing]
Seedance pricing scales with resolution and duration; `1080p` and longer clips cost more. Reference-video inputs are billed using `inputVideoDuration`. Call `POST /v1/video-generation/estimate-credits` with the Seedance `model`, `resolution`, `duration`, and (for video reference) `hasVideoInput` plus `inputVideoDuration` to get the exact credit cost before generating. Credits are charged on task creation and refunded automatically on failure.
Example [#example]
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/video-generation/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "doubao-seedance-2-pro",
"content": [
{ "type": "text", "text": "A cinematic aerial shot of a quiet coastal city at sunrise" }
],
"resolution": "1080p",
"ratio": "16:9",
"duration": 5,
"generateAudio": true
}'
```
See the [AI Video overview](/docs/en/openapi/api-reference/ai-video#request-parameters) for the full parameter list and the image-to-video / video-reference request shapes.
# Wan 3.0 (/docs/en/openapi/api-reference/ai-video/wan3)
Wan 3.0 runs on the shared video generation endpoint. For the endpoint, request flow, content items, polling, task listing, and error codes, see the [AI Video overview](/docs/en/openapi/api-reference/ai-video). This page covers only what is specific to Wan 3.0.
Models [#models]
| Model | Best for | Rate limit |
| -------------------- | ----------------------------------------------------- | ---------- |
| `wan3.0-video` | Clips up to 30s with natively generated audio | 5 RPM |
| `wan3.0-video-prime` | The same capabilities at a markedly faster turnaround | 5 RPM |
Pass the model in the `model` field of `POST /v1/video-generation/generate`.
Limits [#limits]
| Limit | Wan 3.0 and Wan 3.0 Prime |
| -------------------- | -------------------------------------- |
| Resolution | `480p`, `720p`, `1080p` |
| Duration | 2-30s, whole seconds only |
| Aspect ratios | `16:9`, `4:3`, `1:1`, `3:4`, `9:16` |
| Prompt length | up to 2500 characters |
| Reference images | up to 9 per request |
| `inputVideoDuration` | 1–15s, required with a reference video |
Both models accept `first_frame` and `last_frame`; a `last_frame` is only valid alongside a `first_frame`. Frame roles and `reference_image` cannot be combined in one request. Audio is generated natively, so `generateAudio` defaults to `true` — turning it off does not lower the price. The prompt is optional when you supply a first frame.
> Wan 3.0 does not support the `21:9`, `4:5`, or `5:4` aspect ratios; requests
> using them return `400`. A reference video counts toward the length budget:
> `inputVideoDuration` plus `duration` must not exceed 30s, and billing counts
> that same total. `duration: -1` (automatic duration) is not available. Wan 3.0
> also runs longer than the other families — a 5s `480p` clip takes around five
> minutes.
Pricing [#pricing]
Credits scale with resolution and duration. `wan3.0-video-prime` costs 1.5x the standard model at every tier. The total is rounded up to a whole credit.
`wan3.0-video`:
| Resolution | Credits / second | 5s | 10s | 30s |
| ---------- | ---------------- | --- | --- | --- |
| `480p` | 5.625 | 29 | 57 | 169 |
| `720p` | 11.25 | 57 | 113 | 338 |
| `1080p` | 22.5 | 113 | 225 | 675 |
`wan3.0-video-prime`:
| Resolution | Credits / second | 5s | 10s | 30s |
| ---------- | ---------------- | --- | --- | ---- |
| `480p` | 8.4375 | 43 | 85 | 254 |
| `720p` | 16.875 | 85 | 169 | 507 |
| `1080p` | 33.75 | 169 | 338 | 1013 |
Call `POST /v1/video-generation/estimate-credits` with the Wan 3.0 `model`, `resolution`, and `duration` for the exact cost before generating. Credits are charged on task creation and refunded automatically on failure.
Example [#example]
```bash
curl -X POST "https://api.marswave.ai/openapi/v1/video-generation/generate" \
-H "Authorization: Bearer $LISTENHUB_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "wan3.0-video",
"content": [
{ "type": "text", "text": "The camera pushes in slowly as the city lights come up" },
{ "type": "image_url", "role": "first_frame", "image_url": { "url": "https://example.com/open.jpg" } },
{ "type": "image_url", "role": "last_frame", "image_url": { "url": "https://example.com/close.jpg" } }
],
"resolution": "720p",
"ratio": "16:9",
"duration": 8,
"generateAudio": true
}'
```
See the [AI Video overview](/docs/en/openapi/api-reference/ai-video#request-parameters) for the full parameter list and the text-to-video / image-to-video request shapes.
# SDKs & CLI (/docs/en/tools)
ListenHub ships two official client libraries on top of the [OpenAPI](/docs/en/openapi): a JavaScript/TypeScript **SDK** and a **command-line tool**. Both talk to the same endpoints, unwrap the standard `{ code, message, data }` envelope for you, and handle `429` retries automatically — so you write less plumbing than calling the HTTP API directly.
Pick your tool [#pick-your-tool]
- **JavaScript SDK** -- Typed client for Node and browsers. Use it inside an app, a backend service, or a script. [/docs/en/tools/sdk](/docs/en/tools/sdk)
- **Command-line tool** -- Run podcasts, TTS, images, music, and video from your terminal or a CI job — no code required. [/docs/en/tools/cli](/docs/en/tools/cli)
Install [#install]
**SDK:**
```bash
npm i @marswave/listenhub-sdk
```
ESM-only. Requires Node.js >= 20.
**CLI:**
```bash
npm i -g @marswave/listenhub-cli
```
Installs the `listenhub` binary globally. Requires Node.js >= 20.
Which one should I use? [#which-one-should-i-use]
| You want to… | Reach for |
| -------------------------------------------------------------- | ----------------------------------------------------------------------------- |
| Build a product feature that generates audio, images, or video | **SDK** (`OpenAPIClient` for servers, `ListenHubClient` for user-facing apps) |
| Script a one-off job, batch generation, or a CI/CD step | **CLI** — pipe `--json` output through `jq` |
| Explore endpoints, parameters, and exact response shapes | [OpenAPI reference](/docs/en/openapi) |
| Drive ListenHub from an AI agent or assistant | [MCP server](/docs/en/mcp) |
The SDK and CLI are convenience layers. Anything they do, you can also do with raw HTTP against the OpenAPI — the reference is the source of truth for every endpoint, parameter, and enum.
Two auth models [#two-auth-models]
Both clients support the same two ways to authenticate. Choose based on where the code runs.
* **API key** — for servers, scripts, and CI. Pass the key as `Authorization: Bearer $LISTENHUB_API_KEY`. Create keys at [listenhub.ai/settings/api-keys](https://listenhub.ai/settings/api-keys). In the SDK this is `OpenAPIClient`; in the CLI it is the `listenhub openapi …` command group.
* **OAuth login** — for interactive and user-facing use, where actions run on behalf of a signed-in account. In the SDK this is `ListenHubClient`; in the CLI it is `listenhub auth login`, which opens a browser and stores tokens under `~/.config/listenhub/`.
> Treat API keys as secrets. Keep them server-side — never ship a key in browser or mobile client code. For user-facing apps, use OAuth so each request runs under the user's own account.
```ts
// Server-side, API key
import { OpenAPIClient } from '@marswave/listenhub-sdk';
const client = new OpenAPIClient({ apiKey: process.env.LISTENHUB_API_KEY });
const { items: speakers } = await client.listSpeakers({ language: 'en' });
```
```bash
# Same thing from the terminal
export LISTENHUB_API_KEY="lh_sk_..."
listenhub openapi speakers list --language en --json
```
Error handling at a glance [#error-handling-at-a-glance]
Every response is wrapped in `{ "code": 0, "message": "", "data": { … } }`. A non-zero `code` means an error.
* **SDK** — unwraps `data` on `code 0` and throws `ListenHubError` (with `status`, `code`, and `requestId`) otherwise. On `429`, it reads `Retry-After` and retries up to `maxRetries` (default `2`). `client.api` is a [ky](https://github.com/sindresorhus/ky) escape hatch for endpoints the SDK does not wrap yet.
* **CLI** — prints errors to stderr and uses exit codes: `0` success, `1` error, `2` auth, `3` timeout. Long-running generations poll every 10s; pass `--no-wait` to return the ID immediately or `--timeout
` to bound the wait.
Keep reading [#keep-reading]
- **OpenAPI reference** -- Endpoint-level detail: paths, parameters, enums, and response shapes. [/docs/en/openapi](/docs/en/openapi)
- **listenhub-sdk on GitHub** -- Source, examples, and changelog for the JavaScript SDK. [https://github.com/marswaveai/listenhub-sdk](https://github.com/marswaveai/listenhub-sdk)
- **listenhub-cli on GitHub** -- Source, examples, and changelog for the command-line tool. [https://github.com/marswaveai/listenhub-cli](https://github.com/marswaveai/listenhub-cli)
# Authentication (/docs/en/tools/cli/authentication)
The CLI authenticates two ways, mapped to two command namespaces:
* **OAuth login** — `listenhub auth login` opens your browser, signs you in as a ListenHub user, and stores a refreshable token. Bare commands (`listenhub podcast …`, `listenhub tts …`) run as that user.
* **API key** — a `lh_sk_…` key authenticates the `listenhub openapi …` commands. You set it through an environment variable or a stored config file. This is the mode for servers, scripts, and CI.
The two modes use separate credential files and never interfere with each other. You can have both configured at once.
| | OAuth login | API key |
| ----------- | -------------------------------------- | --------------------------------------------------------- |
| Set up with | `listenhub auth login` | `listenhub openapi config set-key` or `LISTENHUB_API_KEY` |
| Used by | bare commands (`listenhub `) | `listenhub openapi ` |
| Acts as | the signed-in user | the key owner |
| Stored at | `~/.config/listenhub/credentials.json` | `~/.config/listenhub/openapi.json` (or env var) |
| Best for | interactive work on your own machine | scripts, CI/CD, automation |
> Both credential files live under `~/.config/listenhub/`. If `XDG_CONFIG_HOME` is set, the CLI uses `$XDG_CONFIG_HOME/listenhub/` instead. Files are written with `0600` permissions (owner read/write only).
OAuth login [#oauth-login]
Use OAuth when you are working interactively on a machine you control. Nothing long-lived gets baked into a script — the CLI holds a short-lived access token plus a refresh token, and renews automatically.
Log in [#log-in]
```bash
listenhub auth login
```
This runs a one-time browser flow:
1. The CLI starts a temporary callback server on a random local port (`127.0.0.1`) and opens your default browser to the ListenHub login page.
2. You sign in (and authorize, if prompted) in the browser. ListenHub redirects back to the local callback with an authorization code.
3. The CLI exchanges the code for tokens, writes them to `~/.config/listenhub/credentials.json`, and prints the account it logged in as:
```text
✓ Logged in as Ada Lovelace
```
The browser flow has a **5-minute timeout**. If you do not finish signing in within that window, the command aborts with `Login timed out after 5 minutes` — rerun `listenhub auth login` to try again. If the browser does not open on its own, the login URL is printed to the terminal; open it manually.
Check status [#check-status]
```bash
listenhub auth status
```
```text
✓ Logged in as Ada Lovelace
Email: ada@example.com
Expires at: 2026-07-01T12:00:00.000Z
```
`status` calls the API with your current token to confirm it is still valid. Add `--json` for a machine-readable form:
```bash
listenhub auth status --json
```
```json
{
"loggedIn": true,
"user": "Ada Lovelace",
"email": "ada@example.com",
"expiresAt": "2026-07-01T12:00:00.000Z"
}
```
If you are not logged in, or the token has expired and cannot be used, `status` reports that and exits with a non-zero code:
```json
{ "loggedIn": false }
```
Log out [#log-out]
```bash
listenhub auth logout
```
This revokes your refresh token on the server, then deletes the local `credentials.json`:
```text
✓ Logged out
```
If the remote revoke call fails (for example, you are offline), the CLI prints a warning and still clears the local credentials, so the machine is left signed out either way.
Token storage and refresh [#token-storage-and-refresh]
`credentials.json` holds the access token, the refresh token, and an `expiresAt` timestamp. You do not refresh tokens manually — the CLI renews the access token from the refresh token as needed while you run commands. The file is written atomically (temp file then rename) with `0600` permissions.
> Treat `credentials.json` like any other secret. It grants access to your ListenHub account until you run `listenhub auth logout` or the refresh token is revoked.
API key [#api-key]
Use an API key when commands run somewhere you cannot complete a browser flow — CI pipelines, cron jobs, servers. API-key auth drives the `listenhub openapi …` namespace.
Create a key at [listenhub.ai/settings/api-keys](https://listenhub.ai/settings/api-keys). Keys start with `lh_sk_`.
There are two ways to supply the key. **The environment variable always takes precedence over the stored file.**
Environment variable [#environment-variable]
Set `LISTENHUB_API_KEY` in your shell or CI secrets:
```bash
export LISTENHUB_API_KEY="lh_sk_your_key_here"
listenhub openapi speakers list --language en
```
This is the recommended approach for CI/CD: keep the key in your platform's secret store and inject it as an environment variable. Nothing is written to disk.
Stored config [#stored-config]
For repeated local use, store the key once:
```bash
listenhub openapi config set-key
```
The command prompts for the key (input goes to `stderr`, so it stays out of piped output), validates that it starts with `lh_sk_`, and writes it to `~/.config/listenhub/openapi.json` with `0600` permissions. It then echoes a masked confirmation:
```text
✓ API Key saved (lh_sk_***)
```
A key that does not start with `lh_sk_` is rejected before anything is saved:
```text
✗ Invalid API Key format. Must start with "lh_sk_".
```
Inspect and clear [#inspect-and-clear]
Check which key is active and where it comes from:
```bash
listenhub openapi config show
```
```text
✓ API Key configured (source: env)
Key ID: lh_sk_***
```
The `source` is `env` when `LISTENHUB_API_KEY` is set, or `file` when the key comes from `openapi.json`. The full key is never printed — only the masked `lh_sk_***` prefix. Add `--json` for scripting:
```bash
listenhub openapi config show --json
```
```json
{ "source": "env", "keyId": "lh_sk_live" }
```
If no key is configured, `show` reports that and exits non-zero.
Remove the stored key (this clears the file only; it does not unset an environment variable):
```bash
listenhub openapi config clear
```
```text
✓ API Key cleared
```
> An API key is a long-lived secret tied to your account. Never commit it to source control or paste it into shared logs. Prefer `LISTENHUB_API_KEY` from a secret store in CI; use stored config only on machines you control.
Which mode should I use? [#which-mode-should-i-use]
* **Working interactively on your own machine** → OAuth login. You avoid keeping a long-lived key on disk, and commands run as you.
* **Scripts, CI/CD, servers** → API key via `LISTENHUB_API_KEY`. It works without a browser and slots into secret managers.
The two are independent. A common setup is OAuth login for day-to-day terminal work plus an API key in CI — both can be configured on the same machine without conflict.
Troubleshooting auth errors [#troubleshooting-auth-errors]
The CLI uses **exit code `2` for authentication failures**, so scripts can distinguish "not authorized" from other errors (`1` = general error, `3` = timeout). Errors are written to `stderr`.
Common cases and fixes:
| Symptom | Cause | Fix |
| ---------------------------------------------------------------------- | ------------------------------------------------------------------------ | ----------------------------------------------------------------------------------------------------------- |
| `No API Key configured` | Neither `LISTENHUB_API_KEY` nor a stored key is set | Run `listenhub openapi config set-key`, or export `LISTENHUB_API_KEY` |
| `Invalid API Key format. Must start with "lh_sk_"` | The key you entered has the wrong prefix | Copy a fresh key from [settings/api-keys](https://listenhub.ai/settings/api-keys); keys start with `lh_sk_` |
| `Not logged in (token expired or invalid)` from `auth status` | OAuth token expired or was revoked | Run `listenhub auth login` again |
| An `openapi` command fails with an auth error despite `config set-key` | `LISTENHUB_API_KEY` is set to a stale/wrong value and overrides the file | `unset LISTENHUB_API_KEY` (env wins over stored config), or fix the variable |
| `Login timed out after 5 minutes` | Browser flow not completed in time | Rerun `listenhub auth login` and finish signing in promptly |
To confirm what the CLI currently sees:
```bash
listenhub auth status # OAuth session
listenhub openapi config show # API key source (env vs file)
```
Next steps [#next-steps]
- **CLI overview** -- Install, the two auth modes at a glance, global flags, and exit codes. [/docs/en/tools/cli](/docs/en/tools/cli)
- **Quickstart** -- Install, authenticate, and create your first episode from the terminal. [/docs/en/tools/cli/quickstart](/docs/en/tools/cli/quickstart)
- **OpenAPI commands** -- Every listenhub openapi command for scripts and CI, keyed off your API key. [/docs/en/tools/cli/openapi-commands](/docs/en/tools/cli/openapi-commands)
# OAuth Commands (/docs/en/tools/cli/commands)
This page documents the OAuth command set: the `listenhub ...` commands that act as your signed-in user account. They require a browser login (`listenhub auth login`) and read tokens from `~/.config/listenhub/credentials.json`. For the API-key command set used in scripts and CI, see [OpenAPI commands](/docs/en/tools/cli/openapi-commands).
Conventions [#conventions]
These behaviors apply across the commands below.
* **Global flags.** Every command accepts `--json` / `-j` (machine-readable output on `stdout`, errors on `stderr`) and `--help` / `-h`. Creation commands also accept `--no-wait` (return the ID immediately without polling) and `--timeout ` (cap how long polling waits; the default varies per command).
* **Polling.** Creation commands submit a job, then poll status every 10 seconds until it reaches a terminal state. On timeout the command exits with code `3`; the job keeps running server-side and you can fetch it later by ID.
* **Language auto-detection.** Where a command has `--lang` and you omit it, the CLI infers the language from your input text: Kana → `ja`, other CJK characters → `zh`, otherwise `en`.
* **Speaker resolution.** `--speaker ` is resolved to an inner ID by listing speakers for the detected language; `--speaker-id ` is passed through directly. If you supply neither, the CLI picks a default voice for the detected language.
* **File vs. URL auto-detect.** Flags that accept `` auto-detect their input: an `http(s)` URL is passed through unchanged, while a local path is validated (extension and size) and uploaded to cloud storage before the API call. Supported uploads — audio: `.mp3`, `.wav`, `.flac`, `.m4a`, `.ogg`, `.aac` (max 20 MB); image: `.jpg`, `.jpeg`, `.png`, `.webp`, `.gif` (max 10 MB); video: `.mp4`, `.mov` (max 50 MB). Some Mureka music subcommands accept local files only (no URL) with their own limits, noted per command.
* **Exit codes.** `0` success, `1` error, `2` authentication required or invalid, `3` timeout.
> Generation consumes credits. The OAuth command set has no per-command credit estimator except `video estimate`. Before generating, check your remaining balance with `listenhub openapi subscription`, and use `listenhub openapi video estimate` (or `listenhub video estimate`) for video cost. Never assume a fixed cost — query it.
auth [#auth]
Manage your login session.
```bash
listenhub auth login
listenhub auth logout
listenhub auth status [-j]
```
| Command | Description |
| -------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| `login` | Open the browser to complete OAuth. On success, writes tokens to `~/.config/listenhub/credentials.json` (mode `0600`). Tokens refresh automatically. |
| `logout` | Revoke tokens and remove the stored credentials. |
| `status` | Show the current login state. Accepts `-j`. |
```bash
listenhub auth login
listenhub auth status
```
podcast [#podcast]
Generate a podcast episode from a topic and/or reference sources.
```bash
listenhub podcast create [options]
listenhub podcast list [options]
```
podcast create [#podcast-create]
| Flag | Values | Default | Meaning |
| ---------------------- | ------------------------- | ------- | --------------------------------------------------------------- |
| `--query ` | string | — | Topic or prompt for the episode. |
| `--source-url ` | URL (repeatable) | `[]` | Reference URL to ground the episode. Repeat for multiple. |
| `--source-text ` | string (repeatable) | `[]` | Reference text to ground the episode. Repeat for multiple. |
| `--mode ` | `quick`, `deep`, `debate` | `quick` | Generation mode. |
| `--lang ` | `en`, `zh`, `ja` | auto | Output language. Auto-detected from `--query` if omitted. |
| `--speaker ` | string (repeatable) | — | Speaker by name. One speaker → solo; two or more → multi-voice. |
| `--speaker-id ` | string (repeatable) | — | Speaker by inner ID. Use instead of `--speaker`. |
| `--no-wait` | flag | poll | Return the episode ID immediately without polling. |
| `--timeout ` | number | `300` | Polling timeout. |
| `--json`, `-j` | flag | `false` | JSON output. |
```bash
listenhub podcast create --query "AI agent trends in 2026" --mode quick
```
podcast list [#podcast-list]
| Flag | Values | Default | Meaning |
| ----------------- | ------ | ------- | --------------- |
| `--page ` | number | `1` | Page number. |
| `--page-size ` | number | `20` | Items per page. |
| `--json`, `-j` | flag | `false` | JSON output. |
```bash
listenhub podcast list --page 1 --page-size 20
```
tts [#tts]
Convert text to speech in one voice.
```bash
listenhub tts create [options]
listenhub tts list [options]
```
tts create [#tts-create]
| Flag | Values | Default | Meaning |
| ---------------------- | ------------------- | ------- | --------------------------------------------------------------- |
| `--text ` | string | — | Text to convert to speech. |
| `--source-url ` | URL (repeatable) | `[]` | Reference URL. Repeat for multiple. |
| `--source-text ` | string (repeatable) | `[]` | Reference text. Repeat for multiple. |
| `--mode ` | `smart`, `direct` | `smart` | `smart` rewrites the input for speech; `direct` reads it as-is. |
| `--lang ` | `en`, `zh`, `ja` | auto | Output language. Auto-detected from `--text` if omitted. |
| `--speaker ` | string | — | Speaker by name. |
| `--speaker-id ` | string | — | Speaker by inner ID. |
| `--no-wait` | flag | poll | Return the ID immediately without polling. |
| `--timeout ` | number | `300` | Polling timeout. |
| `--json`, `-j` | flag | `false` | JSON output. |
```bash
listenhub tts create --text "Hello, world" --lang en
```
tts list [#tts-list]
| Flag | Values | Default | Meaning |
| ----------------- | ------ | ------- | --------------- |
| `--page ` | number | `1` | Page number. |
| `--page-size ` | number | `20` | Items per page. |
| `--json`, `-j` | flag | `false` | JSON output. |
```bash
listenhub tts list
```
voice-clone [#voice-clone]
Clone your own voice from reference audio using the logged-in account, then manage the private voices it produces. Upload mode only — the interactive recording flow lives in the web app. Languages: `zh` and `en`.
Confirming a clone is free within your plan's per-period quota; beyond it each confirmation costs 300 credits and only happens when you pass `--use-credits`.
| Command | Description |
| --------------------------------- | ----------------------------------------------------------- |
| `voice-clone create` | Upload 1–6 reference audio files and create a clone task. |
| `voice-clone get ` | Fetch a task status. |
| `voice-clone confirm` | Confirm a finished task into a private voice. |
| `voice-clone speakers` | List private voices with quota and remaining confirmations. |
| `voice-clone speaker ` | Fetch one private voice. |
| `voice-clone update ` | Rename a voice or change its gender. |
| `voice-clone delete ` | Delete a voice and free one slot. |
`voice-clone create` options:
| Option | Default | Description |
| ---------------------------------------------------- | -------- | -------------------------------- |
| `--file ` | required | 1–6 local reference audio files. |
| `--lang ` | required | `zh` or `en`. |
| `--no-wait`, `--timeout ` (`600`), `--json` | — | Standard async flags. |
`voice-clone confirm` takes `--task-id `, `--name ` (max 50 chars), `--gender `, and optional `--use-credits`. `voice-clone update ` takes `--name` and/or `--gender` (at least one).
```bash
# Clone, then confirm what you heard
listenhub voice-clone create --file ./reference.mp3 --lang en
listenhub voice-clone confirm \
--task-id 6915bde9cca4d3c8ecb3eaf5 --name "My Voice" --gender female
# The speaker ID from `speakers` works anywhere a voice is expected
listenhub voice-clone speakers
listenhub tts create --text "Hello from my own voice." --speaker-id voice-clone-6915bde9cca4d3c8ecb3eaf5
```
explainer [#explainer]
Generate an explainer video (narrated visual segments).
```bash
listenhub explainer create [options]
listenhub explainer list [options]
```
explainer create [#explainer-create]
Audio narration is on by default; pass `--skip-audio` to produce a silent video.
| Flag | Values | Default | Meaning |
| ------------------------ | --------------------- | ------- | --------------------------------------------------------- |
| `--query ` | string | — | Topic or prompt. |
| `--source-url ` | URL (repeatable) | `[]` | Reference URL. Repeat for multiple. |
| `--source-text ` | string (repeatable) | `[]` | Reference text. Repeat for multiple. |
| `--mode ` | `info`, `story` | `info` | Generation mode. |
| `--lang ` | `en`, `zh`, `ja` | auto | Output language. Auto-detected from `--query` if omitted. |
| `--speaker ` | string | — | Speaker by name. |
| `--speaker-id ` | string | — | Speaker by inner ID. |
| `--skip-audio` | flag | `false` | Skip audio narration (silent video). |
| `--image-size ` | `2K`, `4K` | `2K` | Rendered image resolution. |
| `--aspect-ratio ` | `16:9`, `9:16`, `1:1` | `16:9` | Frame aspect ratio. |
| `--style